要点速览
- 单个 vllm serve 同时做 prefill、decode 与 CPU 解析三件事:长 prompt 的 prefill 会卡住同 GPU 上所有 decode 流,ITL 尾延迟飙升。
- P/D 分离买到的是 goodput(同时满足 TTFT 与 ITL 目标的请求速率)而非峰值吞吐;前提是 KV cache 传输够快,否则每个首 token 都为传输买单。
- GPU-less 前端(/render、/derender)把模板、tokenization 与 reasoning/tool 解析移到纯 CPU 机器;引擎 tokens-only 运行,render 层无状态、按 CPU 独立扩缩容。
- 给出 NIXL 三进程端到端示例与关键参数(kv_lease_duration、kv_load_failure_policy),并强调压测前先检查 KV 传输(p2p 拓扑与 KV Transfer metrics)。
- 多轮对话可用 bidirectional_kv_xfer 避免重算历史 KV;但 reasoning 模型的 thinking trace 被 chat template 丢弃时,会得到错误输出而非慢输出。
解决什么问题
一个 vllm serve 进程让计算密集的 prefill、访存密集的 decode 与纯 CPU 的模板/解析工作互相干扰:长 prompt 的 prefill 会阻塞同一 GPU 上所有 decode 流,而 chat 模板、tokenization、reasoning/tool 解析等 CPU 工作又跑在为加速器付费的机器上。文章回答什么时候值得把这些阶段拆开部署、如何在 vLLM v0.31.0+ 上端到端跑起来,以及拆分后引入的 KV cache 传输这一新瓶颈如何评估与处理。
核心思路
把 LLM 推理切成可独立扩展的层:prefill 与 decode 作为两个实例,KV cache 经 KV connector(如 NIXL)传输;模板与解析移到无 GPU 的 render tier,引擎以 tokens-only 模式运行,多个分离维度可组合成四层流水线。文章用两块 L40S 上的对照实验说明收益体现在 goodput 与 ITL 尾延迟而非峰值吞吐,并给出生产环境的决策表、可复制的运行命令与遗留问题清单。最后引用 MoRI-IO、llm-d 等第三方数据说明传输够快时的收益上限。
关键要点
- 一个进程、三份互相干扰的工作 — Prefill 一次性读入整个 prompt,受算力限制,决定 TTFT;decode 每步只产出一个 token,瓶颈在读模型权重的显存带宽,决定 ITL。两者共享一块 GPU 时,长 prefill 会让所有 decode 流停顿,这正是并发一上来就出现流式卡顿的原因。第三份工作是 chat 模板、tokenization、detokenization 与 reasoning/tool 解析等纯 CPU 任务,更隐蔽,却跑在租来跑加速器的机器上。
- 多个可组合的分离维度 — 核心维度是 prefill/decode 拆成两个实例,之间传 KV cache(prompt 每个 token 的 attention keys/values,decode 生成前必须拿到)。前端也可整体移出 GPU 机器:/render 把 OpenAI 请求转成 token IDs,/derender 把输出 token IDs 还原成带 content/reasoning/tool_calls 拆分的响应。更广的维度还包括多模态的 encoder disaggregation、MoE 模型的 AFD 插件(attention 与 FFN 分离),以及带 Mamba 状态传输的 hybrid SSM 模型 P/D。
- 收益是 goodput 与尾延迟,不是峰值吞吐 — 没有延迟目标时,把同样的 GPU 拆成 prefill/decode 池未必提升 tokens/s;真正买到的是同时满足 TTFT 与 ITL 目标下能支撑的请求速率。两层可用不同并行度分别调优(prefill 偏 TP,decode 按 batch 尺寸),互不拖累;decode 实例只跑 decode batch,尾延迟随负载上升保持平稳,不像 chunked prefill 那样要随流量反复调 chunk 大小。代价是要运维三四个服务,且 KV 传输成为新的故障模式,很多部署继续用 collocated 才是对的。
- KV cache 传输是第一瓶颈,先检查再压测 — KV cache 很大:Llama-3.1-70B BF16 每 token 320 KiB,10k token prompt 约 3 GB。跨机走 RDMA(InfiniBand/RoCE),机内走 NVLink 或 GPU P2P。作者测试用的 L40S 无 P2P,8k prompt 约 470 MB KV 用了约 1.3 s 传完,而且带宽解释不了这么慢,大头是拷贝周边的开销,包括 decode 只在自己的 forward 步之间轮询才发现传输完成。诊断方法:单机看 nvidia-smi topo -p2p r 是否为 OK,再逐个发长 prompt 读 decode 的 KV Transfer metrics,若 Avg xfer time 是数百毫秒应先修传输。
- 端到端运行 P/D:NIXL 三进程与关键参数 — prefill 与 decode 各起一个 vllm serve,分别配 NixlConnector 的 kv_producer/kv_consumer 角色,再起一个示例 proxy(仅适合开发,生产用 llm-d 或 Dynamo)。proxy 对每个请求先以 max_tokens=1 加 do_remote_decode 调 prefill,prefill 算出 KV cache 并持有 block,返回指向它们的 kv_transfer_params;proxy 再把原请求连同这些参数发给 decode,decode 经 NIXL 拉取 block 后开始生成。三个关键设置:VLLM_NIXL_SIDE_CHANNEL_PORT 在同一主机上每个 worker 必须唯一;kv_lease_duration(默认 30s)控制 prefill 等 decode 取 block 的时长,高负载下主要调它;kv_load_failure_policy 决定传输失败时 fail(默认,报错)还是 recompute(decode 自己重算,慢但请求能活)。
- 多轮对话:双向 KV 传输与 reasoning 模型陷阱 — 标准 P/D 只单向传 KV,第二轮 prefill 仍要重算 decode 刚生成的回答。两个实例都开启 bidirectional_kv_xfer 后,prefill 改为从 decode 拉回那些 block,只计算新 token;由 proxy 按 conversation_id 追踪哪些 block 属于哪个会话。对 reasoning 模型有一个警告:decode 的 block 含它生成的 thinking trace,若下轮 prompt 的 chat template 把它们丢掉(如 Qwen3 默认行为),prefill 的 prompt 与 decode 的 block 不再对齐,得到的是错误输出而非慢输出,且 vLLM 目前检测不到该不匹配(#43094),开启前必须检查 chat template。
- GPU-less 前端:无状态扩展、配置同步与线程池 — render tier 不保存任何 per-request 状态:流式时靠客户端在每个 chunk 回传 stream_state、prompt_token_ids 与 chat_request,因此任意 render 副本可处理任意 chunk,可像普通无状态 Web 服务一样挂负载均衡、按 CPU 独立扩缩。render、derender 与引擎必须在 model、tokenizer、chat template 与 parser 参数(--chat-template、--reasoning-parser、--tool-call-parser 等)上保持一致,不匹配不会报错,只会返回与 vllm serve 不同的 content/reasoning/tool_calls 拆分。--renderer-num-workers 默认为 1,纯渲染很便宜(9k token prompt 约 15 ms CPU),但带 parser 的流式回放开销大得多,需按并发解析流调大 worker 数或加副本。
- 四层组合、生态与遗留问题 — 两个拆分可同时上:四个层级只需三个服务器,因为 /inference/v1/generate 与 /v1/chat/completions 一样接受 kv_transfer_params,由你的代码(或 llm-d、Dynamo)扮演 proxy 串起 render→prefill→decode→derender 四跳。生态上,llm-d、NVIDIA Dynamo、KServe、vLLM production-stack、AIBrix 都已落地分离式服务,decode 侧甚至可以不是 vLLM(TileRT)。遗留问题包括:带 parser 的流式 derender 是 O(n³) 字符级工作;parser 路径每个 chunk 全量重发 prompt_token_ids,100k prompt 配 1k 输出时 prompt 占请求体约 99%;batch derender 的 finish_reason 与 tool call ID 存在正确性缺口;logprobs 只返回占位字符串。
关键数据
| 指标 | 数值 | 条件 |
|---|---|---|
| KV cache 体积(Llama-3.1-70B) | 320 KiB/token;10k token prompt 约 3 GB,400 Gb/s 线速下约 65 ms | Llama-3.1-70B,BF16 精度,不计任何开销的理论传输时间 |
| collocated 与 P/D 的 p99 ITL 对比 | collocated p99 从 23 ms 跳到 169 ms(0.4 req/s),2 req/s 时达 263 ms;P/D p99 始终在 25–52 ms | 2×NVIDIA L40S(48 GB,PCIe,无 NVLink),Qwen2.5-7B-Instruct,约 8k token prompt、256 输出 token、每速率 100 个 Poisson 请求,前缀缓存关闭;P/D 为 1 prefill + 1 decode 经 NIXL |
| p99 ITL 差距倍数 | collocated p99 约为 P/D 的 6 倍 | 0.4–0.6 req/s 区间,两配置中位 ITL 相同(21–24 ms)的前提下 |
| goodput 提升(MoRI-IO 单机基准) | 73/100 vs 30/100 请求同时满足 1 s TTFT 与 50 ms ITL,约 2.4× goodput | Qwen3-235B-A22B-FP8,单节点 8×MI300X,8 req/s,P/D 与 collocated 同硬件对比 |
| 集群规模端到端延迟降低(llm-d P/D 指南) | 平均端到端延迟约降低 59%,P95 约降低 67% | gpt-oss-120b,16×H200,与同样 GPU 作为聚合副本运行相比 |
| 无 P2P 链路上的 KV 传输耗时 | 约 470 MB KV cache 传输约 1.3 s(56 KiB/token) | 2×L40S(无 peer-to-peer,nvidia-smi topo -p2p r 报 NS),Qwen2.5-7B,8k token prompt |
| 慢速 KV 传输下的 TTFT | P/D 中位 TTFT 2.2 s,collocated 0.7 s | 0.2 req/s,2×L40S 无 P2P,Qwen2.5-7B,8k prompt;P/D 在所有速率都未达到 2 s TTFT 目标,尽管 ITL 尾延迟保持平稳 |
| render 层 CPU 开销与单机容量 | 9k token chat prompt 约 15 ms CPU;单 render 服务默认配置约 73 req/s,仅用略多于一个核 | Qwen2.5-7B 的模板+tokenization,与 GPU 测试同一台机器;在 collocated 尾延迟崩溃的 0.4 req/s 处,渲染不足一个核的 1% |
| 带 parser 的流式 derender 开销 | 约 9× 于进程内解析的 CPU,匹配负载下 E2E p50 +15% | 数千 token 的 reasoning 输出流式经 derender 回放;缓存层已排期(#57571) |
“Llama-3.1-70B in BF16 stores 320 KiB per token, so a 10k-token prompt hands decode about 3 GB.”
“Collocated p99 jumps from 23 ms to 169 ms at 0.4 req/s and reaches 263 ms at 2 req/s. P/D p99 stays between 25 and 52 ms.”
“At 0.4–0.6 req/s the medians match and the collocated p99 is about six times higher.”
前置知识
prefill 与 decode 两阶段的特性差异:计算密集 vs 访存密集 · KV cache 的作用及其随 prompt 长度增长的体积量级 · TTFT、ITL/TPOT、goodput 等 LLM 服务指标的含义 · vllm serve 基本用法与 OpenAI 兼容 API(chat/completions) · GPU 互连与网络基础:PCIe、NVLink、P2P、RDMA/InfiniBand/RoCE · chunked prefill 与 prefix caching 机制的作用
术语表
Prefill/Decode disaggregation (P/D): 把推理的 prefill 与 decode 阶段拆到不同实例/资源池、通过传输 KV cache 衔接的服务架构。KV cache: 注意力层为每个 prompt token 计算并缓存的 keys/values;decode 在产出任何 token 前必须先拿到它。KV connector: vLLM 中在实例间搬运 KV cache 的插件接口,上游已有十余种实现,包括 NIXL、LMCache、Mooncake、FlexKV、AMD MoRI-IO 及可串联的 MultiConnector。NIXL: 常用的 KV 传输后端(vLLM 对应 NixlConnector),通常走 RDMA;需要为每个 worker 配置独立的 side channel 端口。Goodput: 在请求同时满足 TTFT 与 ITL 目标前提下能支撑的请求速率,比峰值吞吐更贴近 SLO 视角的收益指标。TTFT / ITL: Time To First Token(首 token 延迟,由 prefill 决定)与 Inter-Token Latency(token 间延迟,由 decode 决定)。Render / Derender: GPU-less 前端的两端:/render 把 OpenAI 请求渲染成 token IDs,/derender 把输出 token IDs 还原成带 content/reasoning/tool_calls 拆分的响应。Tokens-only 引擎: vLLM 以 token IDs 为输入输出的运行模式(--tokens-only),引擎不再需要 chat 模板与解析器。Bidirectional KV transfer: P/D 双向传输 KV 的模式:多轮对话中 prefill 从 decode 拉回已生成部分的 KV,只计算新增 token。Chunked prefill: 把长 prompt 切块分次 prefill 以降低对 decode 的干扰,但最优 chunk 大小依赖流量特征,需要反复调。kv_lease_duration: prefill 侧持有 KV block 等待 decoder 取走的时长,默认 30 秒,高负载下是主要调优对象。kv_load_failure_policy: KV 传输失败时的策略:fail(默认)让请求报错,recompute 让 decode 自行重算缺失的 KV,慢但请求能存活。
Taking vLLM Apart: A Practical Guide to Disaggregated Serving
A single vllm serve process does three jobs that get in each other's way: processing prompts (prefill), generating tokens (decode) and a pile of CPU work around them. Disaggregated serving in vLLM separates the different stages of LLM inference. Splitting prefill from decode stops long prompts stalling everyone else's output, as long as the KV cache moves between them fast. Moving tokenization and parsing to a CPU-only frontend (/render, /derender) takes that work off your GPU nodes and leaves the engine working purely in token IDs. This post covers when each split or separation is worth using, how to run it with vLLM v0.31.0 or later, and the key gaps and improvements still ahead.
One Server Doing Three Unrelated Jobs
Start a plain vllm serve and you get one process handling three workloads that have nothing in common.
One long prompt arrives while dozens of requests are mid-response and every one of those streams stutters until it's processed. It's the spike you see the moment concurrency goes up. The cause is two phases with little in common sharing one GPU. Prefill reads the whole prompt in one pass, is limited by compute and sets your time to first token (TTFT). Decode is the opposite. It produces one token at a time and what holds it back is how fast the GPU can read the model weights from memory which sets your inter-token latency (ITL). Put them on the same GPU and every decode stream waits while a long prefill runs.
The third job however is quieter and easier to miss. Chat templating, tokenization, detokenization, reasoning parsing, tool call parsing. All pure CPU work running on a box you're renting for its accelerators.
Disaggregation is the obvious response: stop making one process do all of it. If you want the vLLM engine level picture before you go further, Inside vLLM covers how the scheduler mixes prefill and decode today and has a short section on P/D.
The Dimensions
vLLM offers several points where work can be split and they can be combined.
Prefill and decode run as two instances. What passes between them is the KV cache: the attention keys and values for every prompt token which decode needs before it can emit anything. It's big. Llama-3.1-70B in BF16 stores 320 KiB per token, so a 10k-token prompt hands decode about 3 GB. That's roughly 65 ms at a 400 Gb/s line rate before any overhead and all of it lands on TTFT. A KV connector moves it, usually over RDMA. There are more than a dozen connectors upstream now, including NIXL, LMCache, Mooncake, FlexKV and AMD's MoRI-IO, plus a MultiConnector that chains them.
The frontend comes off the GPU box entirely. /render turns an OpenAI request into token IDs, the engine runs token-in / token-out and /derender turns the output token IDs back into a proper OpenAI response with content, reasoning and tool_calls split out. That last leg only landed recently and it completes the round trip.
Beyond P/D, there's encoder disaggregation for multimodal and the AFD plugin for splitting attention from FFN in MoE models. Both use the same idea at a different point in the model. P/D itself now also covers hybrid SSM models with Mamba state transfer included.
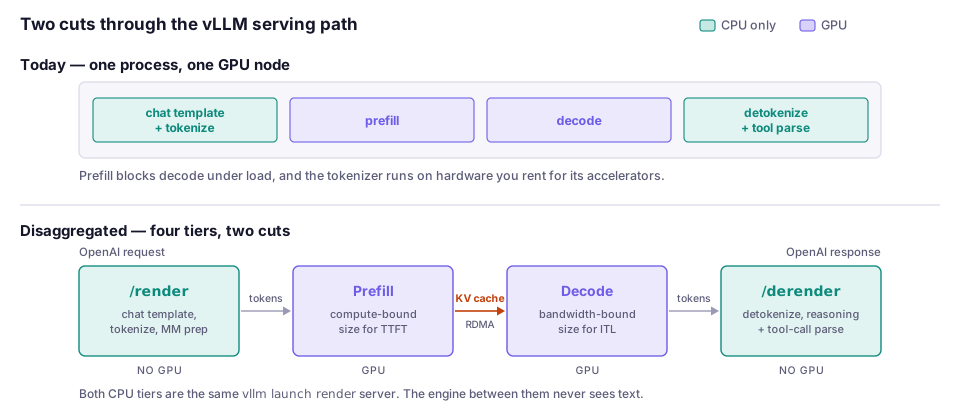
Figure 1. One process doing everything, versus the same pipeline cut into four tiers.
What It Buys You and What It Costs
The pitch isn't peak throughput. With no latency target, splitting the same GPUs into prefill and decode pools won't necessarily move more tokens per second. What it buys is goodput: the request rate you can sustain while requests still meet both their TTFT and ITL targets.
You can tune TTFT and ITL independently. Different parallelism on each tier, sized for the phase it's running. Prefill can be TP-heavy, decode can be sized for batch. Neither change drags the other one with it.
Tail latency stays low as load climbs. A decode instance that only runs decode batches never has a long prefill stall its streams. Chunked prefill gets you partway there, but the right chunk size depends on the traffic, so you end up retuning it.
This was measured on one box with two NVIDIA L40S GPUs (48 GB, PCIe, no NVLink): Qwen2.5-7B-Instruct, ~8k-token prompts, 256 output tokens, 100 Poisson-arrival requests per rate, prefix caching off. Collocated is one vllm serve --data-parallel-size 2, so both setups get the same two GPUs. That isn't the strongest collocated baseline because DP ranks can hold each other up and two independent replicas behind a load balancer might do a little better. P/D is one prefiller and one decoder over NIXL behind the example proxy.
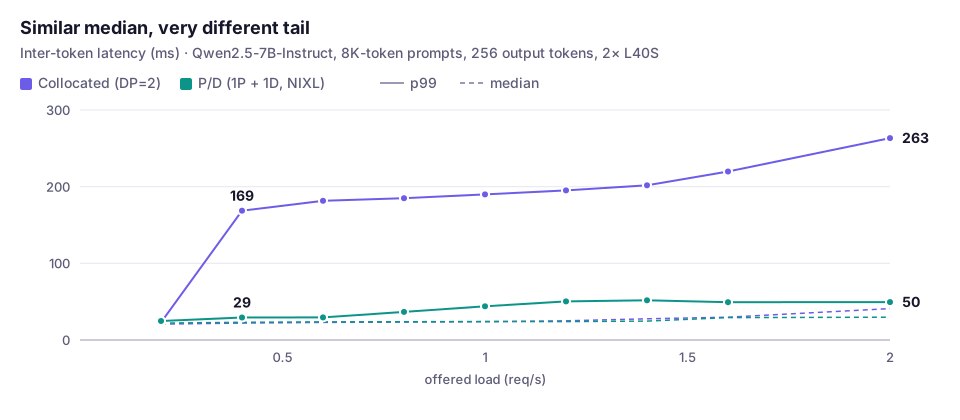
Figure 2. Median ITL is 21–24 ms in both setups up to 1 req/s. At 0.4 req/s, collocated p99 jumps to 169 ms while P/D holds at 29 ms and never exceeds 52 ms.
At 0.4–0.6 req/s the medians match and the collocated p99 is about six times higher. That's 8k-token prefills landing on a GPU that's also decoding and stalling every stream on it until they finish. P/D keeps them off the decode GPU entirely.
Goodput goes up when the transfer is fast. AMD's single-node MoRI-IO benchmark ran Qwen3-235B-A22B-FP8 at 8 req/s on one 8-GPU MI300X node. 73 of 100 requests met both a 1 s TTFT and a 50 ms ITL target, against 30 of 100 for collocated serving. That's about 2.4× the goodput on the same hardware. At cluster scale, llm-d's P/D guide reports about 59% lower mean end-to-end latency and 67% lower P95 for gpt-oss-120b on 16 H200s, compared with the same GPUs run as aggregated replicas.
Every first token pays for the transfer. Those results assume the KV cache moves fast: RDMA over InfiniBand or RoCE between nodes, NVLink or GPU peer-to-peer within one. Our test box had neither. The L40S pair can't do peer-to-peer copies (nvidia-smi topo -p2p r reports NS) and each 8k prompt's ~470 MB of KV cache (56 KiB per token for Qwen2.5-7B) took about 1.3 s to reach decode. At 0.2 req/s, P/D median TTFT was 2.2 s against 0.7 s collocated, so it missed a 2 s TTFT target at every rate even though its ITL tail stayed flat. Bandwidth alone doesn't explain 1.3 s. Even staged through host memory, PCIe 4.0 should move that in tens of milliseconds. Most of it is overhead around the copy, including decode only noticing a finished transfer when it polls between its own forward steps.
So check the transfer before you benchmark anything else. On one box, nvidia-smi topo -p2p r should say OK between your prefill and decode GPUs. Then send a few long prompts one at a time and read decode's KV Transfer metrics line. If Avg xfer time is in the hundreds of milliseconds, fix that first.
The CPU tier is cheap. Once tokenization and parsing move off the GPU box, you scale them against CPU load instead of buying accelerator time to run a tokenizer. Long prompts, multimodal preprocessing and reasoning or tool parsing are where the render tier does real work and none of it needs a GPU. On the same box, templating and tokenizing a 9k-token chat prompt for Qwen2.5-7B cost about 15 ms of CPU. One render server with default settings topped out at 73 req/s using just over one core. At the 0.4 req/s where collocated's tail fell apart, rendering is under 1% of one core.
The catch: you now operate three or four services instead of one and the KV transfer is a new failure mode. Collocated is still the right answer for plenty of deployments.
| Your situation | Recommendation |
|---|---|
| ITL p99 misses your SLO under production load | Disaggregate. This is the main use case. |
| Long prompts at high concurrency | Disaggregate, if your KV transfer is fast. Prefill interference is worst here. |
| Chat or agent loops over a growing context | Disaggregate, with bidirectional transfer (below). Pair it with KV offloading or a shared KV cache such as LMCache or Mooncake. |
| Templating, tokenizing or parsing shows up in your GPU nodes' CPU profile | Split off the render tier. |
| TTFT is the binding constraint | Stay collocated or measure first. The transfer lands on every first token. |
Your KV transfer is slow (check decode's KV Transfer metrics) |
Fix it or stay collocated. It lands on TTFT and caps throughput. Check the fabric too, since a misconfigured network usually slows collectives as well. |
| Low, bursty or latency-insensitive traffic | Stay collocated. |
Running Prefill/Decode
Everything from here on assumes vLLM v0.31.0 or later. The examples use Qwen3-0.6B because it loads fast. That's fine for checking the wiring but it's too small to show a P/D benefit, so benchmark with a larger model (see Where to start).
Three processes: prefiller, decoder, proxy.
# Prefiller on GPU 0
CUDA_VISIBLE_DEVICES=0 UCX_NET_DEVICES=all VLLM_NIXL_SIDE_CHANNEL_PORT=5600 \
vllm serve Qwen/Qwen3-0.6B --port 8100 \
  --kv-transfer-config '{"kv_connector":"NixlConnector","kv_role":"kv_producer"}'

# Decoder on GPU 1
CUDA_VISIBLE_DEVICES=1 UCX_NET_DEVICES=all VLLM_NIXL_SIDE_CHANNEL_PORT=5601 \
vllm serve Qwen/Qwen3-0.6B --port 8200 \
  --kv-transfer-config '{"kv_connector":"NixlConnector","kv_role":"kv_consumer"}'

# Proxy
python tests/v1/kv_connector/nixl_integration/toy_proxy_server.py --port 8192 \
  --prefiller-hosts localhost --prefiller-ports 8100 \
  --decoder-hosts localhost --decoder-ports 8200
The proxy is what ties them together. For each request it calls prefill first, with max_tokens=1 and kv_transfer_params: {"do_remote_decode": true}. Prefill computes the KV cache, holds the blocks and returns kv_transfer_params that point at them. The proxy then forwards the original request to decode with those params attached and decode pulls the blocks over NIXL before it generates.
Point your client at 8192 and it looks like any other OpenAI endpoint. The proxy in tests/ is an example that's fine for development but not for production. For production, look at llm-d or Dynamo.
Three settings worth knowing early. VLLM_NIXL_SIDE_CHANNEL_PORT must be unique per worker on a host. kv_lease_duration (set in kv_connector_extra_config, default 30s) controls how long the prefiller holds blocks waiting for the decoder to collect them. Under load, that's the timeout you'll be tuning. And kv_load_failure_policy decides what happens when a transfer fails: fail, the default, errors the request, while recompute has decode recompute the missing KV itself. Slower, but the request survives.
One easy win if you're running P/D on /v1/chat/completions: the prefill stage already tokenized the prompt, so the decode stage doesn't need to do it again. Ask for return_token_ids on prefill, then hand the IDs to decode through kv_transfer_params. This is the same two step call the proxy makes and the token IDs are the only new part:
from openai import OpenAI

MODEL = "Qwen/Qwen3-0.6B"
messages = [{"role": "user", "content": "What is 17 * 23?"}]

prefill_client = OpenAI(base_url="http://localhost:8100/v1", api_key="EMPTY")
decode_client = OpenAI(base_url="http://localhost:8200/v1", api_key="EMPTY")

prefill = prefill_client.chat.completions.create(model=MODEL, messages=messages, max_tokens=1,
    extra_body={"return_token_ids": True, "kv_transfer_params": {"do_remote_decode": True}})

# prefill's kv_transfer_params point decode at its blocks; add the token IDs on top
decode = decode_client.chat.completions.create(model=MODEL, messages=messages, stream=True,
    extra_body={"kv_transfer_params": {**prefill.kv_transfer_params,
                                       "prompt_token_ids": prefill.prompt_token_ids}})
Once it works, sizing it is the hard part. The Qwen3.8-2.4T PD post walks through picking prefill and decode topologies from KV cache capacity up.
Multi-Turn: Stop Recomputing the Conversation
Standard P/D moves the cache one way which is wasteful for chat and agent loops. On turn two, decode still holds KV for the answer it just generated but prefill has never computed it, so prefill recomputes it. With bidirectional_kv_xfer set on both instances, prefill pulls those blocks back from decode instead and computes only the new tokens. A proxy tracks which blocks belong to which conversation, keyed by a conversation_id the client sends. The bi-directional KV transfer post covers setup, tuning and benchmarking in depth.
One warning for reasoning models. Decode's blocks include the thinking traces it generated. If the next turn's prompt drops them, as Qwen3's chat template does on its own, prefill's prompt no longer lines up with decode's blocks and you get wrong output, not just slow output. Nothing in vLLM catches that mismatch today (#43094), so check your chat template before you turn this on.
Running the GPU-Less Frontend
Taking CPU work off the GPU box is only part of it. Once the engine takes token IDs in and gives token IDs out, it doesn't need the chat template or the parsers any more, and the caller gets to see and use the token IDs. A router can render a request, then pick a replica on prefix cache hits for the real prompt tokens rather than guessing from text. RL and eval pipelines get the exact IDs the model saw and produced, which matters because decoded text doesn't always re-tokenize the same way.
Multimodal preprocessing moves too. Image decoding and the model's processor run on the render tier and with encoder disaggregation, render sends the processed tensors to the encoder and just the metadata to prefill. The processed payload can be much bigger than the source image, so size your request limits for it.
Two servers: a render tier with no GPU and an engine that speaks tokens only. The parsers go on the render server since that's where derender runs them.
vllm launch render Qwen/Qwen3-0.6B --port 8100 \
  --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser hermes
vllm serve Qwen/Qwen3-0.6B --tokens-only --port 8200
Both of those modes always expose their scale-out endpoints. On a regular vllm serve they're off by default. If you want /render, /derender or /inference/v1/generate on a server that also takes normal OpenAI traffic, add --enable-scale-out.
Then it's three hops — render, generate, derender:
import httpx

MODEL = "Qwen/Qwen3-0.6B"
RENDER = "http://localhost:8100"  # vllm launch render
ENGINE = "http://localhost:8200"  # vllm serve --tokens-only

chat_request = {
    "model": MODEL,
    "messages": [{"role": "user", "content": "What is 17 * 23?"}],
    "max_tokens": 2048,
}

with httpx.Client(timeout=60.0) as client:
    # 1. request -> token IDs (no GPU)
    generate_request = client.post(f"{RENDER}/v1/chat/completions/render", json=chat_request).json()

    # 2. token IDs -> token IDs (GPU)
    generate_response = client.post(f"{ENGINE}/inference/v1/generate", json=generate_request).json()

    # 3. token IDs -> ChatCompletionResponse (no GPU)
    response = client.post(f"{RENDER}/v1/chat/completions/derender", json={
        "model": MODEL,
        "generate_response": generate_response,
        "prompt_tokens": len(generate_request["token_ids"]),
        "chat_request": chat_request,
    }).json()

message = response["choices"][0]["message"]
print(message["reasoning"], message["content"], sep="\n---\n")
Pass chat_request back into the derender step. The parsers need the original context (tools, tool_choice, include_reasoning) to produce the same content / reasoning / tool_calls split a normal vllm serve would. On a model with a parser configured, leaving it out gets you a 400 rather than a silent fallback that leaks <tool_call> markup into content.
Streaming
Both endpoints also take stream: true. /render keeps stream on the request it returns, so generate streams too, and each generate chunk goes through derender on its own. Continuing the example above:
import json

chat_request = {**chat_request, "stream": True}

with httpx.Client(timeout=60.0) as client:
    generate_request = client.post(f"{RENDER}/v1/chat/completions/render", json=chat_request).json()
    prompt_token_ids = generate_request["token_ids"]

    stream_state = None  # one per choice index if n > 1
    with client.stream("POST", f"{ENGINE}/inference/v1/generate", json=generate_request) as stream:
        for line in stream.iter_lines():
            if not line.startswith("data: ") or line == "data: [DONE]":
                continue
            derendered = client.post(f"{RENDER}/v1/chat/completions/derender", json={
                "stream": True,
                "model": MODEL,
                "generate_chunk": json.loads(line[len("data: "):]),
                "stream_state": stream_state,
                "prompt_tokens": len(prompt_token_ids),
                "prompt_token_ids": prompt_token_ids,
                "chat_request": chat_request,
            }).json()
            stream_state = derendered["stream_state"]
            for choice in derendered["chunk"]["choices"]:
                print(choice["delta"].get("content") or "", end="", flush=True)
Send stream_state as null on the first call and echo back whatever the last response gave you. chat_request and prompt_token_ids go with every chunk because the server keeps nothing between calls. Because of that, any render replica can handle any chunk. It's also where the cost comes from once a parser is involved (see What's still left).
Deploying the Render Tier
The render tier holds no per-request state, even when streaming, so it scales like any stateless web service. Put replicas behind an ordinary load balancer and scale them on CPU, independently of the GPU pool.
Keep the config in sync. Render, derender and the engine have to agree on the model, tokenizer, chat template and parser flags (--chat-template, --default-chat-template-kwargs, --reasoning-parser, --tool-call-parser, --enable-auto-tool-choice). A mismatch doesn't raise an error. You just get a different content / reasoning / tool_calls split from what vllm serve would return.
Then size the thread pool. Templating, tokenization, multimodal preprocessing and streaming parser replay all run on the renderer's workers, set by --renderer-num-workers, which defaults to 1. Plain rendering is cheap (about 15 ms of CPU for the 9k-token prompt above). Streaming a reasoning or tool-calling model through a parser costs a lot more, so raise the worker count or add replicas to match your concurrent parsed streams.
Putting Both Splits Together
Figure 1 shows both splits at once: four tiers, but only three servers since one vllm launch render server handles both /render and /derender. Nothing upstream drives the four hops for you yet but the pieces combine because /inference/v1/generate accepts kv_transfer_params just like /v1/chat/completions does.
# Render and derender, no GPU
vllm launch render Qwen/Qwen3-0.6B --port 8000 \
  --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser hermes

# Prefill on GPU 0
CUDA_VISIBLE_DEVICES=0 UCX_NET_DEVICES=all VLLM_NIXL_SIDE_CHANNEL_PORT=5600 \
vllm serve Qwen/Qwen3-0.6B --tokens-only --port 8100 \
  --kv-transfer-config '{"kv_connector":"NixlConnector","kv_role":"kv_producer"}'

# Decode on GPU 1
CUDA_VISIBLE_DEVICES=1 UCX_NET_DEVICES=all VLLM_NIXL_SIDE_CHANNEL_PORT=5601 \
vllm serve Qwen/Qwen3-0.6B --tokens-only --port 8200 \
  --kv-transfer-config '{"kv_connector":"NixlConnector","kv_role":"kv_consumer"}'
Your code then plays the proxy's part between render and derender:
import httpx

MODEL = "Qwen/Qwen3-0.6B"
RENDER, PREFILL, DECODE = "http://localhost:8000", "http://localhost:8100", "http://localhost:8200"

chat_request = {
    "model": MODEL,
    "messages": [{"role": "user", "content": "What is 17 * 23?"}],
    "max_tokens": 2048,
}

with httpx.Client(timeout=60.0) as client:
    # 1. Render: request -> token IDs (no GPU)
    generate_request = client.post(f"{RENDER}/v1/chat/completions/render", json=chat_request).json()

    # 2. Prefill: compute the KV cache, generate one token, hold the blocks
    prefill_response = client.post(f"{PREFILL}/inference/v1/generate", json={
        **generate_request,
        "sampling_params": {**generate_request["sampling_params"], "max_tokens": 1},
        "kv_transfer_params": {"do_remote_decode": True},
    }).json()

    # 3. Decode: pull prefill's blocks over NIXL, then generate
    generate_response = client.post(f"{DECODE}/inference/v1/generate", json={
        **generate_request,
        "kv_transfer_params": prefill_response["kv_transfer_params"],
    }).json()

    # 4. Derender: token IDs -> ChatCompletionResponse (no GPU)
    response = client.post(f"{RENDER}/v1/chat/completions/derender", json={
        "model": MODEL,
        "generate_response": generate_response,
        "prompt_tokens": len(generate_request["token_ids"]),
        "chat_request": chat_request,
    }).json()

message = response["choices"][0]["message"]
print(message["reasoning"], message["content"], sep="\n---\n")
Step 2 is the same trick the proxy uses: a one-token budget plus do_remote_decode, so prefill computes the KV cache and holds on to the blocks. Step 3 hands decode the kv_transfer_params prefill returned which point at those blocks. The example proxy only handles /v1/completions and /v1/chat/completions, so in production this orchestration is yours to write. It's also the job of llm-d and Dynamo which the renderer docs name as its intended callers.
Who's Actually Running This
llm-d uses vLLM's native remote prefill/decode and NIXL KV-transfer capabilities. llm-d's router and EPP scheduler choose the prefill/decode endpoints and orchestrate the KV-cache handoff between them. NVIDIA Dynamo runs vLLM on Kubernetes in aggregated or disaggregated mode with its own router and planner. KServe exposes it through LLMInferenceService, built on llm-d.
The vLLM production stack ships disaggregated prefill via Helm and AIBrix covers the control plane side. On the connector side, Moonshot's Mooncake, LMCache and AMD's MoRI-IO are all upstream. And because decode sits behind a connector, it doesn't even have to be vLLM: TileRT pairs stock vLLM prefill with its own latency optimized decode engine.
What's Still Left To Do?
Streaming derender with a parser is expensive. Reasoning and tool parsers hold state that can't be serialized, so each chunk rebuilds a fresh parser and replays the token history through it. Transport is O(n) per chunk, replay is O(n) parse calls per chunk and parse_delta itself rescans accumulated text for parsers like Hermes and DeepSeek-R1. That's O(n³) character work over a long generation. A benchmark on multi-thousand-token reasoning output measured roughly 9× the in-process CPU at matched load and +15% on E2E p50. A caching layer is scheduled (#57571). Until it lands, a render tier left at one worker saturates under concurrent parsed streams, so size it as described above.
Long prompts dominate the wire. The parser path resends prompt_token_ids in full on every chunk. A 100k-token prompt with 1k tokens of output means the prompt is ~99% of each request body. Plain detokenization without a parser doesn't have this problem.
Some small correctness gaps are being worked on. Batch derender doesn't always return finish_reason: "tool_calls" when it parses tool calls (fix pending in #47931) and it mints its own tool call IDs instead of keeping the parser's. Logprobs come back from the tokenizer free engine as "token_id:N" placeholder strings which works but isn't ideal. #57574 proposes returning real integer token IDs.
One design question is still open. #56851 asks whether /inference/v1/generate should just return text or derendered output directly, skipping the third hop for callers who don't need it.
The umbrella RFCs are #42729 (detokenization batch), #47161 (detokenization streaming), #22817 (tokens-in, tokens-out) and #34407 (disaggregated frontend). Please weigh in on the RFCs and let us know what you think.
Where To Start
If you've got two GPUs, run the NIXL example above with a 7B-class model. Qwen3-0.6B prefills so fast that it barely disturbs decode, so there's nothing for P/D to fix. Check the transfer first, as discussed above. Then run the same benchmark against the proxy on 8192 and against one collocated vllm serve --data-parallel-size 2 on the same two GPUs, and compare p99 ITL, TTFT and goodput. Step --request-rate up until the collocated server's p99 ITL falls apart. With 8k prompts on the test box that was 0.4 req/s. Start every server with --no-enable-prefix-caching if you reuse a --seed across rates. Otherwise later rates replay prompts the server has cached and the cache hits hide exactly the prefill interference you're trying to measure.
vllm bench serve --model Qwen/Qwen2.5-7B-Instruct --port 8192 \
  --dataset-name random --random-input-len 8192 --random-output-len 256 --ignore-eos \
  --request-rate 0.4 --num-prompts 100 \
  --percentile-metrics ttft,tpot,itl --metric-percentiles 50,99 \
  --goodput ttft:2000 tpot:30
Serving chat or agents? Turn on bidirectional_kv_xfer and measure TTFT on turn five, not turn one.
If you're already on Kubernetes, start from llm-d or Dynamo rather than building a proxy yourself. And if you're running a reasoning or tool-calling model through streaming derender, benchmark the render tier before you size it — that's the part most likely to surprise you.
Docs: disaggregated prefilling, NixlConnector, renderer, derenderer.
Acknowledgements
Thanks to @aoshen02, Bongwoo Bak, Chauncey, Guan-Ming Chiu, Hyunkyun Moon, Konstantin Dunas, Maroon Ayoub, Nick Hill, Nicolò Lucchesi, Nithin Chalapathi, Robert Shaw, Sagi Ahrac, Seiji Eicher, @snadampal, Will Eaton, Yuqi Wang, and Yuge Zhang, as well as others in the vLLM community for helping deliver disaggregated serving.