要点速览
- DSpark 在 DFlash 并行起草上加顺序修正与置信度两个轻量头,缓解 suffix decay 并拉长接受序列。
- Speculators 为 2.8T 的 Kimi K3 训练出 5 层/5B 参数、每步 8 token 的 DSpark,宏平均接受长度 4.11。
- 单流交互性 ~110→~435 tok/s/user;并发 1→16 时聚合吞吐 177→683 tok/s;matched 交互性下吞吐最高 ~3.5×。
- 2.8T 模型放不进单节点,于是用 Mooncake 传输引擎跨节点流式搬运 hidden states,训练与推理解耦、独立伸缩。
- 在 Verda 的 GB300 NVL72 机架上以 12 节点训练,每 3 节点一组(2 节点推理 + 1 节点训练)吞吐最佳,模型以 HF 兼容格式发布。
解决什么问题
DSpark 算法虽强,但要给 2.8T 参数的前沿模型 Kimi K3 训练草稿模型仍缺一套可复用的工程路径:训练需要目标模型的 hidden states 与 log-probability 输出构成的数据集,而 Kimi K3 即便 4-bit 量化也超出单节点显存,既有的单节点 hidden-state 抽取方案无法扩展。文章要回答的正是开源社区关心的那个问题:能否不靠专人看护 checkpoint,就把 DSpark 训练、打包并部署出来。
核心思路
用 vLLM 项目的 Speculators 训练库完成 DSpark draft model 的训练、打包与部署,产出标准 Hugging Face 兼容格式,vLLM 直接加载。训练数据靠 vLLM 的 hidden-state 抽取系统生成:一个 dummy draft model 复用 draft-model 管线接收目标模型 hidden states 并写入 dummy attention layer 的 KV cache,再由实现 KVConnector 接口的类导出。为突破单节点限制,新构建 MooncakeHiddenStatesConnector,以 Mooncake transfer engine 为后端,由 master Mooncake proxy 撮合 vLLM 引擎与 Speculators dataloader 之间的 RDMA/TCP 流式传输。训练在 Verda 提供的 GB300 NVL72 机架上进行,采用 12 节点、每 3 节点一组(2 节点 vLLM 推理 + 1 节点训练)的解耦拓扑,两类资源可独立伸缩。
关键要点
- DSpark:并行起草 + 顺序修正 + 置信度调度 — DFlash 用一次非因果 backbone 前向预测整块 token,但并行位置无法互相条件化:对 “Thank you!”,位置一可能同时偏向 “Of” 和 “No”,下一位置同时偏向 “course” 和 “problem”,拼出 “Of problem” 这类错配;又因验证在首个被拒 token 处停止,一个错误会作废整个后缀,即 suffix decay。DSpark 保留并行 backbone,新增 Markov logit-bias head——顺序采样 token,并用低秩转移矩阵按上一个已选 token 调整当前位置 logits,在不增加一次 transformer 前向的情况下恢复局部依赖。confidence head 则估计每个 token 被接受的概率,供硬件感知调度器在轻载时验证更长前缀、繁忙时裁剪不易被接受的后缀。
- Speculators:训练、打包、部署一条龙 — Speculators 是 vLLM 项目的开源训练库,用于构建、训练、评估和分享推测解码模型,产出标准 Hugging Face 兼容格式,vLLM 直接加载,免去手工照看 checkpoint。该实现已在 Qwen3.6-35B-A3B、Gemma-4-31B-it、GLM-5.2 等模型上验证,本篇把它扩展到 2.8T 参数的 Kimi K3。成品以 RedHatAI/Kimi-K3-speculator.dspark 发布,配合官方 vLLM recipe 一条 docker run 即可部署。
- 推理性能:接受长度与长上下文 — Kimi K3 DSpark speculator 用 5 层、50 亿参数的 draft model,每个解码步提议 8 个 token,九个评测域宏平均接受长度 4.11。结构化任务最强:数学推理 6.42、HumanEval 4.96、翻译 4.65。长上下文尤其亮眼:LongBench-v2 上 378K-token prompt 达到每解码迭代 5.31 个输出 token,整体负载中 top 10% 请求也至少 3.76,说明显著的投机深度在真实长上下文下依然可行。需要注意的是,半自回归设计只有在额外顺序开销远低于一次 draft model 前向时才有净收益。
- 并发扩展与首 token 延迟 — 并发从 1 提到 16,聚合输出吞吐从 177 升至 683 tok/s,扩展性良好。同时 median time to first token 仅增加 100 ms(379→479 ms),说明负载下响应启动依然很快。加速在低请求量时最显著;在 matched interactivity 条件下,并发负载的输出吞吐最高约 3.5×。
- 训练数据从哪来:hidden-state 抽取 — draft model 小而强的关键是把目标模型 hidden states 当输入,从而与目标预测对齐,这要求训练集包含 hidden-state 输入与目标模型 log-probability 输出。vLLM 的 hidden-state 抽取系统用 dummy draft model 复用 draft-model 管线接收目标 hidden states,并插入 dummy attention layer 的 KV cache,再由实现 KVConnector 接口的类取出;内置的 ExampleHiddenStatesConnector 会把 hidden states 异步写盘。该方案适合单节点:半数 GPU 训练、半数 GPU 跑 vLLM 按需抽取。
- MooncakeHiddenStatesConnector:跨节点的数据面 — 2.8T 参数的 Kimi K3 即使 4-bit 量化,也至少需要两个 GB300 节点(每节点 4 GPU)才能 serving,单节点抽取方案不可行。新连接器以 Mooncake transfer engine 为后端,在进程间与跨节点流式传输:master Mooncake proxy 负责与 vLLM 及注册为 client 的训练实例通信;训练进程向 vLLM 前端发请求并拿到 Mooncake store key,master 再撮合从 vLLM 引擎到 Speculators dataloader 的传输。控制路径与数据路径分离,可配置走高速 RDMA 或普通 TCP。
- GB300 NVL72 环境与 12 节点训练拓扑 — 训练在 Verda 提供的 GB300 机架完成:NVIDIA 参考设计、裸金属无虚拟化,Ubuntu 24.04.4 LTS(64K-page kernel 6.14),610.57.04 open-kernel 驱动(R610),CUDA 13.4.0 Developer Preview(首个支持 Rubin sm_107 的工具链)与 CUDA 13.1/12.9 并存,系统级 NCCL 2.31.2;无需 root 即可用硬件计数器做 GPU profiling。拓扑共 12 节点,每 3 节点一组:1 个四 GPU 节点训练、2 个四 GPU 节点跑 vLLM 推理,Mooncake 负责传输 hidden states。实测该配比吞吐最佳,且推理与训练两类资源可独立伸缩调优。
- 部署:官方 recipe 一条命令拉起 — 按 vLLM 官方 Kimi-K3 recipe 用 docker run 部署:--tensor-parallel-size 16 --nnodes 2,--load-format fastsafetensors,--kv-cache-dtype fp8,TOKENSPEED_MLA attention 后端(含 prefill query quantization),--enable-prefix-caching 且 --prefix-match-unit 128,--max-model-len 1048576。推测解码通过 --speculative-config 启用:method=dspark、model=RedHatAI/Kimi-K3-speculator.dspark、num_speculative_tokens=8、draft_sample_method=probabilistic、rejection_sample_method=block。另需 --reasoning-parser kimi_k3 与 --language-model-only。
关键数据
| 指标 | 数值 | 条件 |
|---|---|---|
| 单流交互性(数学推理) | ~110 → ~435 tok/s/user | Kimi K3 + DSpark speculator,数学推理负载;文章未注明该项测试的具体推理硬件 |
| 并发下输出吞吐提升 | 最高 ~3.5× | Kimi K3 + DSpark,并发负载、与基线交互性对齐(matched interactivity)条件下 |
| draft model 规模与提议长度 | 5 层、50 亿参数;每解码步提议 8 个 token | 已发布的 Kimi K3 DSpark speculator(目标模型为 2.8T 参数) |
| 宏平均接受长度 | 4.11 tokens/验证轮 | 九个评测域取宏平均 |
| 分域接受长度 | 数学推理 6.42 / HumanEval 4.96 / 翻译 4.65 tokens | 结构化任务表现最强 |
| 长上下文接受长度 | 最高 5.31 tokens/解码迭代 | LongBench-v2 数据集,378K-token prompt |
| 长上下文负载 top 10% 接受长度 | ≥3.76 tokens/迭代 | LongBench-v2 更广泛负载中接受长度最高的 10% 请求 |
| 聚合输出吞吐(并发扩展) | 177 → 683 tok/s | 并发请求数从 1 增至 16;文章未注明具体推理硬件 |
| median TTFT 增量 | 379 → 479 ms(仅 +100 ms) | 并发请求数增至 16 倍(1→16)时 |
| 接受序列长度对比 | 比 DFlash 长 16–18%,比 EAGLE-3 长 27–31% | DSpark 论文数据,Qwen3 目标模型 |
| 生产环境每用户生成速度提升 | 60–85% | DSpark 论文数据,DeepSeek-V4 生产 serving,较 MTP-1 基线、吞吐对齐 |
| DFlash 相对 EAGLE-3 的加速 | 最高 2.5× | DFlash 论文报告数据 |
| 训练拓扑配比 | 每 3 节点一组 = 2 节点推理 + 1 节点训练(每节点 4 GPU) | GB300 机架,Kimi K3 4-bit 量化;4-bit 下目标模型 serving 至少需 2 个 GB300 节点 |
“boosts single-stream interactivity from ~110 to ~435 tok/s/user on math reasoning”
“while delivering up to **~3.5× higher output throughput** at matched interactivity under concurrent load”
“uses a five-layer, five-billion-parameter draft model and proposes eight tokens per decoding step”
前置知识
推测解码基本机制:轻量 draft model 先提议多个 token,目标模型一次前向并行验证,验证在首个被拒 token 处截断 · EAGLE-3 与 DFlash 两种起草方式的差异:自回归逐步起草 vs 单次非因果块级起草 · Transformer 的 hidden states 与 KV cache 概念 · 分布式推理基础:tensor parallelism、多节点部署与 NCCL 通信 · RDMA 高速传输的概念,以及 Mooncake 传输引擎的定位 · vLLM 基本用法:OpenAI 兼容 serving 与 docker 启动参数
术语表
DSpark: DeepSeek 提出的 DFlash 扩展算法:保留并行块级起草,加入 Markov logit-bias head 与 confidence head,提升 token 间连贯性与接受长度。DFlash: 块级推测解码算法:一次非因果 backbone 前向预测整块 token,相比 EAGLE-3 报告最高 2.5× 加速。EAGLE-3: 推测解码强基线:仍需自回归起草,提议七个 token 要七步顺序 drafting。Speculators: vLLM 项目的开源训练库,用于构建、训练、评估、分享推测解码模型,输出 Hugging Face 兼容格式,可与 vLLM 等推理引擎直接集成。draft model: 推测解码中的轻量草稿模型,快速提议多个候选 token 供目标模型验证;常以目标模型 hidden states 为输入。suffix decay: 后缀衰减:并行起草中一个 token 被拒绝,其后的整个后缀都随之作废。Markov logit-bias head: DSpark 组件:顺序采样 token,并用低秩转移矩阵按上一个已选 token 调整各位置 logits,恢复局部依赖。confidence head: DSpark 组件:估计每个 token 被接受的概率,供硬件感知调度器决定验证前缀长度。acceptance length: 接受长度:每轮验证中目标模型实际接受的 token 数,是衡量草稿质量的核心指标。Mooncake: 传输引擎(以 KV cache 传输起家),本文中作为 hidden states 跨进程/跨节点流式传输的后端,支持 RDMA 与 TCP。KVConnector: vLLM 中负责 KV cache/hidden states 转移的接口;文中 MooncakeHiddenStatesConnector 与 ExampleHiddenStatesConnector 均为其实现。hidden states: 目标模型的内部中间表示,作为 draft model 的输入,使其预测与目标模型对齐。MTP-1: 单 token 的 multi-token prediction 基线,DeepSeek-V4 生产环境此前采用的方案。TTFT: time to first token,首 token 延迟,衡量交互启动速度的指标。GB300 NVL72: NVIDIA GB300 机架级系统;文中 Verda 的部署保持 NVIDIA 参考设计并裸金属运行。
How we trained the fastest DSpark for Kimi-K3 using GB300 NVL72
In June, DeepSeek shipped DSpark, an extension to the DFlash block-level speculative decoding algorithm. The new algorithm promised stronger intertoken coherence and therefore better acceptance lengths. But the real question for the open-source community is always the same: can you train it, package it, and deploy it without a PhD student babysitting the checkpoint?
Thanks to the vLLM Project's Speculators training library, the answer is a resounding yes! With Speculators it’s easy to train, package, and deploy DSpark draft models in a standard, Hugging Face-compatible format that vLLM loads directly. The implementation has already been validated on Qwen3.6-35B-A3B, Gemma-4-31B-it, GLM-5.2, and more. This blog post explores how we extended our training library to support Kimi K3, a 2.8T-parameter frontier model. Our new DSpark speculator boosts single-stream interactivity from ~110 to ~435 tok/s/user on math reasoning, while delivering up to ~3.5× higher output throughput at matched interactivity under concurrent load.
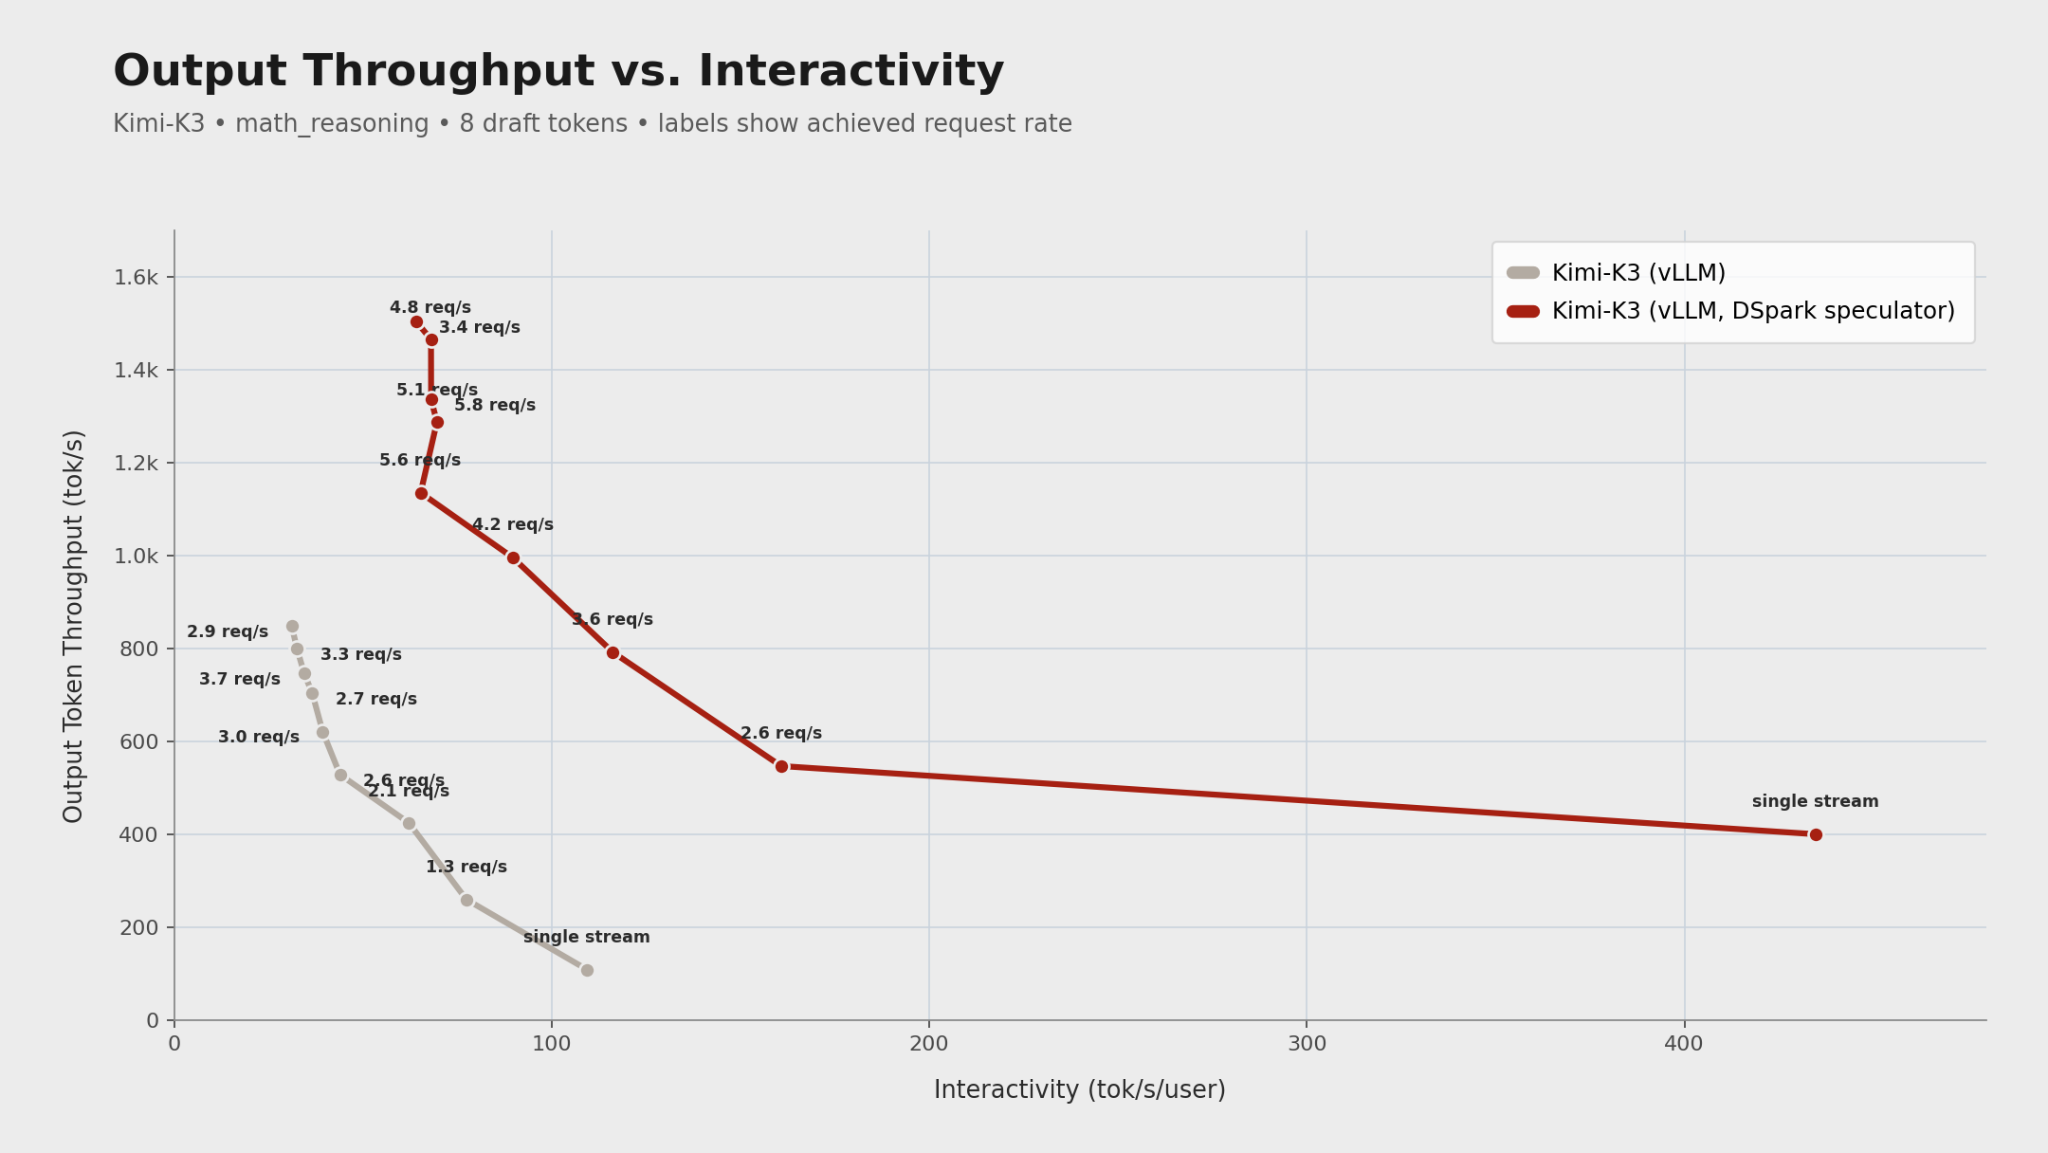
Figure 1. The Kimi K3 DSpark speculator raises both single-stream interactivity and aggregate output throughput on math reasoning workloads.
What Is DSpark?
Large language models generate text one token per forward pass. Speculative decoding accelerates this process by having a lightweight drafter propose several tokens, which the full target model verifies together.
EAGLE-3 is a strong baseline, but it still drafts autoregressively: seven proposed tokens require seven sequential drafting steps. DFlash instead predicts an entire block in one non-causal backbone pass, reporting up to 2.5× greater acceleration than EAGLE-3.
The tradeoff is that parallel positions cannot condition on one another. For a prompt “Thank you!” the model might independently favor responses of both “Of” and “No” at position one and both “course” and “problem” at the next, producing mismatches such as “Of problem.” Because verification stops at the first rejected token, one mistake also invalidates the remaining suffix—a problem the DSpark paper calls suffix decay.
DSpark preserves DFlash’s parallel backbone while adding two lightweight components:
- The Markov logit-bias head samples tokens sequentially and adjusts each position’s logits using the previously selected token. Its low-rank transition matrix restores important local dependencies without another transformer pass.
- The confidence head estimates the probability that each token will be accepted. A hardware-aware scheduler uses these estimates to verify longer prefixes under light load and trim unlikely suffixes when the system is busy.
DSpark therefore keeps the main advantage of parallel drafting by inheriting the single backbone pass, while recovering some of the coherence of autoregressive generation. Across Qwen3 target models, it reports 16–18% longer accepted sequences than DFlash and 27–31% longer sequences than EAGLE-3. In DeepSeek-V4 production serving, it improved per-user generation speed by 60–85% over the previous MTP-1 baseline at matched throughput.
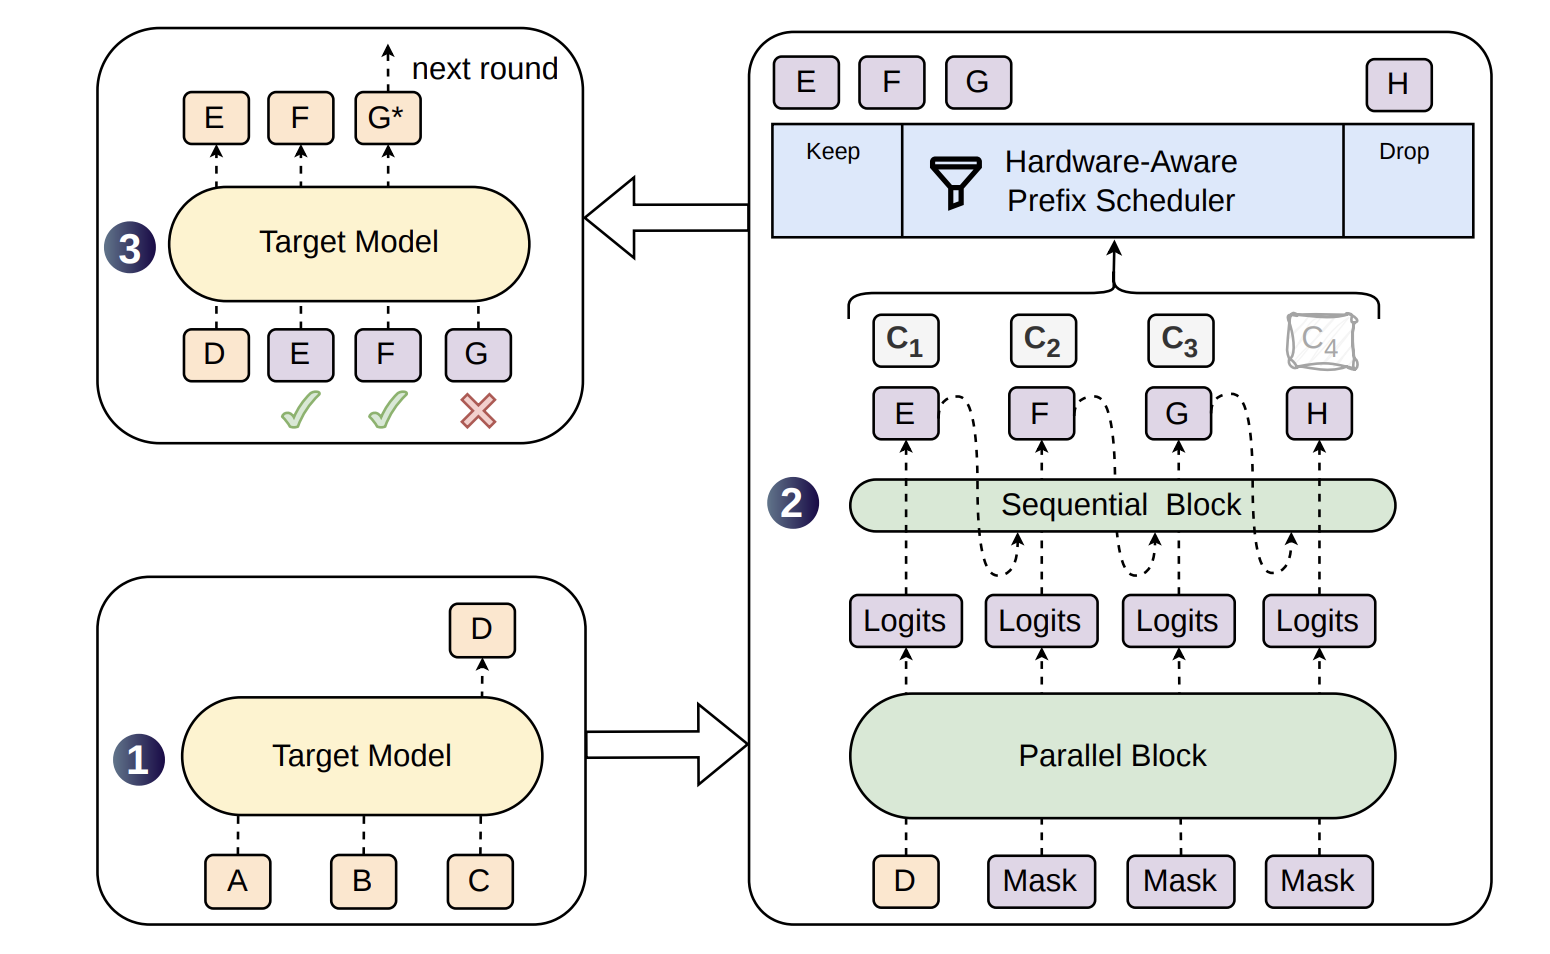
Figure 2. DSpark combines a parallel block with sequential correction and hardware-aware prefix scheduling before target-model verification.
Performance During Inference
DSpark’s semi-autoregressive design improves inference only when the additional sequential work remains much cheaper than another draft-model forward pass. The released Kimi K3 DSpark speculator uses a five-layer, five-billion-parameter draft model and proposes eight tokens per decoding step.
Across nine evaluation domains, it achieves a macro-average acceptance length of 4.11 tokens per verification round. Performance is strongest on structured tasks: 6.42 tokens for mathematical reasoning, 4.96 for HumanEval, and 4.65 for translation. The speedup is especially significant at low request counts.
This model works especially well for long-context prompts. On a challenging domain-specific dataset like LongBench-v2, our Kimi K3 DSpark reached up to 5.31 output tokens per decode iteration on a 378K-token prompt. Even across the broader workload, the top 10% of requests achieved at least 3.76 tokens per iteration, demonstrating that deep speculative runs remain possible at genuinely long context lengths.
It scales effectively as more requests arrive simultaneously. Increasing concurrency from 1 to 16 raises aggregate output throughput from 177 to 683 tokens per second.
Crucially, response startup remains fast under load. Despite serving 16 times as many concurrent requests, median time to first token increases by only 100 milliseconds, from 379 to 479 milliseconds.
Deployment is easy. Follow the official vLLM recipe for your hardware and use case:
docker run --gpus all \
  --privileged --ipc=host -p 8000:8000 \
  -v ~/.cache/huggingface:/root/.cache/huggingface \
  -e GLOO_SOCKET_IFNAME=$IFACE_NAME \
  -e NCCL_SOCKET_IFNAME=$IFACE_NAME \
  -e VLLM_ALLREDUCE_USE_FLASHINFER=1 \
  -e VLLM_ENGINE_READY_TIMEOUT_S=3600 \
  -e VLLM_USE_V2_MODEL_RUNNER=1 \
  -e VLLM_USE_RUST_FRONTEND=1 \
  vllm/vllm-openai:latest moonshotai/Kimi-K3 \
  --trust-remote-code \
  --gpu-memory-utilization 0.95 \
  --tensor-parallel-size 16 \
  --nnodes 2 \
  --node-rank 0 \
  --master-addr $HEAD_IP \
  --load-format fastsafetensors \
  --no-enable-flashinfer-autotune \
  --max-model-len 1048576 \
  --kv-cache-dtype fp8 \
  --attention-config '{"use_prefill_query_quantization":true,"mla_prefill_backend":"TOKENSPEED_MLA"}' \
  --enable-prefix-caching \
  --attention-backend TOKENSPEED_MLA \
  --prefix-match-unit 128 \
  --reasoning-parser kimi_k3 \
  --language-model-only \
  --speculative-config '{"model":"RedHatAI/Kimi-K3-speculator.dspark", "num_speculative_tokens":8, "method":"dspark", "draft_sample_method":"probabilistic", "rejection_sample_method":"block"}'
Hardware Setup
This model was trained on a GB300 rack generously provided by Verda. Verda is a European AI cloud that owns the stack end to end, from data centers to managed services, and runs on 100% renewable energy. Verda was among the first providers in Europe to deploy GB300 NVL72 racks. Its in-house AI Lab also conducts inference research on the same racks.
The GB300 rack keeps the NVIDIA reference design and runs bare metal, without virtualization, using Ubuntu 24.04.4 LTS on NVIDIA's 64K-page kernel 6.14.
Verda focuses its optimization efforts on the system-level configuration choices that matter most, giving researchers access to a frontier-class environment. The system uses NVIDIA’s 610.57.04 open-kernel GPU driver (R610). CUDA 13.4.0 Developer Preview is installed alongside CUDA 13.1 and 12.9, while NCCL 2.31.2 is available system-wide.
CUDA 13.4.0 was selected for its new Blackwell programming features and because it is the first toolkit to include Rubin support (sm_107). This helps ensure that code written and profiled on GB300 today can be built for the next generation of hardware without unexpected compatibility issues. Hardware-counter-based GPU profiling is also available without root access, allowing every researcher to profile both training and inference workloads.
We have been collaborating with Verda to help open-source training and inference infrastructure scale to the latest GPU architectures, with a current focus on rack-scale systems spanning GB300 through VR200. We are grateful to see the results of this collaboration taking shape.
Extracting Hidden States at Scale
Part of what makes speculative decoding draft models so powerful despite their small size is that they often take hidden states from the target model as inputs to inform their predictions. This greatly improves their working context and makes it possible for the drafters to closely align their predictions with the target models.
The caveat is that training these drafters requires a dataset of hidden-state inputs and target-model log-probability outputs. Thankfully, vLLM has a hidden-state extraction system that makes it possible to get internal target hidden states on demand for dataset samples. This system uses a dummy draft model, which reuses vLLM’s draft-model plumbing to receive target hidden states and inserts them into the KV cache of a dummy attention layer. From there, a class implementing the KVConnector interface can retrieve and transfer the hidden states out of vLLM. Currently vLLM ships with an ExampleHiddenStatesConnector that does just that, writing the hidden states asynchronously to disk.
This system works well for single-node vLLM-and-training configurations. For example, half the node’s GPUs can be devoted to training, while the other half serve the target model in vLLM and extract hidden states on demand. This system has been well supported in both Speculators and vLLM for months. However, with a 2.8T-parameter model like Kimi K3, even state-of-the-art accelerators start to run into VRAM limits despite 4-bit quantization for model weights. We need a system that scales beyond single-node training and enables disaggregated training and hidden-state extraction.
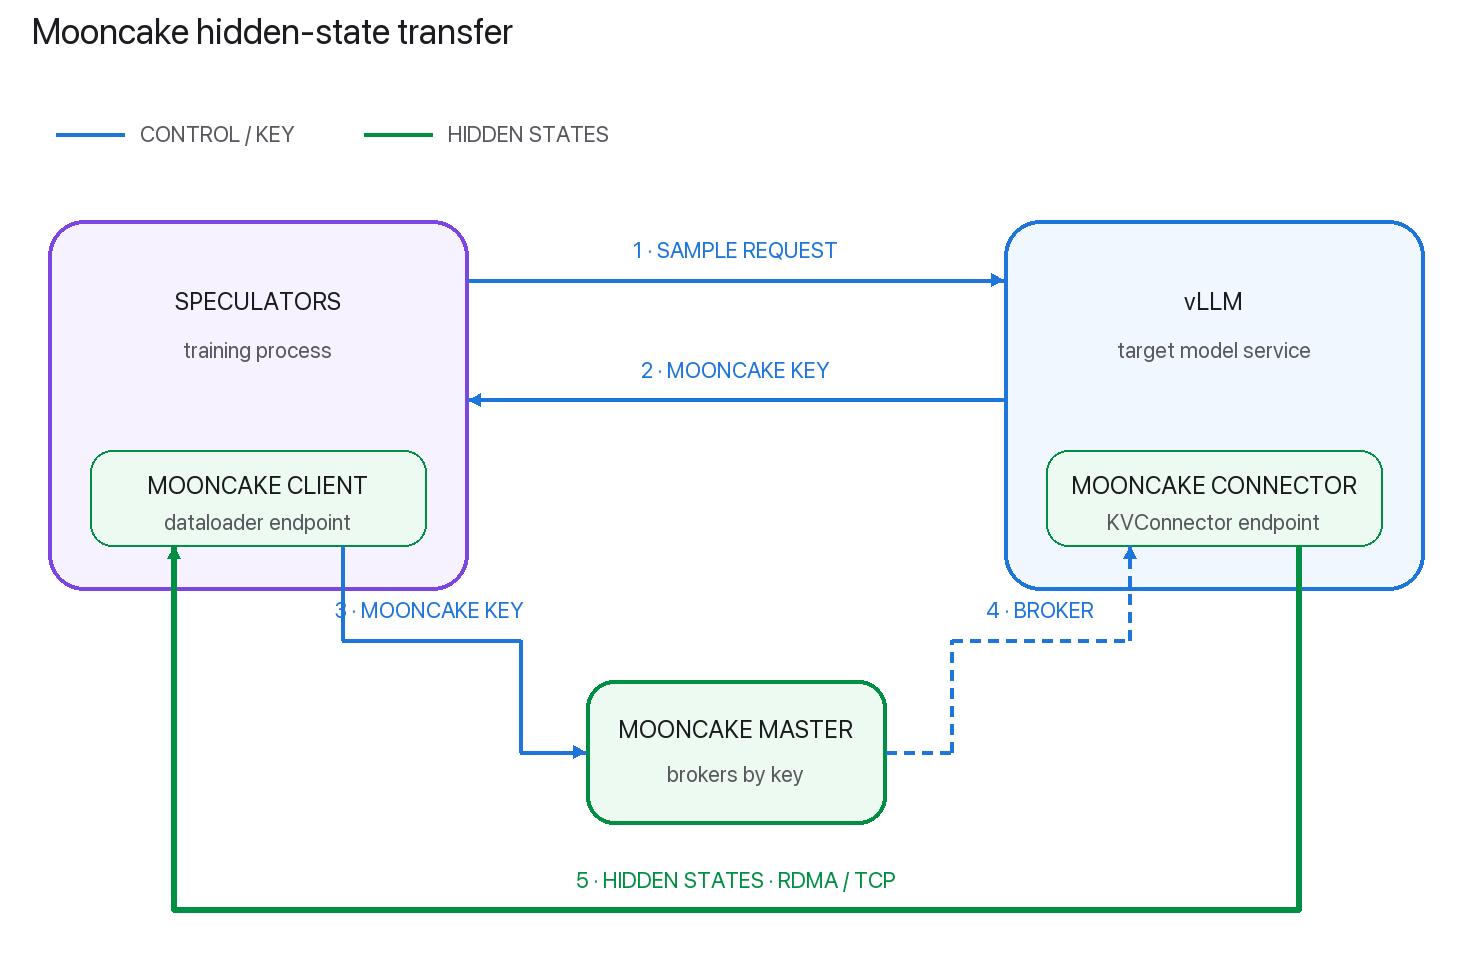
Figure 3. The Mooncake connector separates the control path from the hidden-state data path, using RDMA or TCP for transfers between vLLM and the Speculators dataloader.
With these requirements in mind, we built the MooncakeHiddenStatesConnector, which uses the Mooncake transfer engine as its backend for streaming hidden states between processes and across nodes. The new system uses a master Mooncake proxy process to manage communication with vLLM and training instances that register themselves as clients. Once set up, training processes can send requests to the vLLM frontend and receive a Mooncake store key in response. That key is then provided to the Mooncake master, which brokers a transfer from the vLLM engine to the Speculators dataloader. All of this happens automatically, managed by the Mooncake server, and—depending on configuration—uses high-speed RDMA transfers or regular TCP to send data between processes on the same or different nodes.
Training Kimi K3 DSpark
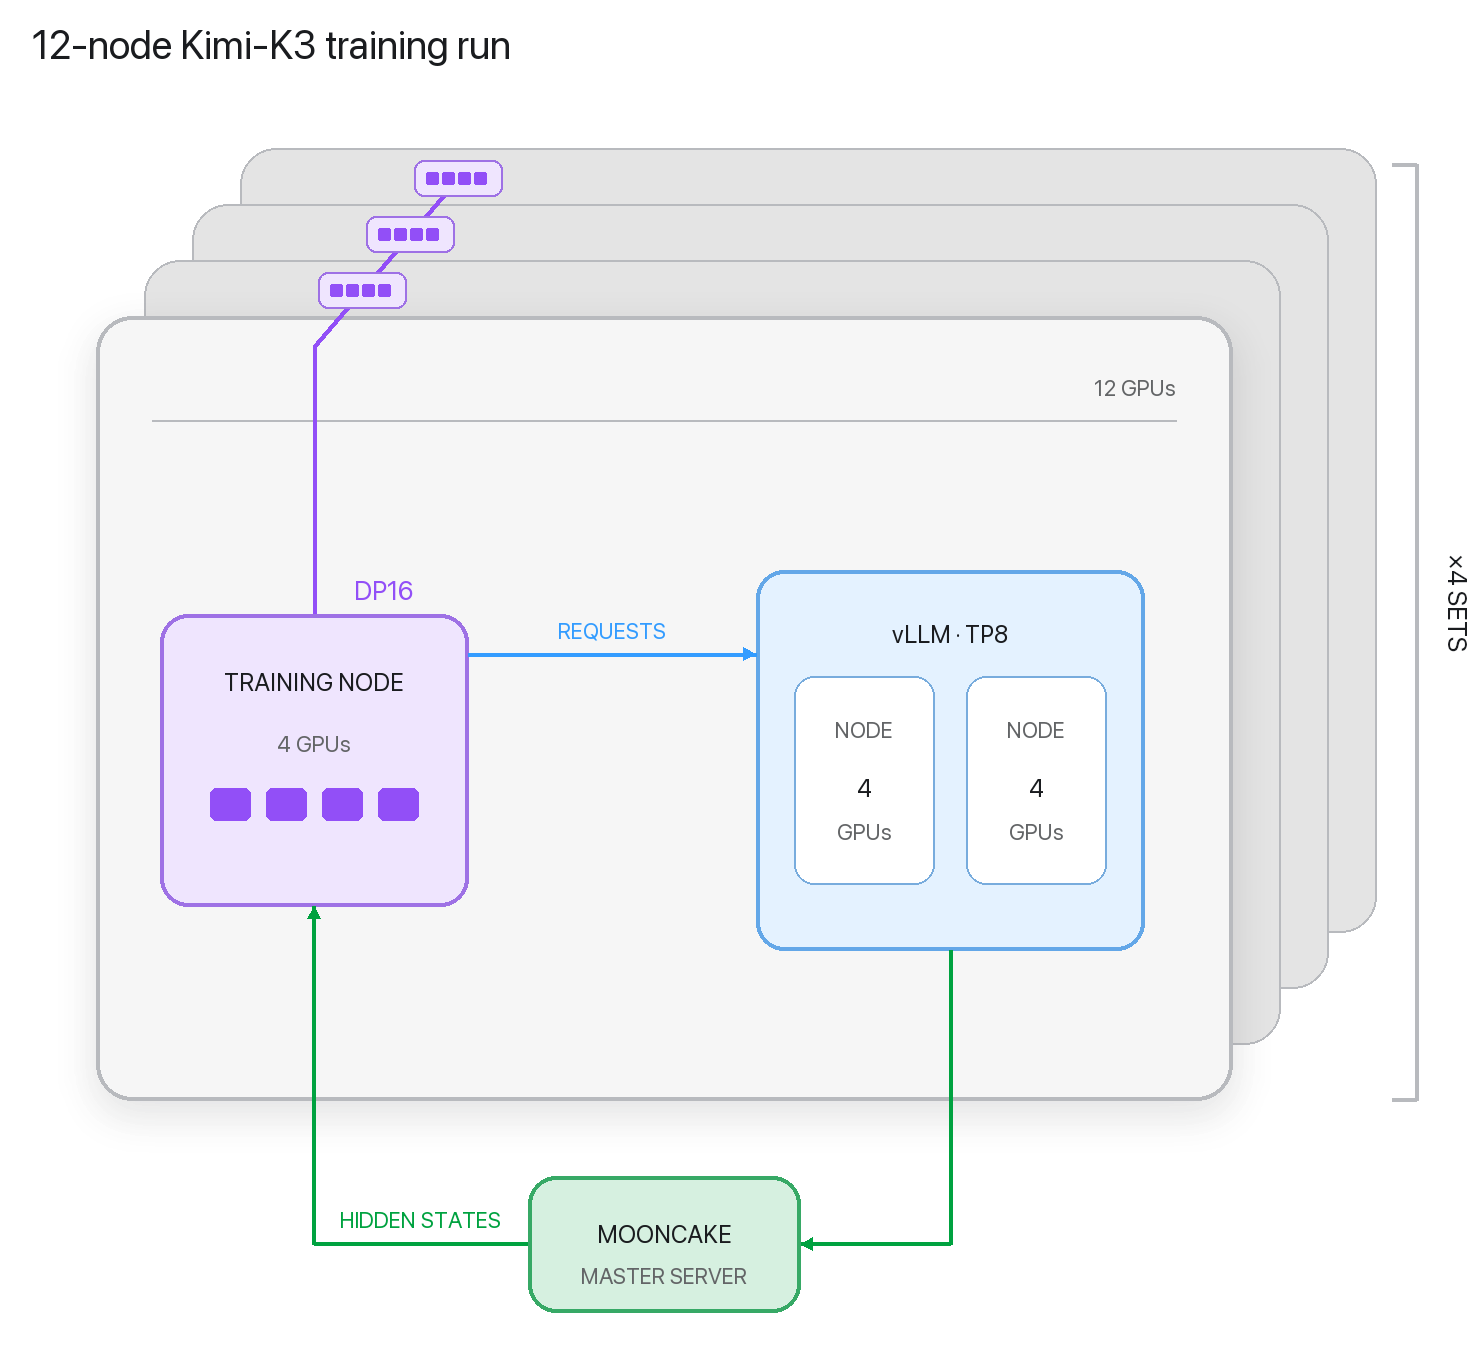
Figure 4. Each four-node set dedicates one four-GPU node to training and two four-GPU nodes to vLLM inference, with Mooncake transferring hidden states.
With the new MooncakeHiddenStatesConnector in hand, we now have a system capable of scaling to large-model, multi-node training. Even with Kimi K3 quantized to 4 bits, the model still requires at least two GB300 nodes (four GPUs each) to serve. We experimented with different training and vLLM configurations and found that sets of three nodes—two for inference and one for training—offered the best throughput. Another advantage of Speculators with the Mooncake connector is how easy it is to independently scale either component up or down for the best performance.
Conclusion
Speculators is an open-source library for building, training, evaluating, and sharing speculative decoding models that integrate directly with inference engines such as vLLM. Whether you are training a new draft model, exploring algorithms such as DFlash, DSpark, or DFlash2, or improving production inference performance, we welcome your ideas and contributions. Join the vLLM Community Slack and find us in #speculators and #feat-spec-decode to ask questions, share results, discuss new algorithms, and collaborate with the community. Contributions to the code, documentation, examples, model support, and evaluation tooling are all welcome.