要点速览
- DaoCloud 用 3 台 8 卡 B300(共 24 GPU)以 4 Prefill + 1 Decode 的 disaggregated 拓扑部署 GLM-5.2-NVFP4,SLA 目标为 mean TTFT ≤ 2.5 s、mean TPOT ≤ 20 ms。
- 最大单项优化是 Decode 侧 speculative padding:消除 P/D 交接处 mixed batch 导致的 CUDA Graph 快路径退化,mean TPOT 从约 40 ms 降到约 22 ms。
- 叠加 Model Runner V2(约 -11% TPOT)、FlashInfer NVLink A2A 后端(约 -4%)、FULL_DECODE_ONLY CUDA Graph 与不对称 MTP 配置,最终 TPOT 到 17 ms。
- Prefill 没有选 TGS 最高的 TP1 DP2 EP,而是选 TP1 DP4 EP:牺牲约 8% 每 GPU 效率换取 4 卡实例的 KV cache 容量,保住 1M 上下文能力。
- 上线后按 Prefill/Decode 资源池分别监控 TTFT/TPOT 分位数并把 MTP acceptance rate 当一级告警指标;多日长稳测试还揪出一个 host 内存无限增长问题。
解决什么问题
GLM-5.2 是 744B 参数、40B 激活的 MoE 模型(DSA 稀疏注意力 + 原生 MTP),在 24 张 B300 上做生产部署时 Decode 侧 mean TPOT 接近 40 ms,约为 SLA 上限(20 ms)的两倍且伴随明显 P99 抖动。文章要解决的是在 mean TTFT ≤ 2.5 s、mean TPOT ≤ 20 ms 两个硬约束下,如何系统地把延迟压进预算并保证上线后的长期稳定性,而不是单纯冲峰值吞吐。所有优化都在约束感知(constraint-aware)的框架下进行:一个提升 30% 吞吐但把 TPOT 推过 SLA 的配置没有价值。
核心思路
以 P/D disaggregation(4 Prefill TP1 DP4 EP + 1 Decode TP1 DP8 EP,NIXL 传输)为起点,先通过 profiling 定位到 P/D 交接处 MTP 混合批次使 Decode 掉出 full-CUDA-Graph 快路径,用 speculative padding(PR #45237)修复后 mean TPOT 从约 40 ms 降到约 22 ms。随后叠加 Model Runner V2、FlashInfer NVLink A2A 后端、FULL_DECODE_ONLY CUDA Graph 与不对称 MTP 配置(Decode 3 个 speculative tokens、Prefill 1 个),把 TPOT 进一步压到 17 ms。Prefill 并行策略在 TGS 与 KV cache 容量之间做生产取舍,放弃 8% 每 GPU 效率选择 TP1 DP4 EP。再用 IndexerCache 及配套修复稳住 MTP acceptance rate,用公开基准验证精度,最后为 P/D 拓扑建立分池监控并通过多日长稳验收(顺带定位并修复了一个 host 内存泄漏)。
关键要点
- SLA 优先:为什么以 P/D disaggregation 为起点 — 生产服务不看峰值吞吐,而看在不违反延迟目标的前提下能扛多少流量。colocated serving 中长 prompt 混入 decode 批次会拉高所有在途请求的 inter-token latency,TPOT 尾延迟成为不受系统控制的输入分布函数;disaggregation 把 prefill 移出 decode 关键路径,使 TPOT 只取决于 decode 批次构成,这才让紧的 TPOT SLA 可达成。负载按请求速率施加而非固定并发:8K/16K/256K 输入下并发分别约 700/300/25,全部封顶在 --max-concurrency 1024 之下。
- 根因定位:P/D 交接处的 mixed batch — 请求经 KVConnector 把 prompt KV cache 转移到 Decode 节点后,首个 Decode step 只需计算 1 个 token;而 MTP 开启时已有请求每步计算 1+N 个 token。两种请求形状不同形成 mixed batch,无法走 uniform-decode 的 full-CUDA-Graph 快路径,回退到更昂贵的 piecewise/eager 执行路径。DP 会放大影响:CUDA Graph 模式与 padding 需要跨 rank 协调,任一 rank 收到新请求,其余 rank 也跟着走慢路径;稳态 P/D 下新请求持续到达,慢路径被持续触发。
- 最大单项收益:Speculative Padding(PR #45237) — 修复方式是在请求到达后的首个 Decode step 用 dummy speculative tokens 把形状补齐到 1+N,与 Decode worker 中已有请求保持一致,从而保住 uniform Decode 执行和 full-CUDA-Graph 快路径,且无需从 Prefill 节点传输生成 token 或 draft token。该修复使端到端 mean TPOT 从约 40 ms 降到约 22 ms,是整个优化过程中最大的单项收益。更普遍的教训:最大的性能损失可能不在任何单个 kernel,而在子系统边界——请求状态、调度形状与 CUDA Graph 执行模式的小不一致被 DP 规模和持续流量放大。
- Model Runner V2 带来的三项关键能力 — MRV2 重构了运行时执行路径,v0.25.0 起为 dense 模型默认;GLM-5.2 是 MoE 模型需用 VLLM_USE_V2_MODEL_RUNNER=1 显式开启,在本配置下 TPOT 相对 MRV1 再降约 11%。PR #47285 把 GLM-5.2 DSA indexer 的 prefill-metadata kernel 加入启动 warmup,避免生产首个请求触发 Triton JIT 编译的冷启动尖峰(基准测试的 warmup 会吸收它,生产环境则在每次滚动发布后暴露);PR #46448 为多 GPU MTP 增加 local argmax reduction,draft token 生成不再 AllGather 全词表 logits,TP 通信量从正比于词表规模降到约 2×TP size;PR #45953 让动态投机长度与 full CUDA Graph 兼容,减少 draft 长度变化导致的 graph miss 与 eager 回退。
- MoE 通信后端与 CUDA Graph / MTP 配置 — GLM-5.2 是 MoE,Decode 侧 DEP8 使 expert dispatch/combine 通信直接落在关键路径上;用 FlashInfer NVLink A2A 后端 flashinfer_nvlink_two_sided 替换默认 AllGather/ReduceScatter EP 后端,TPOT 再降约 4%(更新的 one_sided 后端预计更好但未在本文测量)。CUDA Graph 采用 FULL_DECODE_ONLY 加 --max-num-batched-tokens 1024:Decode 不需要 prefill 形状的图,既保证 Decode 路径全覆盖又显著缩短启动编译时间。MTP 配置刻意不对称:Decode 侧 num_speculative_tokens=3、Prefill 侧为 1——Prefill 要尽快产出并移交 KV cache,更深的投机收益小;Decode 在延迟关键路径上,只要 acceptance rate 够高,更深的投机能摊薄每 token 执行成本。
- Prefill 并行策略:放弃 TGS 最优的生产取舍 — 在 8K/32K 输入下比较多种并行策略,因配置所用 GPU 数不同,TGS(每 GPU 吞吐)才是公平指标。TP1 DP4 EP 绝对吞吐最高(8K 输入 47,806 tok/s)但只因用了两倍 GPU,按每 GPU 只排第二;TP2+EP 在仅两卡规模上 all-to-all 开销超过收益,反而不如纯 TP2——EP 需要足够的 expert 分布在足够多的设备上才能摊薄通信成本。TGS 最优的 TP1 DP2 EP 每实例只有 2 卡,KV cache 容量撑不起 GLM-5.2 的 1M 上下文能力,团队不愿为 8% TGS 优势放弃模型最重要的特性之一,最终选择 TP1 DP4 EP。上游 PCP 虚拟批处理(PR #46570,已合入 main)在 4 GPU 32K Prefill 测试中把 prompt 吞吐从约 20.1K 提到约 27.3K tok/s,可能在未来改变这一取舍。
- IndexerCache:让 MTP 在 DSA 模型上划算且稳定 — IndexerCache(PR #44420)复用 DSA indexer 产生的 Top-K 稀疏索引而非传统 KV cache;朴素实现每个 MTP draft step 都重跑 indexer,而稀疏检索成本随上下文增长,会吃掉投机解码的预期收益。index_share_for_mtp_iteration 让首个 draft step 计算 Top-K、后续复用,这是 MTP 在 GLM-5.2 上划算的前提。PR #45895 修复 GLM-5.2 MTP 归一化循环等,使 GLM-5.2-FP8 TP=8 下 mean accepted length 从约 3 升至约 4(平均 acceptance rate 约 60%,IFBench 保持 74.62);PR #47238 优化批处理请求的共享索引 buffer 布局,把索引共享从单请求扩展到高并发批处理;PR #47448 让 MTP 循环复用 post-final-norm 隐藏态。精度上最终配置 AIME 2025 86.67、GPQA 92.89、LongBench V2 64.01、MMLU-Pro 86.3、SWE-bench Verified 85.2,与社区报告一致,其中 LongBench V2 直接检验长上下文下 DSA 与索引共享的质量。
- P/D 可观测性与长稳测试揪出的内存泄漏 — disaggregated 部署的请求时延拆在两个资源池上(TTFT 主要由 Prefill 决定、TPOT 由 Decode 决定,中间夹一次 KV 传输),因此要按池监控 TTFT/TPOT 分位数、MTP acceptance rate 与 mean accepted length(最早期预警信号——它下降不报错、TPOT 只是逐渐劣化,建议作为一级告警指标)、KV cache 与 GPU 利用率对比、KV 传输延迟与队列深度。多日长稳测试发现 vLLM 进程 RSS 从约 721 GiB 线性涨到约 800 GiB:增长慢到秒级基准看不见、发生在 host 内存而非 GPU、且 EngineCore 启动时 gc.freeze() 使 gc.get_objects()/tracemalloc 全部失明,症状像 allocator 碎片。根因是 PR #35219 引入的 SingleTypeKVCacheManager.new_block_ids 只按 cache spec 类型记录新块、却仅在模型含 Mamba 层时清理,非 Mamba 模型(含 GLM-5.2 with MLA)列表无限增长;修复(经 PR #47723 报告、合入 PR #44490)是在每个调度步无条件 drain take_new_block_ids() 并只在真正需要清理时使用其结果。
关键数据
| 指标 | 数值 | 条件 |
|---|---|---|
| SLA 目标 mean TPOT | ≤ 20 ms(约 50 tokens/s 流式输出) | GLM-5.2-NVFP4 / 24× B300 / 16K–256K 上下文生产 SLA |
| 优化前 mean TPOT | 约 40 ms(约为 SLA 上限两倍) | GLM-5.2-NVFP4 / B300 / 16K 输入 + 1K 输出,初始配置 |
| speculative padding 后 mean TPOT | 约 22 ms(从约 40 ms) | 同硬件同负载,消除混合批次执行路径回退后 |
| 最终 mean TPOT | 17 ms | 全部优化叠加后的最终生产配置 |
| MRV2 相对 MRV1 的 TPOT 改善 | 约 11% | GLM-5.2 Decode 配置(TP1 DP8 EP) |
| FlashInfer NVLink A2A 后端 TPOT 改善 | 再降 4% | MoE DEP8 Decode 侧,flashinfer_nvlink_two_sided 替换默认 EP 后端 |
| Prefill 绝对吞吐 | 47,806 tok/s | 8K 输入,TP1 DP4 EP 实例(绝对最快但每 GPU 仅第二) |
| MTP mean accepted length | 约 3 → 约 4(平均 acceptance rate 约 60%) | GLM-5.2-FP8 / TP=8 / PR #45895 修复后,IFBench 保持 74.62 |
| PCP 虚拟批处理 prompt 吞吐 | 约 20.1K → 约 27.3K tok/s | 4-GPU GLM-5.2-NVFP4 / 32K Prefill / TP=2 + PCP=2(PR #46570) |
| 长稳测试 host 内存增长 | 约 721 GiB → 约 800 GiB(数十小时线性增长) | 多日连续运行下的 vLLM 容器内存(WSS 面板) |
| LongBench V2 精度 | 64.01 | 最终配置(NVFP4 + MTP + P/D)公开基准,检验长上下文 DSA 与索引共享 |
| SLA 约束下的并发水平 | 约 700(8K)/ 300(16K)/ 25(256K) | 固定请求速率负载,--max-concurrency 1024 封顶 |
“**Mean TPOT ≤ 20 ms** — roughly 50 tokens/s of streaming output; below this rate, the reading experience degrades noticeably”
“Our starting point on the same hardware was a mean TPOT of nearly 40 ms for 16K-token inputs — roughly twice our SLA limit.”
“With the execution-path regression caused by mixed batches eliminated, end-to-end mean TPOT dropped from approximately 40 ms to approximately 22 ms — the single largest improvement of the entire effort.”
前置知识
P/D disaggregation(Prefill/Decode 分离)基本原理与 KVConnector、NIXL 等 KV 传输组件 · MTP speculative decoding 机制:draft/verify 流程、acceptance rate、num_speculative_tokens · CUDA Graph 捕获与 replay,以及 piecewise/full 模式对执行路径和性能的影响 · MoE 模型并行策略:TP/DP/EP 组合(如 DEP8)与 expert all-to-all 通信 · DSA(DeepSeek Sparse Attention)稀疏注意力与 Top-K 索引机制 · SLO/SLA 概念与 Prometheus/Grafana 监控实践
术语表
P/D disaggregation: 把 prefill 与 decode 拆到不同节点/资源池的部署架构,使 TPOT 不再受 prefill 批次干扰,两类资源可独立扩缩。MTP: Multi-Token Prediction,一种投机解码方法,模型同时预测多个未来 token,由目标模型验证后一次产出多个 token。TPOT: Time Per Output Token,平均每输出 token 时延,衡量流式输出的流畅度。TTFT: Time To First Token,用户动作到首个可见 token 的时延。CUDA Graph: 将 GPU kernel 序列录制成图一次性 replay 以消除 CPU 启动开销;混合形状批次会使其退化为 piecewise/eager 慢路径。Speculative padding: 在首个 decode step 用 dummy draft token 把新请求形状补齐到 1+N,保持 uniform decode 批次以留在 CUDA Graph 快路径。DSA: DeepSeek Sparse Attention,通过 Top-K 稀疏索引降低长上下文注意力计算与访存开销。IndexerCache: 复用 DSA indexer 产生的 Top-K 稀疏索引的缓存机制,是 MTP 在 GLM-5.2 上具备收益的前提。MRV2: vLLM Model Runner V2,重构后的运行时执行路径,v0.25.0 起为 dense 模型默认,MoE 需显式开启。TGS: Throughput per GPU,每 GPU 吞吐,比较不同 GPU 数量的配置时的公平指标。DEP: Data Parallel + Expert Parallel 的组合并行方式,MoE Decode 侧常用(如 DEP8)。NIXL: vLLM 使用的 KV cache 跨节点传输连接器/传输库,P/D 之间经 KVConnector 交接状态。PCP: Prefill Context Parallelism,把请求拆成多个虚拟批次行在 context-parallel rank 间并行处理长 prompt。RSS: Resident Set Size,进程驻留内存大小,本文长稳测试监控的 host 内存指标。
From Day 0 to Production SLAs: Serving GLM-5.2 on 24 NVIDIA B300 GPUs with vLLM
TL;DR
We deployed GLM-5.2-NVFP4 across three 8-GPU B300 servers (24 GPUs in total) using a disaggregated 4-Prefill + 1-Decode topology. Under our production SLA targets of mean TTFT ≤ 2.5 s and mean TPOT ≤ 20 ms, we measured the following:
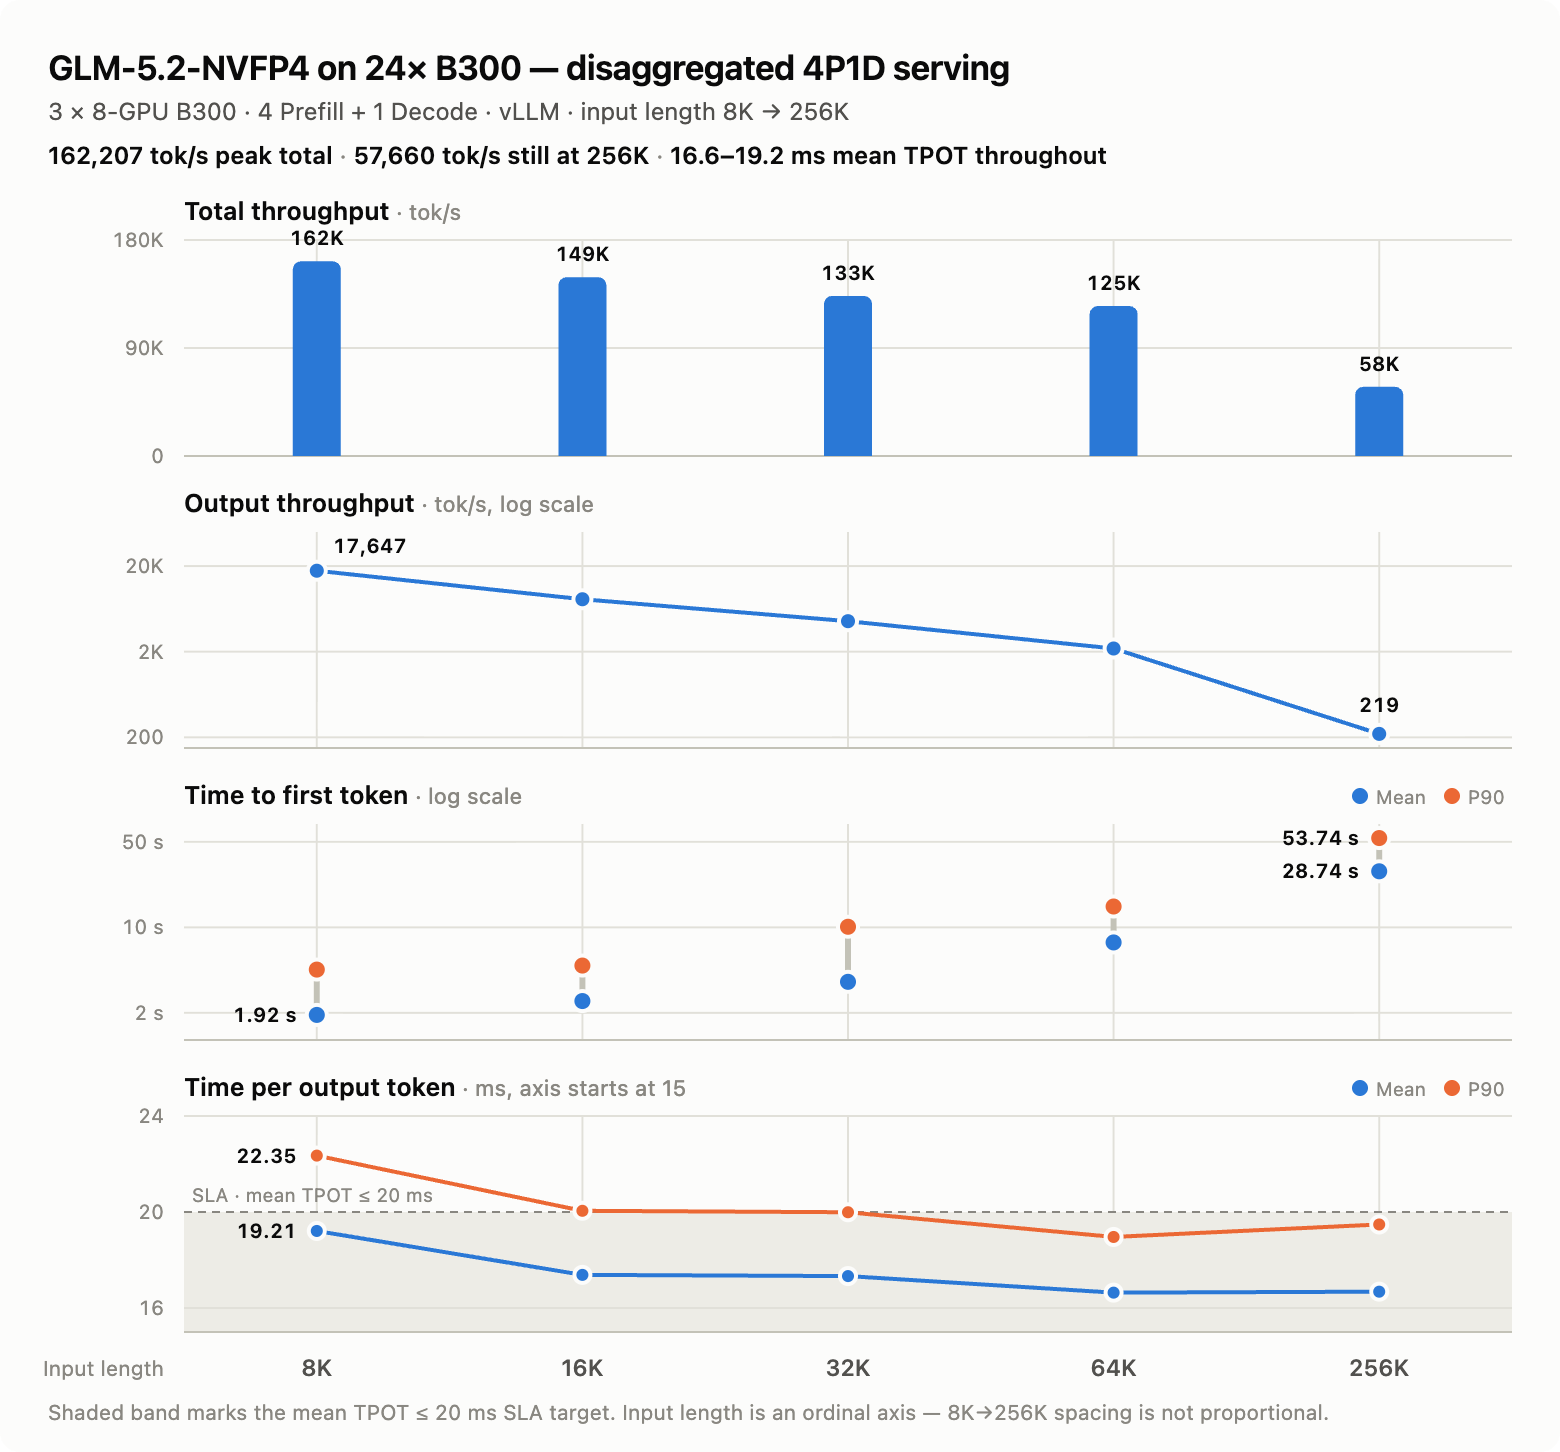
Our starting point on the same hardware was a mean TPOT of nearly 40 ms for 16K-token inputs — roughly twice our SLA limit. This post documents the full journey from 40 ms to 17 ms: what we changed at each step, how much each change contributed, and why the parallelism strategy we shipped is not the one with the highest raw throughput. A complete, reproducible set of vllm serve commands is included at the end.
1. Why We Optimized for SLA Compliance, Not Peak Throughput
In colocated serving, prefill chunks are interleaved into decode batches, and every long prompt entering a batch stretches the inter-token latency of every request already decoding. TPOT tail latency therefore becomes a function of the incoming prompt length distribution — something a serving system does not control. Disaggregation removes prefill work from the decode critical path entirely, making TPOT a function of decode batch composition alone. That is what makes a tight TPOT SLA achievable in the first place, and it is why the rest of this post treats P/D as the starting point rather than as one optimization among many.
Production services are not accepted on peak throughput alone. The real question is how much traffic the system can sustain without violating latency targets. Our requirements were explicit:
- Typical context length: 16K–256K tokens
- Mean TTFT ≤ 2.5 s — the maximum acceptable delay between a user action and the first visible token
- Mean TPOT ≤ 20 ms — roughly 50 tokens/s of streaming output; below this rate, the reading experience degrades noticeably
- Subject to those two hard constraints, maximize throughput
A note on batch size: we did not fix one. Load is applied as a request rate, and concurrency is whatever that rate produces under the SLA — deliberately as large as the latency budget allows. Because prefill cost grows with context length, concurrency settles lower as input length rises: roughly 700 concurrent requests at 8K, 300 at 16K, and 25 at 256K, all under a --max-concurrency 1024 cap.
This objective shaped the methodology throughout: every configuration search was constraint-aware. A configuration that improves throughput by 30% but pushes mean TPOT past the SLA is not useful to us. Section 4 contains a representative example.
GLM-5.2 is a 744B-parameter MoE model with 40B active parameters. It uses DSA sparse attention and natively supports MTP speculative decoding, and vLLM already provides mature support for all three. Our work was to combine them effectively with P/D disaggregation, then tune parameters, topology, and scheduling around production SLA targets.
2. Starting Point: Improving Decode Performance under P/D Disaggregation
With the initial configuration, the Prefill side already met its target and had ample TTFT headroom. The bottleneck was Decode: with 16K input tokens and 1K output tokens, mean TPOT was close to 40 ms, with substantial P99 jitter.
2.1 Root Cause: Mixed Batches at the P/D Handoff
Speculative decoding has become a standard inference-time optimization for large MoE models, and production Decode deployments increasingly run it by default. Profiling revealed an issue that sits precisely at the interaction between P/D disaggregation and speculative decoding.
After a request transfers its prompt KV cache to a Decode node through KVConnector, its first Decode step needs to compute only one token. Existing requests on that Decode node, however, are scheduled with 1 + N tokens per step when MTP is enabled. Because the two request types have different shapes, the step becomes a mixed batch. It can no longer take the uniform-decode full-CUDA-Graph fast path and instead falls back to the more expensive piecewise or eager execution path.
Data parallelism amplifies the impact. Under DP, CUDA Graph mode and padding require coordination across ranks, so if any DP rank receives a newly transferred request, the remaining ranks follow it onto the same execution path. In steady-state P/D operation, new requests arrive at the Decode instance continuously, so the slow path is triggered constantly.
2.2 Optimization: Speculative Padding on the Decode Side
The fix is conceptually simple. On the first Decode step after a request arrives, dummy speculative tokens pad its shape to 1 + N, matching the other requests already in the Decode worker. This preserves uniform Decode execution and keeps the workload on the full-CUDA-Graph fast path.
It requires no transfer of generated tokens or draft tokens from the Prefill node. The optimization was merged by the vLLM community in PR #45237.
2.3 Performance Gain
With the execution-path regression caused by mixed batches eliminated, end-to-end mean TPOT dropped from approximately 40 ms to approximately 22 ms — the single largest improvement of the entire effort.
The result carries a broader lesson for deployments that combine P/D disaggregation with speculative decoding: the largest performance loss may not live in any individual kernel. It can arise at the boundary between subsystems, where small inconsistencies in request state, scheduling shape, and CUDA Graph execution mode are amplified by DP scale and continuous traffic.
3. Further Decode-Side Optimizations
At 22 ms we were close to the SLA but had no safety margin, so we ran another round of configuration search.
3.1 Model Runner V2: 11% Lower TPOT
vLLM Model Runner V2 (MRV2) refactors the runtime execution path. Since v0.25.0 it is the default for all dense models; GLM-5.2 is an MoE model, so it is not enabled by default and must be activated explicitly with VLLM_USE_V2_MODEL_RUNNER=1.
On our Decode configuration, MRV2 improved TPOT by approximately 11% over MRV1. Beyond the shorter execution path, MRV2 brings several capabilities that matter for predictable production latency:
- PR #47285 adds the GLM-5.2 DSA indexer prefill-metadata kernel to startup warmup, so the first production request no longer triggers Triton JIT compilation and a latency spike. This is easy to miss in benchmarks, where warmup absorbs it; in production it shows up as a cold-start spike after every rolling deployment.
- PR #46448 adds local argmax reduction for multi-GPU MTP. With
use_local_argmax_reductionenabled, draft-token generation no longer AllGathers full-vocabulary logits, reducing TP communication from a volume proportional to vocabulary size to approximately 2 × TP size. MTP, EAGLE, DFlash, and other speculators running under MRV2 all benefit. - PR #45953 lets dynamic speculative lengths work with full CUDA Graphs, reducing graph misses and eager fallbacks caused by changes in draft length.
3.2 All-to-All Backend: 4% Lower TPOT
Because GLM-5.2 is an MoE model, the Decode side runs DEP8, which places expert dispatch and combine communication directly on the critical path. We replaced the default AllGather/ReduceScatter-based EP backend with the FlashInfer NVLink A2A backend; in our measurements, flashinfer_nvlink_two_sided cut TPOT by a further 4%.
vLLM now also ships the newer flashinfer_nvlink_one_sided backend, which is expected to perform better. This post keeps the two-sided backend because that is the configuration we actually measured. Evaluating the one-sided backend under the same Decode workload is on our list.
3.3 CUDA Graph Mode
The Decode instance runs --compilation-config '{"cudagraph_mode":"FULL_DECODE_ONLY"}' together with --max-num-batched-tokens 1024. The Decode side does not need graphs compiled for prefill shapes, and FULL_DECODE_ONLY gives complete graph coverage of the Decode path while cutting startup compilation time significantly.
3.4 MTP Speculative Decoding
We use num_speculative_tokens=3 on the Decode side and 1 on the Prefill side. (MTP only becomes cost-effective on GLM-5.2 together with IndexerCache, discussed in Section 5.) The asymmetry is intentional: Prefill nodes should produce and hand off KV cache as fast as possible, so deeper speculation buys little there. Decode nodes sit on the latency-critical path, where deeper speculation amortizes the execution cost per token — provided the acceptance rate stays high.
4. Prefill Parallelism: Why We Did Not Choose the Highest-Throughput Configuration
On the Prefill side we compared several parallelism strategies at 8K- and 32K-token inputs. Since the configurations use different numbers of GPUs, TGS — throughput per GPU — is the meaningful metric.
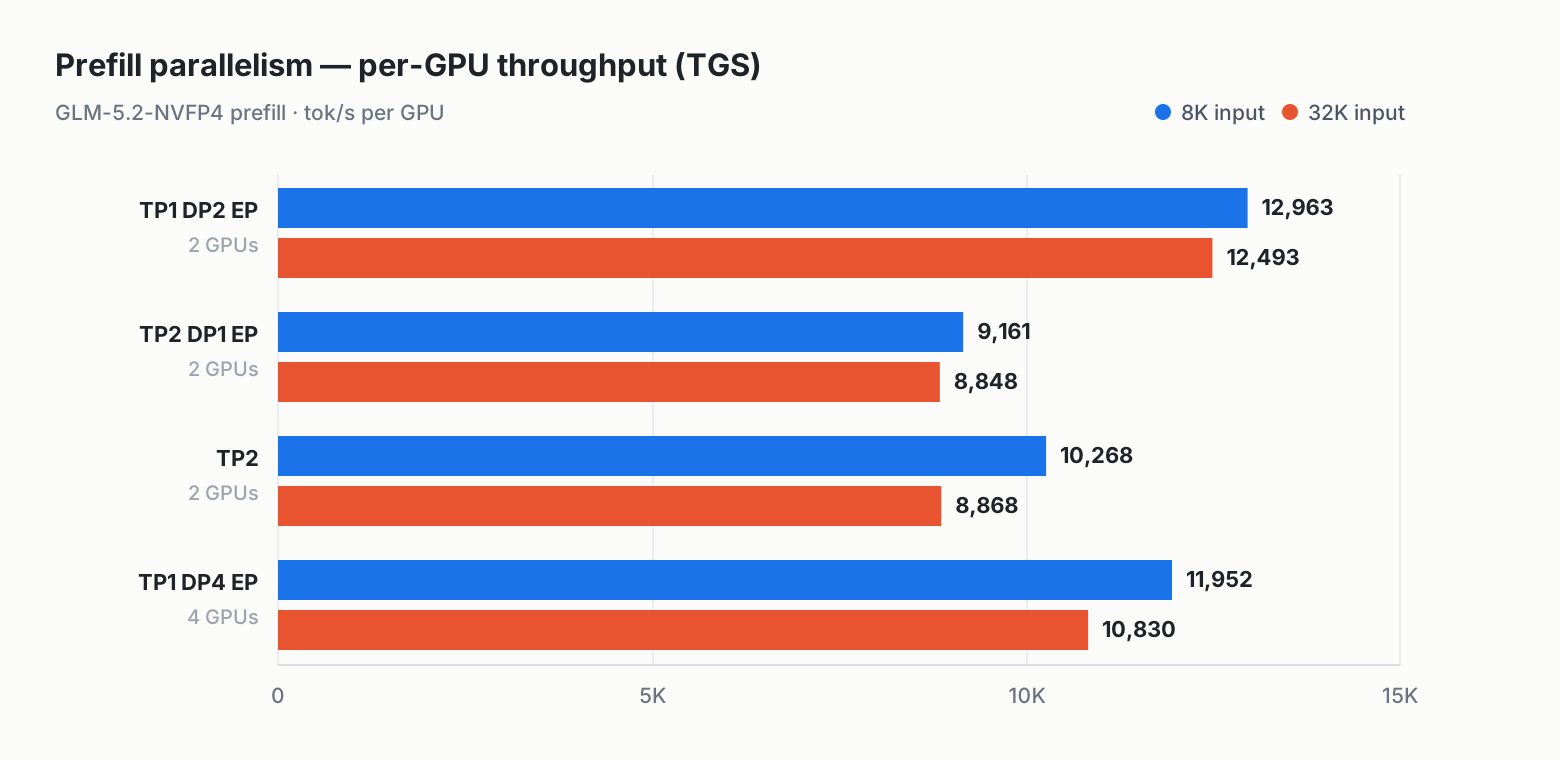
Per-GPU prefill throughput for four parallelism strategies, at 8K and 32K input lengths.
In absolute terms TP1 DP4 EP is the fastest instance — 47,806 tok/s at 8K inputs — but only because it uses twice as many GPUs as the others; per GPU it lands second. Two conclusions stand out:
- TP2 + EP performed worse than plain TP2. At a scale of only two GPUs, the all-to-all overhead introduced by EP exceeds its benefit. EP needs enough experts spread across enough devices to amortize its communication cost.
- TP1 DP2 EP achieved the best TGS, but we shipped TP1 DP4 EP.
The second point is where production engineering parts ways with benchmark chasing. TP1 DP2 EP delivered the best per-GPU efficiency, but each instance had only two GPUs, leaving too little KV-cache capacity for GLM-5.2's 1M-token context capability. We were not willing to give up one of the model's most important features for an 8% TGS advantage, so we chose TP1 DP4 EP — trading roughly 8% of per-GPU efficiency for the KV-cache capacity of four GPUs per instance.
5. MTP + IndexerCache: How We Improved the Acceptance Rate
vLLM has been extensively validated in production under conventional configurations. This deployment enabled three relatively new capabilities at once — P/D disaggregation, MTP, and MRV2 — which put us on a less frequently exercised combination path, and the tuning process surfaced several long-tail issues. Most fixes went from report to release within a few days; anyone on v0.26.0 already has all of them. This section records the work to show how MTP acceptance was stabilized step by step.
5.1 IndexerCache: Making MTP Cost-Effective with DSA
IndexerCache (PR #44420) is not a conventional KV cache — it reuses the Top-K sparse indices produced by the DSA indexer. A naive implementation reruns the indexer for every MTP draft step, and since sparse-retrieval cost grows with context length, that can consume much of the benefit expected from speculative decoding. PR #44420 introduced index_share_for_mtp_iteration, which lets the first draft step compute Top-K indices and subsequent draft steps reuse them. This is a prerequisite for MTP to be worthwhile on GLM-5.2 at all.
The community then completed three improvements around this mechanism, which together stabilized acceptance under high concurrency:
- PR #45895 improves indexer initialization when Top-K layers are skipped and fixes the GLM-5.2 MTP normalization loop. The PR reports that on GLM-5.2-FP8 with TP=8, mean accepted length rose from approximately 3 to approximately 4, at an average acceptance rate of about 60%, while IFBench held at 74.62.
- PR #47238 optimizes the layout of the shared index buffer for batched requests: after the first draft step, it retains only the Top-K indices corresponding to each request's final query token. This was the key step in extending index sharing from single-request execution to high-concurrency batching.
- PR #47448 ensures the MTP loop reuses the post-final-norm hidden state.
Taken together, IndexerCache is not merely a compute-saving optimization. It is also a key mechanism for holding MTP acceptance rates up under high concurrency.
5.2 Two Additional Fixes for the Combined Configuration
MRV2 scheduling classification. After switching to MRV2, we observed excessive TPOT variance under a specific benchmark pattern and reported it in Issue #47239. The community quickly traced it to uniform-decode ordering: speculative-decoding steps were being classified as prefill and therefore took a slower execution path. PR #47381 fixed it.
Lookahead handling for asynchronous KV loading in P/D deployments. PR #46694 improves slot-allocation timing for the combined GLM-5.2 + NIXL P/D + MTP configuration. The Decoder now waits until remote KV transfer completes before allocating speculative-token slots, correctly handling the boundary case of a final partial KV block. This partial-block handoff is specific to the interaction between P/D disaggregation and speculative decoding, and fixing it was another step toward making the path production-ready.
Both fixes are included in v0.25.0 and later releases.
5.3 Accuracy Validation
We ran a set of public benchmarks with the final configuration to verify that combining NVFP4 quantization, MTP, and P/D disaggregation did not reduce output quality:
| Test Item | Score |
|---|---|
| AIME 2025 | 86.67 |
| GPQA | 92.89 |
| LongBench V2 | 64.01 |
| MMLU-Pro | 86.3 |
| SWE-bench Verified (Agentic) | 85.2 |
The results are consistent with community-reported GLM-5.2 numbers. LongBench V2 mattered most to us because it directly exercises DSA sparse attention and IndexerCache index sharing under long contexts. A score of 64.01 indicates that index sharing holds up in long-context workloads, and that the speedup from speculative decoding did not come at the expense of output quality.
6. Upstream Progress
The capabilities used in this deployment build on a broader set of optimizations coordinated by the vLLM community under the GLM-5.2 optimization tracking issue, Issue #46654. Beyond the PRs referenced above, two developments are especially relevant.
A secondary tier for P/D disaggregation. PR #42285 introduces a unified CPU KV-cache layout as an intermediate layer. TieringManager coordinates the primary cache tier and the P/D connector, reducing coupling between the transfer backend and the model execution path. Merged in v0.25.0.
PCP virtual batching for long-context Prefill. PR #46570 splits requests into multiple virtual batch rows processed in parallel across context-parallel ranks, aggregating only the MLA latent cache and DSA indexer cache. In an initial 4-GPU GLM-5.2-NVFP4 / 32K Prefill test, TP=2 with PCP=2 raised prompt throughput from approximately 20.1K tok/s to approximately 27.3K tok/s. The PR was merged into main on July 19, 2026, and will ship in the next release. Since KV-cache capacity is exactly why we rejected the TGS-optimal configuration in Section 4, PCP may change that trade-off, and it is a key focus of our next validation phase.
7. Observability: Verifying the SLA after Production Launch
Passing a benchmark does not make a system production-ready. Observability is harder for a disaggregated P/D deployment than for a single instance, because request latency is split across two resource pools: TTFT is determined mostly by the Prefill pool, TPOT by the Decode pool, with a KV transfer in between. When any stage degrades, users see only one symptom — the service got slower.
We built monitoring for the P/D topology with Prometheus and Grafana. In production we watch the following metric groups:
- Per-pool TTFT and TPOT percentiles, not just end-to-end aggregates. This is the first place to look to decide whether a problem belongs to Prefill or Decode.
- MTP acceptance rate and mean accepted length. Easy to overlook, yet among the earliest warning signals available. A declining acceptance rate produces no error; TPOT simply degrades gradually. In practice this is the first dashboard we open for any Decode-side anomaly, and we recommend treating MTP acceptance rate as a first-class alerting metric.
- KV-cache utilization versus GPU utilization, on both the Prefill and Decode sides. The central benefit of P/D disaggregation is that the two resource types scale independently; the relative levels of these curves are the scaling signal.
- KV-transfer latency and queue depth, to determine whether the inter-node network has become the bottleneck.
7.1 A Problem Visible Only during Long-Running Stability Tests
Short benchmarks validate performance, not long-term stability. Our production acceptance process includes multi-day continuous runs, and that step revealed persistent host-memory growth: vLLM process RSS increased linearly over tens of hours without reaching a plateau.
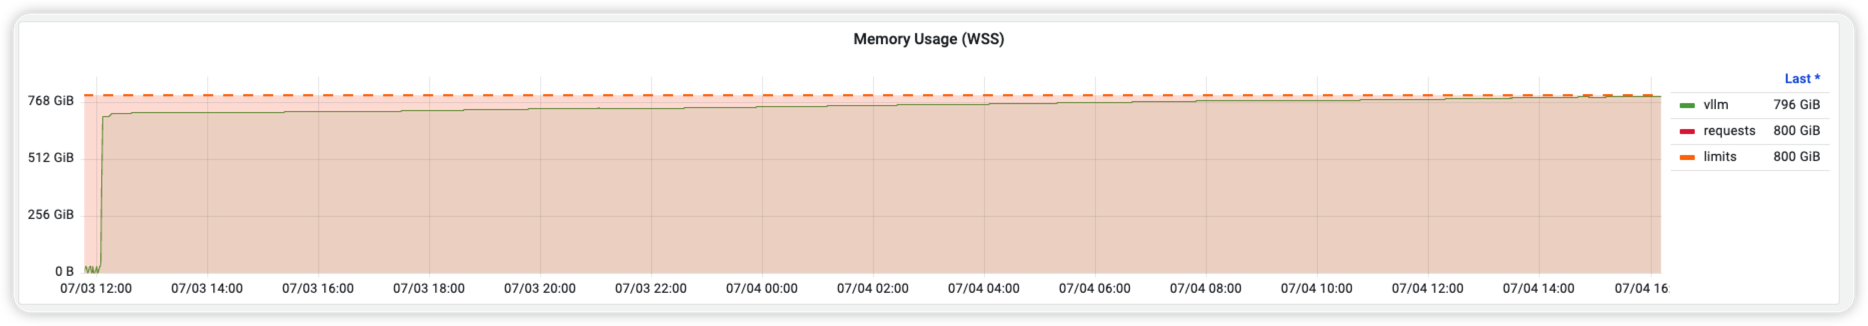
Grafana Memory Usage (WSS) panel: vLLM container memory grew linearly from approximately 721 GiB to approximately 800 GiB over tens of hours.
Several characteristics explain why this issue needed production monitoring, rather than a benchmark, to be discovered:
- The growth rate was slow and only visible over hours. A
vllm bench serverun lasting seconds or minutes could not reveal it. - The growth affected host memory, not GPU memory. Every GPU-side metric looked normal.
- Conventional memory-analysis tools could not see it.
EngineCorecallsgc.freeze()during startup, so the leaked objects never appeared ingc.get_objects()ortracemalloc; the symptom looked like allocator fragmentation.
We reported the behavior and our initial diagnosis to the community in PR #47723, and a maintainer incorporated it into PR #44490.
The root cause was inconsistent gating between a producer and a consumer. PR #35219 had introduced SingleTypeKVCacheManager.new_block_ids for clearing Mamba SSM cache state. Entries were recorded based on the KV-cache spec type — FullAttentionSpec, MLAAttentionSpec, and so on — but cleared only when the model contained Mamba layers. For models without Mamba layers, which includes most standard attention models and GLM-5.2 with MLA, every block allocation was recorded and the list was never drained, so it grew without bound as request volume increased. The fix was to drain take_new_block_ids() unconditionally on every scheduling step and use its result only when clearing is actually required. Mamba behavior is unchanged.
8. Complete Deployment Recipe
8.1 Environment
| Deployment | Configuration |
|---|---|
| Hardware | 3 × 8 B300 (24 GPUs) |
| Model | GLM-5.2-NVFP4 |
| Topology | 4 Prefill (TP1 DP4 EP, 4 GPUs each = 16) + 1 Decode (TP1 DP8 EP = 8) |
| KV Transfer | NIXL |
8.2 Prefill Node
export VLLM_USE_V2_MODEL_RUNNER=1

vllm serve /mnt/model/glm/GLM-5.2-NVFP4 \
    --trust-remote-code \
    --kv-transfer-config '{"kv_connector":"NixlConnector","kv_role":"kv_producer"}' \
    --chat-template-content-format=string \
    -ep \
    -tp 1 \
    -dp 4 \
    --tool-call-parser glm47 \
    --enable-auto-tool-choice \
    --reasoning-parser glm45 \
    --gpu-memory-utilization 0.92 \
    --enable-prompt-tokens-details \
    --speculative-config='{"method":"mtp","num_speculative_tokens":1}' \
    --shutdown-timeout 300 \
    --fingerprint-mode=none
8.3 Decode Node
export VLLM_USE_V2_MODEL_RUNNER=1

vllm serve /mnt/model/glm/GLM-5.2-NVFP4 \
    --trust-remote-code \
    --chat-template-content-format=string \
    --kv-transfer-config '{"kv_connector":"NixlConnector","kv_role":"kv_consumer"}' \
    --compilation-config '{"cudagraph_mode":"FULL_DECODE_ONLY"}' \
    --max-num-batched-tokens 1024 \
    -ep \
    -tp 1 \
    -dp 8 \
    --tool-call-parser glm47 \
    --enable-auto-tool-choice \
    --reasoning-parser glm45 \
    --gpu-memory-utilization 0.90 \
    --enable-prompt-tokens-details \
    --all2all-backend=flashinfer_nvlink_two_sided \
    --speculative-config='{"method":"mtp","num_speculative_tokens":3}' \
    --shutdown-timeout 300 \
    --fingerprint-mode=none
8.4 Benchmark Methodology
All performance data was collected with the random dataset in vllm bench serve. There were no prefix-cache hits, so the TTFT figures represent worst-case, compute-only latency. Requests were injected at a fixed --request-rate, computed as target TPS divided by (input_len + output_len) and multiplied by a tuning factor.
vllm bench serve \
  --backend openai-chat \
  --model /mnt/model/glm/GLM-5.2-NVFP4 \
  --endpoint /v1/chat/completions \
  --dataset-name random \
  --random-input-len 16384 \
  --random-output-len 1000 \
  --request-rate <target TPS / (input + output) × tuning factor> \
  --percentile-metrics ttft,tpot,itl,e2el \
  --metric-percentiles 50,90 \
  --save-result
9. What Comes Next
For GLM-5.2 and the larger MoE models that will follow, we see two major directions for Decode optimization. The following are forward-looking assessments rather than conclusions measured in this post.
First, reduce the cost of each target forward pass. Beyond core kernels such as GEMM, Attention, and the Indexer, this includes exploring PDL, persistent kernels, localized megakernels, and coordinated computation and communication across MoE Dispatch, Expert GEMM, and Combine. As deployments scale across nodes, WideEP, hierarchical all2all, and overlap between inter-node communication and computation become increasingly important. The objective is to shorten the end-to-end critical path of a complete Decode step.
Second, advance model–runtime co-optimization for speculative decoding. On the model side, stronger drafters such as DSpark can be trained on broader datasets to improve the accuracy of consecutive proposal tokens. On the runtime side, dynamic speculative decoding, per-request proposal lengths, and compact verification can keep verification cost in check across different workloads. The draft model determines how far the system can predict; the serving runtime determines how far prediction is actually economical.
In addition, the PCP virtual-batch work described in Section 6 has already landed in main. We will evaluate whether it removes the KV-cache-capacity versus per-GPU-efficiency trade-off discussed in Section 4.
About Us
This work was completed by the DaoCloud team. We deliver full-stack platforms for enterprise LLM training and inference, including heterogeneous accelerator scheduling, inference-service orchestration, and observability. We shared our observations and validation results with the vLLM community throughout the tuning process, and the resulting improvements were merged upstream. The configuration in this post can be used directly with v0.26.0.
Special thanks to Nicolò Lucchesi (@NickLucche) from Mistral AI, who suggested writing this post in the first place, reviewed it in detail, and kept it moving from a rough set of notes to what you have just read.
We also thank the vLLM community for its efficient collaboration under Issue #46654. In most cases, fixes moved from initial report to a released version within one week.