要点速览
- 自回归解码一步一个 token,每步都要跑完整目标模型;对 Kimi-K2.5、MiniMax-M2.5 这类大 MoE 模型,这限制了吞吐并推高实时延迟。
- EAGLE3 用 feature-level drafting:训练与目标对齐的 draft 模块,结合目标低/中/高层 hidden states,接受率高。
- AMD Quark 提供 day-0 MXFP4/FP8 checkpoint,在 ROCm/vLLM 开箱即用,MI350 系列原生支持 FP4 矩阵加速。
- 训练管线以 vLLM 为中心:on-policy 数据合成、hidden states 提取、FSDP2 冷启动、serve-eval 选优、导出部署。
- MiniMax-M3 draft 平均 AL 2.80;Kimi-K2.5 最高 2.00x、MiniMax-M2.5 最高 1.79x(MI355X)。
解决什么问题
LLM 推理日益受制于自回归解码:即使 prefill 已高度优化,decode 阶段仍要一步一步生成 token,每步通常都要运行完整目标模型。对 Kimi-K2.5、MiniMax-M2.5 这样的大型 mixture-of-experts 与注意力密集模型,这种串行模式限制了服务吞吐,并增加了实时应用的延迟。本文解决如何在 AMD Instinct GPU 上端到端地完成 EAGLE3 speculative decoding 的训练、量化与推理加速全流程。
核心思路
文章给出三段式端到端方案:(1)EAGLE3 draft 训练——由 vLLM 服务 AMD Quark MXFP4 目标模型合成 on-policy 数据(用精确 chat template 的 /v1/chat/completions 与绕过模板的 /v1/completions),通过 hidden-state extraction hook 流式提取目标的低/中/高层特征(online/offline/streaming 三种模式,streaming 让 420B MoE 目标单节点训练可行),在 FSDP2 下以 TTT 损失与位置衰减加权冷启动单层 draft 头,并周期性 serve-eval 用实测接受长度选出最优 checkpoint 后导出部署;(2)AMD Quark day-0 MXFP4/FP8 量化,目标与 draft 均可覆盖;(3)ROCm/vLLM 上的 EAGLE3 推理加速,并在 MI355X 上用 InferenceX 基准测试。
关键要点
- Speculative decoding 机制与无损性 — 流程为:draft 模型提议若干候选 token;目标模型一次前向验证;greedy 解码下匹配的 token 被接受,采样解码下按目标与 draft 概率接受或纠正;首个拒绝处验证器发出修正 token 并从中重启起草,若全部接受则验证器额外产出一个 bonus token。每个 draft token 都对照被服务的目标模型验证,因此目标的输出分布保持不变,是一种无损加速。以 γ=5 为例:接受 α=3 的前缀、拒绝首个不匹配、丢弃后续 draft 并发修正 token,一轮返回 α+1=4 个 token。
- 两个关键指标:条件接受率与接受长度 — conditional acceptance rate 衡量在前序位置均被接受时接受当前位置的概率;acceptance length(AL)衡量每个验证周期平均产出的 token 数,AL=1 表示每个验证步骤只产出一个 token(还未计入起草开销)。更高的 AL 可以减少目标模型验证步数,但实际吞吐还取决于起草与验证的开销,二者需一起权衡。
- 为什么选 EAGLE3 — EAGLE 系列持续演进:EAGLE 开创 feature-level speculative decoding,EAGLE2 改进草稿质量与接受率,EAGLE3 进一步利用目标模型多层特征提升准确率与加速。它不依赖无关的小语言模型,而是训练与目标模型紧密对齐的 draft 模块,使用 training-time testing 技术并组合目标的低/中/高层语义特征,使 draft 提出验证器更可能接受的候选。常见的其他方案包括小 draft 模型、MTP、Medusa 式多头预测,以及 DFlash、DSpark 等 feature-level 方法;EAGLE3 以强草稿质量、高接受率与稳定加速胜出。
- MXFP4 与 day-0 量化 — MXFP4 是 OCP Microscaling 4-bit 浮点格式:4-bit 元素分组成小块并共享 scale factor,显存占用接近 INT4 而数值行为远好于 INT4。MI350 系列(MI350X/MI355X)原生提供 FP4 矩阵加速,MXFP4 权重可直接映射到硬件,缓解大 MoE 解码的带宽与容量压力。AMD Quark 团队为主流模型提供 day-0 MXFP4/FP8 checkpoint(如 amd/Kimi-K2.5-MXFP4、amd/MiniMax-M3-MXFP4),即模型发布当天就有能在 ROCm/vLLM 开箱运行的硬件就绪量化版本;vLLM 经 MXFP4 执行路径与 AITER MoE kernel 直接消费这些 checkpoint。
- vLLM 中心的五阶段训练管线 — Stage 1 on-policy 数据合成:把 MXFP4 目标跑成 vLLM-ROCm 服务生成数据,既用 /v1/chat/completions(与后续服务完全一致的 chat template)也用绕过模板的 /v1/completions,以覆盖非对话与分布外场景,保证训练/服务一致。Stage 2 hidden states 提取:EAGLE3 以目标的低/中/高层 hidden states 加 fc_norm 为条件,vLLM hook 直接从运行中的引擎暴露这些辅助层,支持 online(同机共置)、offline(落盘)、streaming(从 vLLM serve 直播给 trainer,不落盘)三种模式。Stage 3 冷启动:在 FSDP2 下用 TTT 损失与位置衰减加权从头训练单层 draft 头,验证器就是部署时的 MXFP4 目标。Stage 4 serve-eval:训练损失会高估真实接受率,因此周期性导出 checkpoint 在 vLLM 下实测接受长度,按该指标选优。Stage 5 导出 HF 格式并以 vLLM-ROCm EAGLE 投机解码部署。
- 流式 hidden-state 提取让大模型训练可行 — hidden-state extraction hook 直接从运行中的目标引擎暴露辅助层,三种模式可互换:online 目标与 trainer 同机共置,offline 把 hidden states 落盘,streaming 从活跃的 vLLM serve 直流给 trainer 而无磁盘转储。streaming 模式正是在单节点上训练 420B MXFP4 MoE 目标得以可行的关键。这一设计把『推理引擎』变成了『训练数据与监督信号的生产者』。
- MiniMax-M3 draft 质量:SPEED-Bench 11 域结果 — 在多域推测解码基准 SPEED-Bench 上,训练出的 MiniMax-M3 EAGLE3 draft 以接受长度(AL)评估:11 个域平均 AL 2.80,即每个目标验证步约产出 2.8 个 token。结构化技术内容最强——coding 3.32、math 3.14、RAG 3.12、multilingual 3.04;最难的开放式写作与角色扮演仍保持 2.01-2.33。接受长度随 prompt 从 1K 增长到 32K 基本平坦(2.69 到 2.65),说明跨上下文长度稳定;三个推测 token 下第一/二/三位累计接受率约 76%/56%/43%。该 draft 已发布为 amd/MiniMax-M3-EAGLE3.1,配 amd/MiniMax-M3-MXFP4 目标用 vllm serve 启动(TP=8、TRITON_ATTN、eagle3、num_speculative_tokens=3)。
- 加速结果、测量条件与来源说明 — 1K/1K(ISL=OSL=1024)随机 prompt、MI355X、TP=4 下,EAGLE3 相对同 build 无推测基线提升吞吐:Kimi-K2.5 为 1.69x–2.00x(BF16 draft 1.69x-1.90x、FP8 draft 1.76x-2.00x),MiniMax-M2.5 为 1.38x–1.79x,低并发时收益最大。注意:Kimi 的 BF16 与 FP8 扫描使用不同 vLLM build 与 MML(2248 vs 2304),并非受控精度对比;随机 prompt 扫描是吞吐微基准而非应用级负载基准;FP8 draft(amd/kimi-k2.5-eagle3-fp8,与目标共享 BF16 LM head)经 RowWiseTorchFP8ScaledMMLinearKernel(hipBLASLt row-wise scaled FP8 GEMM)而非 AITER preshuffled FP8 路径分发。Kimi-K2.5 与 MiniMax-M2.5 的 draft 是 HuggingFace 社区开源版本,非本文训练;本文自训的是 MiniMax-M3 draft,EAGLE3 draft 训练支持计划在下一个 AMD Quark 版本发布。
关键数据
| 指标 | 数值 | 条件 |
|---|---|---|
| Kimi-K2.5 EAGLE3 吞吐提升 | 1.69x–2.00x | amd/Kimi-K2.5-MXFP4 目标,1K/1K 随机 prompt,MI355X,TP=4,每格 10 个随机种子取均值 |
| Kimi-K2.5 分 draft 精度(BF16/FP8)的加速区间 | BF16 1.69x-1.90x;FP8 1.76x-2.00x | amd/Kimi-K2.5-MXFP4 目标,1K/1K,MI355X,TP=4;BF16 与 FP8 使用不同 vLLM build 与 MML,非受控精度对比 |
| Kimi-K2.5 基准 MML 设置差异 | BF16 扫描 MML=2248;FP8 扫描 MML=2304 | Kimi 图表中 BF16(vllm-openai-rocm:v0.19.0)与 FP8(nightly)两条路径的 max-model-len 不同 |
| MiniMax-M2.5 EAGLE3 吞吐提升 | 1.38x–1.79x | MiniMaxAI/MiniMax-M2.5 目标 + thoughtworks BF16 draft,1K/1K 随机 prompt,MI355X,TP=4 + 专家并行,每并发 5 个种子 |
| MiniMax-M3 draft SPEED-Bench 平均接受长度 | 2.80 | amd/MiniMax-M3-EAGLE3.1 draft 对 amd/MiniMax-M3-MXFP4 目标,SPEED-Bench 11 个域 |
| 按域接受长度(最强/最弱) | coding 3.32、math 3.14、RAG 3.12、multilingual 3.04;开放式写作与角色扮演 2.01-2.33 | MiniMax-M3 EAGLE3 draft,SPEED-Bench 各域,角色扮演最低 2.01、写作 2.33 |
| 接受长度随上下文长度变化 | 1K 时 2.69 → 32K 时 2.65 | MiniMax-M3 EAGLE3 draft,SPEED-Bench,prompt 长度从 1K 增至 32K token |
| 各 draft 位置累计接受率 | 第 1/2/3 位约 76% / 56% / 43% | MiniMax-M3 EAGLE3 draft,三个推测 token(num_speculative_tokens=3) |
| 可训练的目标模型规模 | 420B 参数 MXFP4 MoE,单节点 | 训练管线采用 streaming hidden-state 模式时,MiniMax-M3 类大 MoE 目标的 draft 训练可在单节点完成 |
| 基准负载设置 | ISL=1024,OSL=1024(1K/1K) | 加速结果章节的统一工作负载;速度提升定义为 EAGLE3 吞吐除以对应无推测基线吞吐 |
| MiniMax-M2.5 推测配置 | num_speculative_tokens=3,draft_tensor_parallel_size=1 | MiniMax-M2.5 BF16 EAGLE3 draft 路径(thoughtworks/MiniMax-M2.5-Eagle3) |
“Across the 1K/1K sweeps, EAGLE3 increases output throughput by 1.69x–2.00x for Kimi-K2.5 and 1.38x–1.79x for MiniMax-M2.5 relative to the matching no-speculation baselines (Figures 4 and 5).”
“Both the BF16 and AMD Quark FP8 draft paths beat the no-speculative baseline (1.69x-1.90x and 1.76x-2.00x respectively); the gain is largest at low concurrency.”
“The Kimi chart shows the BF16 and FP8 draft paths together; the BF16 vLLM v0.19.0 sweep uses MML=2248, while the FP8 sweep uses MML=2304.”
前置知识
自回归解码与 prefill/decode 两阶段:decode 一步一个 token,每步运行完整目标模型并触及权重、attention 状态与 KV cache · speculative decoding 基本机制:draft 提议、目标单次验证、接受/修正/bonus token 逻辑 · EAGLE 家族 feature-level drafting 思路:用目标模型 hidden states 训练紧密对齐的 draft 模块 · 量化基础:FP8 缩放与 OCP MXFP4 块级缩放格式 · vLLM serving 基础:tensor parallelism(TP)、--speculative-config、max-model-len(MML)、docker 镜像 · 分布式训练与 AMD 生态基础:FSDP2、ROCm、MI355X、AITER/hipBLASLt
术语表
Speculative Decoding: 推测解码:小型/轻量 draft 模型提议多个未来 token,目标模型单次前向验证,接受匹配 token 以减少昂贵的目标解码迭代,同时精确保留目标输出分布(无损)。EAGLE3: EAGLE 家族第三代 feature-level 推测解码方法,训练与目标紧密对齐的 draft 模块,组合目标模型低/中/高层 hidden states 与 training-time testing,草稿质量与接受率高。Draft Model / Target Model: draft model 是提议候选 token 的轻量模型;target model 是被服务的原始模型,充当验证器,每个 draft token 都对照它验证。Acceptance Length (AL): 接受长度:每个目标验证周期平均产出的 token 数;AL=1 意味着没有加速(尚未计入起草开销),越高越好。Conditional Acceptance Rate: 条件接受率:在前序位置均被接受的条件下,接受当前 draft 位置的概率。Bonus Token: 奖励 token:当全部 draft token 被接受时,验证器额外生成的一个 token,进一步提升每轮产出。MXFP4: OCP Microscaling 4-bit 浮点格式:4-bit 元素分成小块并共享 scale factor,显存占用接近 INT4 而数值行为好得多;MI350 系列原生 FP4 矩阵加速可直接承载。AMD Quark: AMD 的模型量化工具包,提供主流 LLM 的 day-0 MXFP4/FP8 量化 checkpoint 与量化工作流。Day-0 Quantization: day-0 量化:主流模型发布当天即提供能在 ROCm/vLLM 开箱即用的硬件就绪 MXFP4(和 FP8)构建,无需等待第三方量化。On-policy Data: on-policy 数据:由被服务的目标模型自身生成、与其输出分布一致的数据;EAGLE3 draft 从这类数据学习效果最好。Hidden-state Extraction: vLLM 的 hidden states 提取 hook,直接从运行中的目标引擎暴露低/中/高层 hidden states 与 fc_norm 供 draft 训练;有 online、offline、streaming 三种模式。FSDP2: Fully Sharded Data Parallel 2,用于从头冷启动训练单层 EAGLE3 draft 头的分布式训练策略。Serve-eval: 训练过程中周期性导出 checkpoint、在 vLLM 推测解码下实际服务并测量真实接受长度,以该实测指标选择最优 checkpoint;弥补训练损失高估接受率的问题。MML (max-model-len): vLLM 单请求可处理的最大上下文长度,即 prompt 与生成输出 token 总数的上限。AITER: AMD ROCm 上的算子库,提供 MoE kernel;vLLM 通过 MXFP4 执行路径与 AITER MoE kernel 消费 Quark 量化 checkpoint。MoE: mixture-of-experts 混合专家架构;大型 MoE 的 decode 阶段受访存带宽与容量支配,量化与推测解码收益尤其明显。SPEED-Bench: 多域推测解码基准,覆盖 coding、math、RAG、multilingual 等 11 个域,以接受长度(AL)为主要指标。ISL / OSL: 输入/输出序列长度;本文加速基准统一采用 ISL=1024、OSL=1024 的 1K/1K 工作负载。InferenceX: 本文加速结果所使用的推理基准测试工具。
EAGLE3 Speculative Decoding on AMD Instinct GPUs: Training and Serving with vLLM and AMD Quark
Large language model (LLM) inference is increasingly constrained by autoregressive decoding. Even when prefill is highly optimized, the decode phase still generates tokens one step at a time, and each step typically requires running the full target model. For large mixture-of-experts and attention-heavy models such as Kimi-K2.5 and MiniMax-M2.5, this sequential pattern limits serving throughput and increases latency for real-time applications.
Speculative decoding is one of the most practical ways to address this bottleneck. It is a lossless LLM inference acceleration technique that preserves the exact output distribution of the target model while improving decoding efficiency. It uses a smaller or lighter-weight draft model to propose multiple future tokens, then asks the original target model to verify those tokens in a single forward pass. When the draft model predicts tokens that the target model would also produce, those tokens can be accepted together, reducing the number of expensive target-model decode iterations.
Common speculative decoding approaches include small draft models, multi-token prediction (MTP), Medusa-style multi-head prediction, and feature-level drafting methods such as EAGLE3, DFlash, and the recently introduced DSpark. Among existing speculative decoding methods, EAGLE3 is particularly attractive due to its strong draft quality, high acceptance rate, and consistently competitive inference speedups.
In this blog, we walk through three parts of the EAGLE3 workflow on AMD Instinct GPUs, with contributions from the AMD Quark team: (1) training EAGLE3 draft models, where vLLM serves the target to synthesize on-policy data, extract training-time hidden states, and run in-the-loop acceptance evaluation; (2) AMD Quark quantization, which provides day-0 MXFP4 and FP8 support for both the target and the draft; and (3) inference acceleration on ROCm/vLLM for Kimi-K2.5 and MiniMax-M2.5 on AMD Instinct™ MI355X GPUs, benchmarked with InferenceX. The same pipeline was used to train our MiniMax-M3 EAGLE3 draft, which we use as the running example in the training section.
Why Speculative Decoding and EAGLE3 Matter
Standard autoregressive decoding emits one token per target-model step. If a model needs to generate 1,000 output tokens, the serving engine typically performs roughly 1,000 target-model decode iterations after prefill. This is expensive because each decode iteration touches the model weights, attention state, scheduler, and KV cache machinery.
Speculative decoding changes this process:
-
A draft model proposes several candidate next tokens.
-
The target model verifies those candidates in one pass.
-
Under greedy decoding, matching draft tokens are accepted; under sampling, draft tokens are accepted or corrected according to the target and draft probabilities.
-
At the first rejection, the verifier emits a correction token and drafting resumes from it; if all draft tokens are accepted, the verifier emits one bonus token.
Conditional acceptance rate measures the probability of accepting a draft position given that the preceding positions were accepted. Acceptance length measures the number of tokens emitted per verification cycle. Higher acceptance length can reduce the number of target-model verification steps, but realized throughput also depends on drafting and verification overhead. (Figure 1)
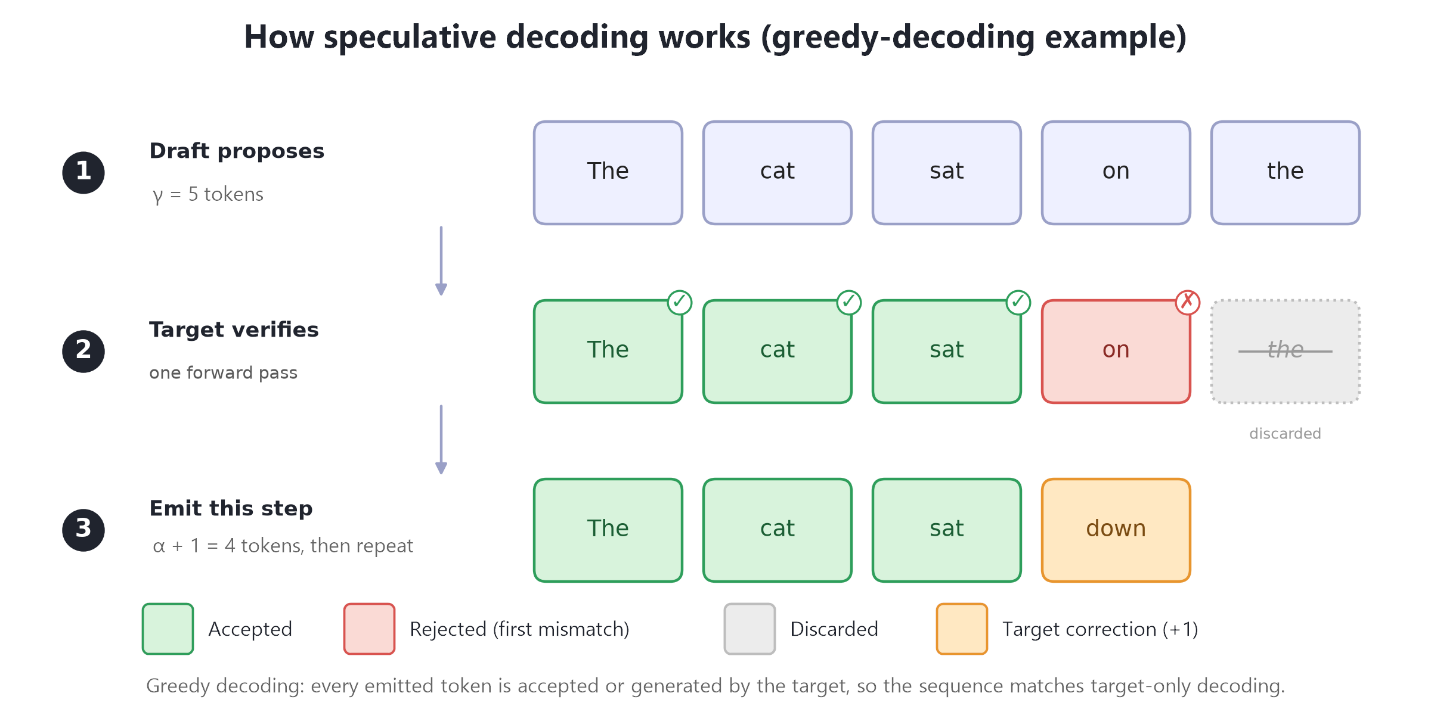
Figure 1: Greedy speculative decoding with γ=5: the target accepts an α=3-token prefix, rejects the first mismatch, discards later draft tokens, and emits a correction token, returning α+1=4 tokens. If all γ draft tokens are accepted, the extra token is a target-generated bonus token.
EAGLE has been continuously improving over the past few years. It started with feature-level speculative decoding in EAGLE, improved draft quality and acceptance rates in EAGLE2, and further increased accuracy and speedups in EAGLE3 by leveraging multi-layer features from the target model. Instead of relying on an unrelated small language model, it trains a draft module that is closely aligned with the target model. It uses training-time testing techniques and combines low-, mid-, and high-level semantic features from the target model, helping the draft model propose candidates that the verifier is more likely to accept.
For production inference, the important point is simple: EAGLE3 can improve generation throughput while preserving the target model output behavior through verification.
AMD Quark MXFP4: Day-0 Quantization for Mainstream LLMs
MXFP4 is the Open Compute Project (OCP) Microscaling 4-bit floating-point format: 4-bit elements are grouped into small blocks that share a scale factor, giving a memory footprint close to INT4 while keeping far better numerical behavior. AMD Instinct MI350-series GPUs (MI350X/MI355X) provide native FP4 matrix acceleration, so MXFP4 weights map directly onto the hardware and relieve the memory-bandwidth and capacity pressure that dominates large mixture-of-experts decoding.
AMD Quark is AMD's model-quantization toolkit, and the AMD Quark team provides Day-0 MXFP4 quantized checkpoints for mainstream LLMs, published on Hugging Face (for example, amd/Kimi-K2.5-MXFP4 and amd/MiniMax-M3-MXFP4). Day-0 means that when a major model is released, the Quark team ships a hardware-ready MXFP4 (and FP8) build that runs on ROCm/vLLM out of the box, rather than waiting for third-party quantization to catch up. These published checkpoints are ready to use directly as the target for both EAGLE3 draft training and speculative-decoding inference.
These checkpoints are consumed directly by vLLM on ROCm through the supported MXFP4 execution path and AITER MoE kernels, so users get the memory savings of MXFP4 together with production-grade throughput. Speculative decoding is lossless: every draft token is verified against the served target, so it leaves the target's output distribution unchanged.
Training EAGLE3 Draft Models with vLLM
A high-acceptance draft is what makes speculative decoding fast, and training one is as much a systems problem as a modeling problem. In our pipeline, vLLM is not just the inference engine — it sits at the center of training too. The AMD Quark team developed and validated the MiniMax-M3 EAGLE3 training workflow on AMD Instinct GPUs, which we use as the running example. (The Kimi-K2.5 and MiniMax-M2.5 EAGLE3 drafts in the inference results below are open-source community drafts from Hugging Face, not trained by us.) (Figure 2)
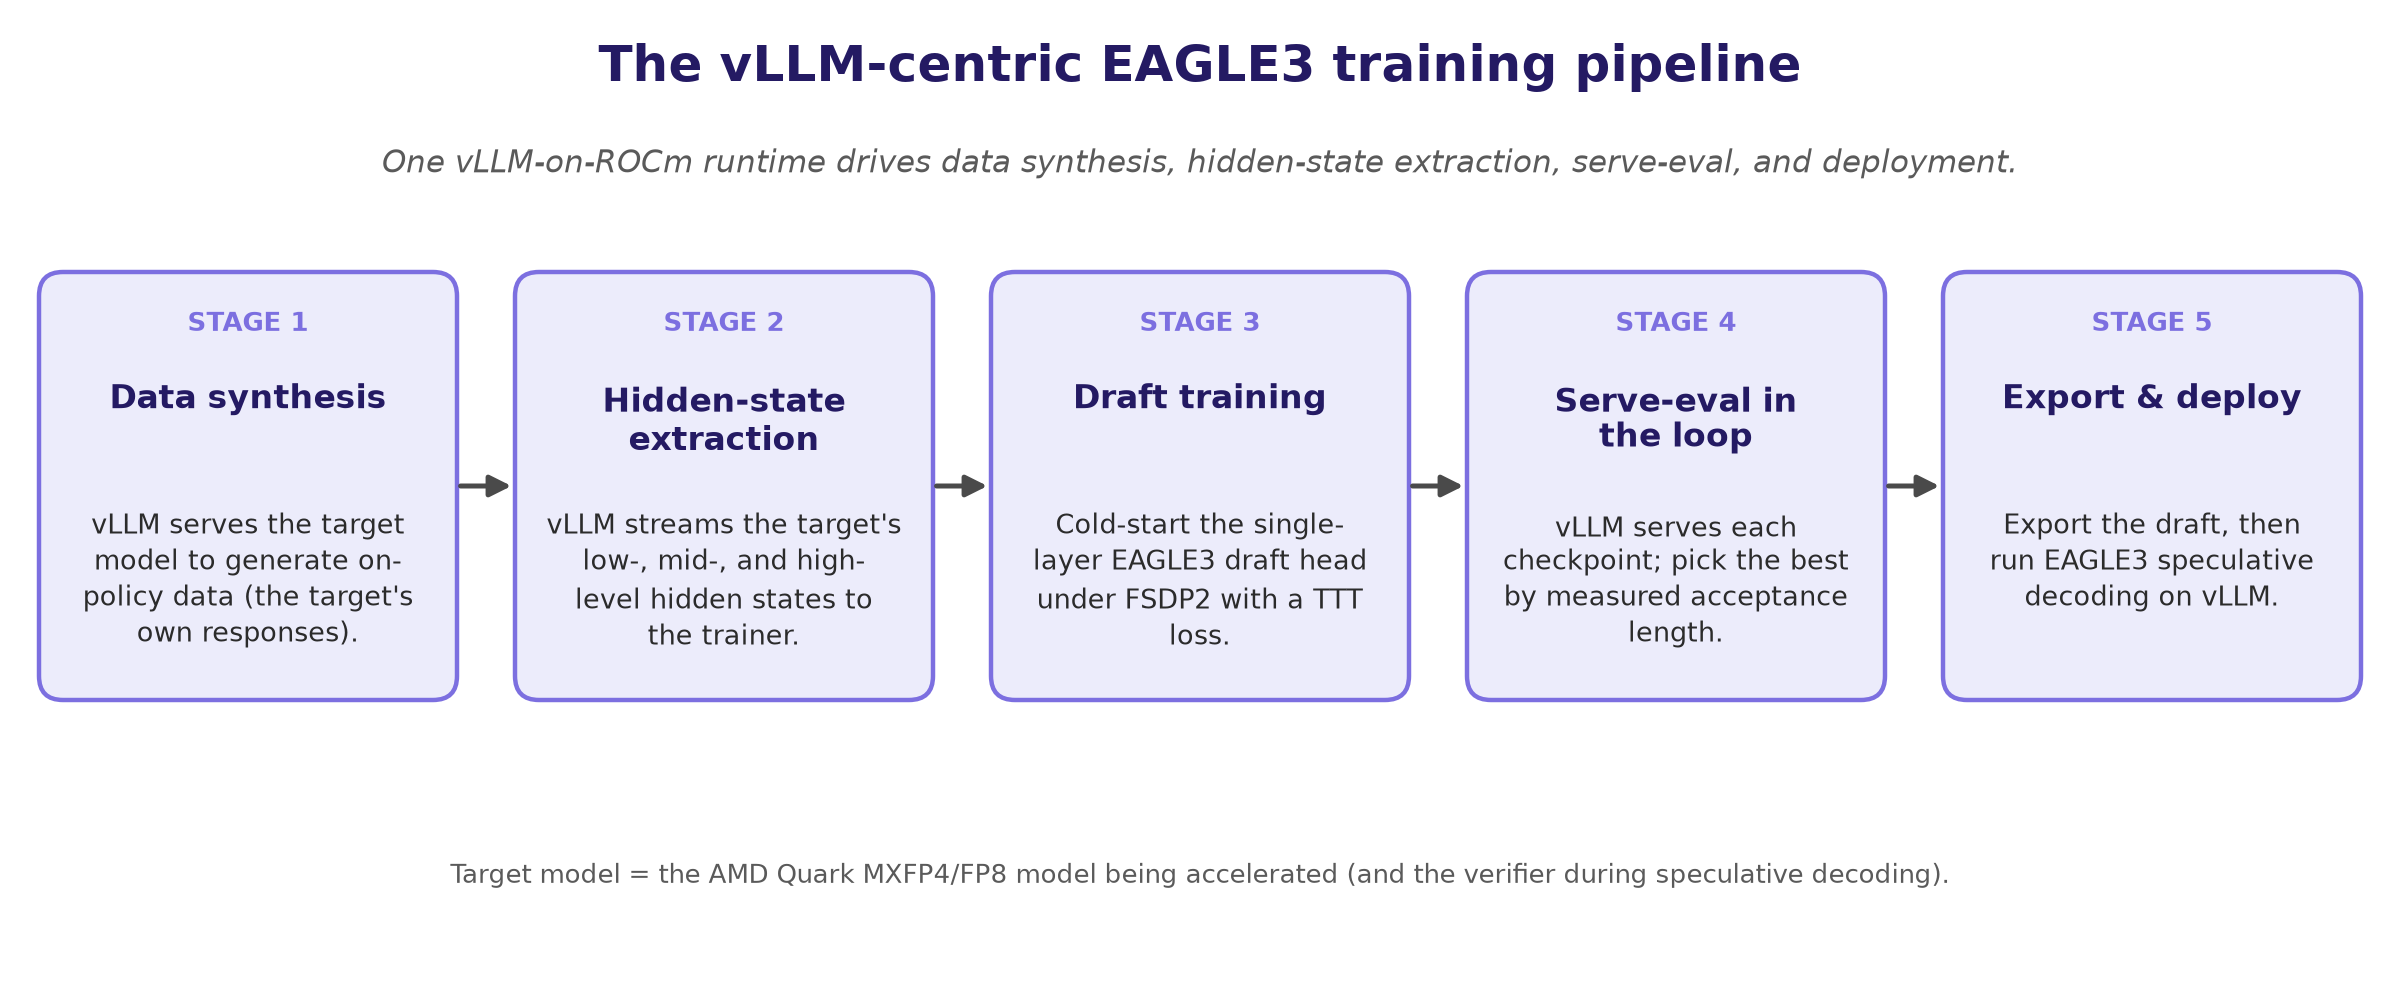
Figure 2: The vLLM-centric EAGLE3 training pipeline. One vLLM-on-ROCm runtime drives the whole loop: it serves the AMD Quark MXFP4/FP8 target model to synthesize on-policy data (Stage 1), streams the target’s low-, mid-, and high-level hidden states to the trainer (Stage 2), cold-starts the single-layer EAGLE3 draft head under FSDP2 (Stage 3), runs in-loop serve-eval to select the best checkpoint by measured acceptance length (Stage 4), then exports the draft and deploys it for EAGLE3 speculative decoding (Stage 5).
-
On-policy data synthesis, served by vLLM. EAGLE3 drafts learn best from data in the target’s own distribution. We stand up the AMD Quark MXFP4 target as a vLLM-ROCm server and generate on-policy responses through it — both chat (
/v1/chat/completions, using the exact serving chat template) and raw/v1/completions(template-bypassed) for non-chat and out-of-distribution robustness. Generating data with the same engine and template we later serve with keeps training and serving consistent. -
Hidden-state extraction, provided by vLLM. EAGLE3 conditions the draft on the target’s internal features — low-, mid-, and high-level hidden states plus an
fc_norm— rather than on an unrelated small model. vLLM’s hidden-state extraction hook exposes these auxiliary layers directly from the running target engine. We support three interchangeable modes: online (target co-located with the trainer), offline (hidden states dumped to disk), and streaming (hidden states streamed from a live vLLM serve to the trainer with no disk dump). Streaming is what makes training a 420B MXFP4 MoE target practical on a single node. -
Cold-start FSDP2 training. The single-layer EAGLE3 draft head is trained from scratch with a training-time-test (TTT) loss and position-decay weighting under FSDP2. Because the verifier is the AMD Quark MXFP4 target, the draft learns against exactly the activation space it will face at deploy time.
-
Serve-eval in the loop, again on vLLM. The in-training loss overstates real acceptance, so we periodically export the current checkpoint, serve it under vLLM speculative decoding, measure the true acceptance length, and select the best checkpoint by that served metric. The engine that will run in production is the same engine that picks the draft.
-
Export and deployment on vLLM. The selected draft is exported to Hugging Face format, folded into a vLLM-ready draft directory, and deployed with vLLM-ROCm EAGLE speculative decoding — the exact path measured in the next section.
Draft quality on SPEED-Bench: 11 domains and long context
We evaluate the trained MiniMax-M3 EAGLE3 draft on SPEED-Bench, a multi-domain speculative-decoding benchmark, using acceptance length (AL) — the mean number of tokens emitted per target verification step (higher is better; AL = 1 means one emitted token per target verification step, before accounting for drafting overhead).
Acceptance length by domain (SPEED-Bench qualitative):
| Domain | Acceptance length (AL) |
|---|---|
| Coding | 3.32 |
| Math | 3.14 |
| RAG | 3.12 |
| Multilingual | 3.04 |
| Reasoning | 2.89 |
| STEM | 2.86 |
| Summarization | 2.86 |
| Humanities | 2.71 |
| QA | 2.55 |
| Writing | 2.33 |
| Roleplay | 2.01 |
| Average | 2.80 |
Across 11 domains the draft averages AL 2.80 — roughly 2.8 emitted tokens per target verification step. It is strongest on structured, technical content — coding (3.32), math (3.14), RAG (3.12), and multilingual (3.04) — and still holds AL 2.01-2.33 on open-ended writing and roleplay, the hardest cases for any draft to predict. Just as important, acceptance length is essentially flat as the prompt grows from 1K to 32K tokens (2.69 to 2.65), indicating stable draft acceptance across context lengths. At three speculative tokens, the first, second, and third draft positions are accepted about 76%, 56%, and 43% of the time (cumulative). These results are the payoff of our vLLM-centric recipe: on-policy data generated through the target, hidden-state supervision from the target’s own features, cold-start training against the exact AMD Quark MXFP4 verifier, and checkpoint selection by real served acceptance. (Figure 3)
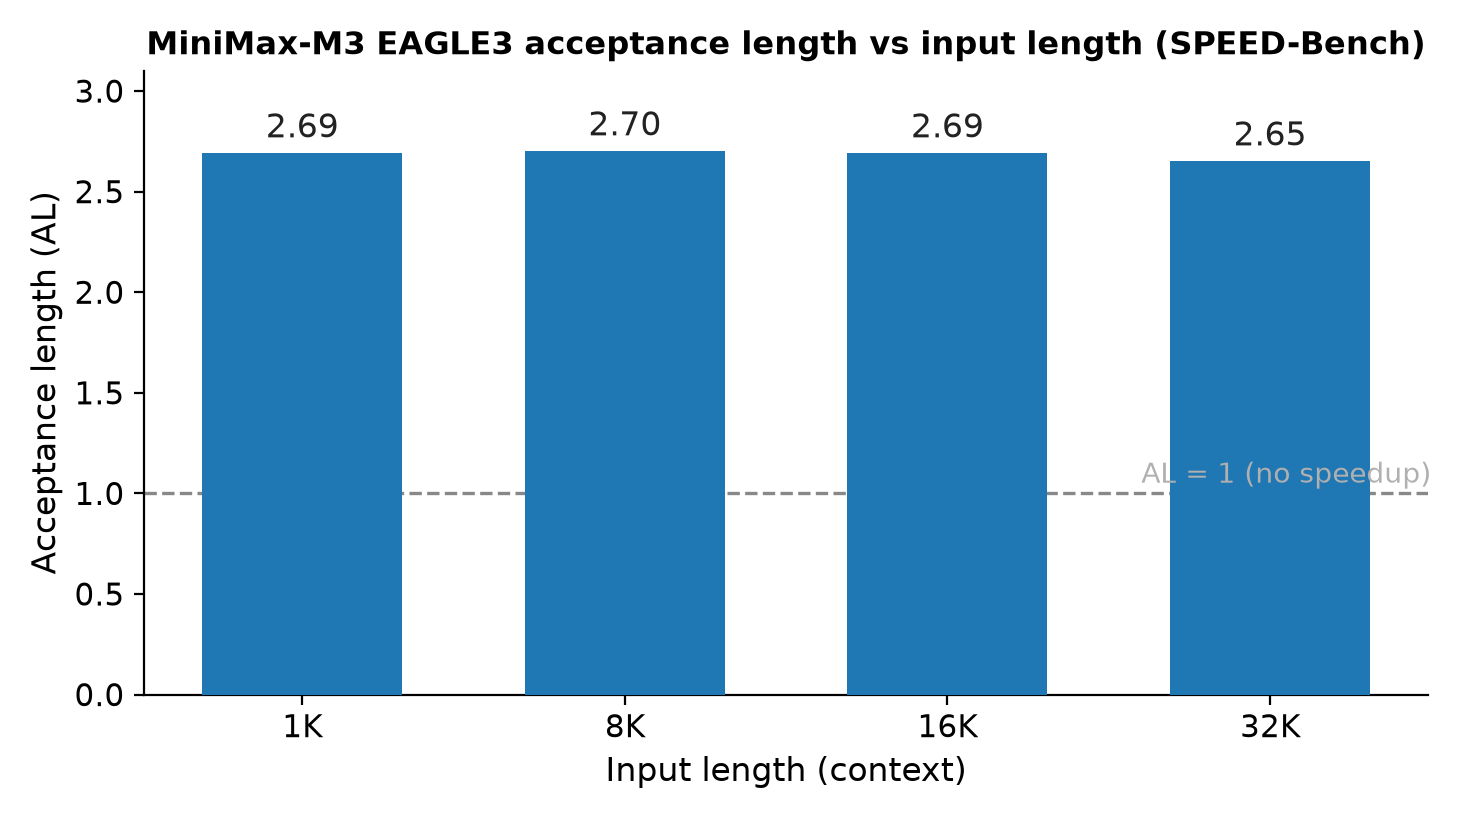
Figure 3: MiniMax-M3 EAGLE3 acceptance length is essentially flat from 1K to 32K context on SPEED-Bench (2.69 at 1K to 2.65 at 32K). The dashed AL=1 line marks one emitted token per verification cycle.
The trained draft is published as amd/MiniMax-M3-EAGLE3.1 and can be served with vLLM speculative decoding against the amd/MiniMax-M3-MXFP4 target:
export VLLM_ROCM_USE_AITER=1
vllm serve amd/MiniMax-M3-MXFP4 --trust-remote-code --tensor-parallel-size 8 \
--block-size 128 --attention-backend TRITON_ATTN --moe-backend emulation \
--speculative-config '{"method":"eagle3","model":"amd/MiniMax-M3-EAGLE3.1","num_speculative_tokens":3,"attention_backend":"TRITON_ATTN"}'
End-to-End Solution
The AMD Quark team handles the entire stack end to end:
-
Target model: day-0 MXFP4/FP8 quantization and ROCm/vLLM deployment.
-
Draft model: EAGLE3 training performed in this work, FP8/MXFP4 quantization with AMD Quark, and ROCm/vLLM deployment.
-
End-to-end integration: on-policy data synthesis, hidden-state extraction, serve-eval, export, and speculative serving are all wired through vLLM and validated together.
Together, these components provide a quantized target, a matching high-acceptance draft, and a validated vLLM speculative-decoding deployment for AMD Instinct GPUs.
Acceleration Results
The following draft results section lists only the 1K/1K workload, with ISL=1024 and OSL=1024. Speedup is computed as EAGLE3 throughput divided by the corresponding no-speculative-decoding baseline throughput. Each draft result is compared only with the no-speculation baseline from the same vLLM build and MML setting. Kimi-K2.5 results use AMD Instinct MI355X, TP=4, random prompts, num_prompts=10 x concurrency, num_warmups=2 x concurrency, and 10 seeds per cell. Each plotted value is the arithmetic mean of 10 runs with different random seeds. These random-prompt sweeps are throughput microbenchmarks, not application-level workload benchmarks. The Kimi chart shows the BF16 and FP8 draft paths together; the BF16 vLLM v0.19.0 sweep uses MML=2248, while the FP8 sweep uses MML=2304. Because the builds and MML settings differ, the two paths are not a controlled precision comparison. Here, MML (max-model-len) is the maximum context length - the total number of tokens (prompt + generated output) that a vLLM model can process in a single request.
Kimi K2.5 EAGLE3: BF16 and AMD Quark FP8 Drafts
Docker images: BF16 sweep uses vllm/vllm-openai-rocm:v0.19.0 (MML=2248); FP8 sweep uses vllm/vllm-openai-rocm:nightly-fb1ac806c55a6dc96fe92261b80c8550e9c39d2f (MML=2304).
Target model: amd/Kimi-K2.5-MXFP4. BF16 draft model: lightseekorg/kimi-k2.5-eagle3. FP8 draft model: amd/kimi-k2.5-eagle3-fp8, produced by the AMD Quark team using the released AMD Quark FP8 quantization workflow and metadata; it shares the target's BF16 LM head. In this setup, the FP8 draft path dispatches through vLLM RowWiseTorchFP8ScaledMMLinearKernel, i.e. torch._scaled_mm over hipBLASLt row-wise scaled FP8 GEMM, rather than the AITER preshuffled FP8 path.
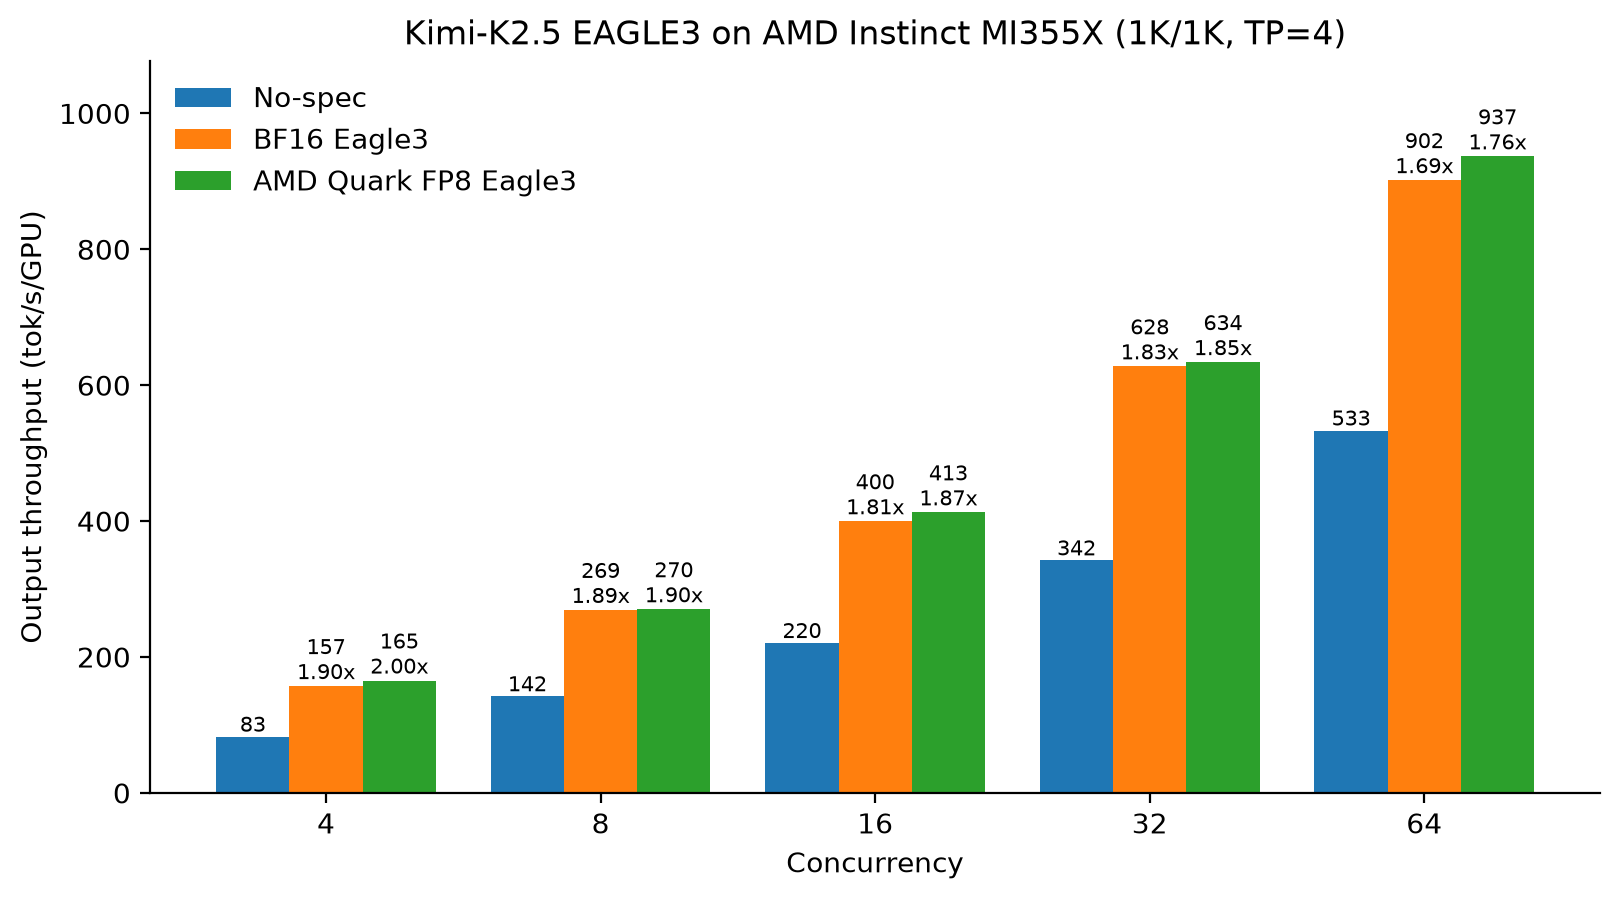
Figure 4: Kimi-K2.5 EAGLE3 output throughput (tok/s/GPU) at 1K/1K on AMD Instinct MI355X (TP=4). Both the BF16 and AMD Quark FP8 draft paths beat the no-speculative baseline (1.69x-1.90x and 1.76x-2.00x respectively); the gain is largest at low concurrency. Each speedup uses its matching no-speculation baseline; the BF16 and FP8 sweeps use different vLLM builds and MML settings.
MiniMax M2.5 BF16 EAGLE3
Docker image: vllm/vllm-openai-rocm:nightly-4eafc729285e459a5fc96efd6f7b313b155cad48
Target model: MiniMaxAI/MiniMax-M2.5. Draft model: thoughtworks/MiniMax-M2.5-Eagle3, BF16 draft path with num_speculative_tokens=3 and draft_tensor_parallel_size=1. The numbers below use 1K/1K random prompts, TP=4 with expert parallelism enabled, and five seeds per concurrency. Each plotted value is the arithmetic mean of five runs with different random seeds, and each EAGLE3 result is paired with a no-speculation baseline from the same build and configuration.
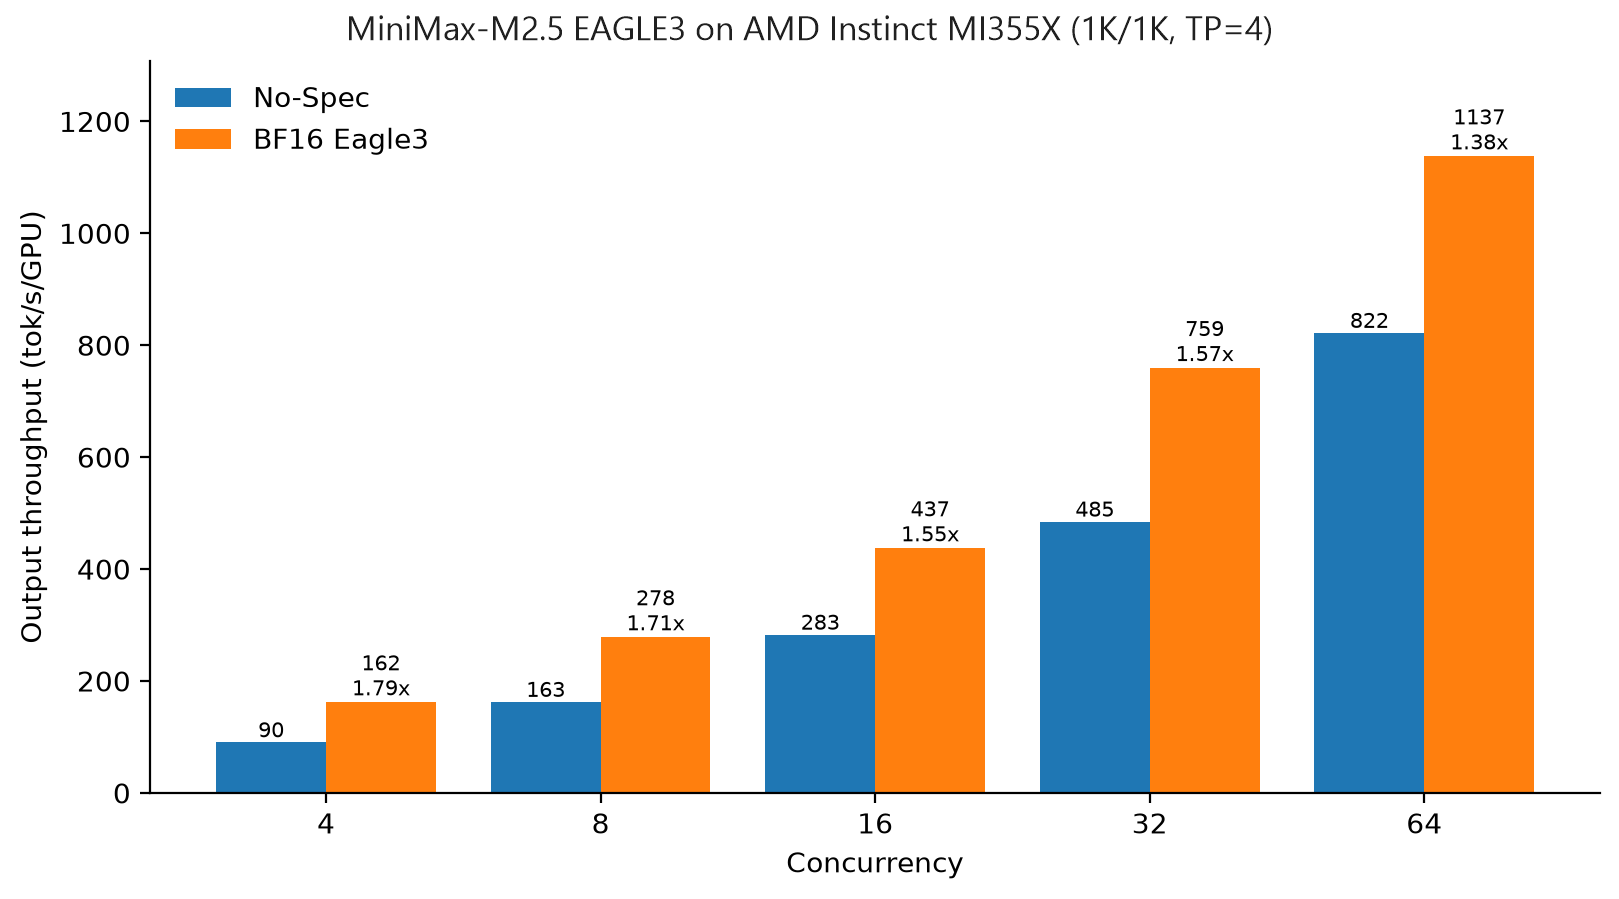
Figure 5: MiniMax-M2.5 EAGLE3 output throughput (tok/s/GPU) at 1K/1K on AMD Instinct MI355X (TP=4). Each EAGLE3 result uses the matching no-speculation baseline; the largest relative gain occurs at low concurrency.
Across the 1K/1K sweeps, EAGLE3 increases output throughput by 1.69x–2.00x for Kimi-K2.5 and 1.38x–1.79x for MiniMax-M2.5 relative to the matching no-speculation baselines (Figures 4 and 5).
Summary
Speculative decoding with EAGLE3 delivers throughput gains on AMD Instinct GPUs while preserving target-model decoding semantics - 1.69x to 2.00x for Kimi-K2.5 and up to 1.79x for MiniMax-M2.5 in our 1K/1K sweeps. What makes this practical end to end is the combination of (1) AMD Quark MXFP4/FP8 quantization for the target and selected draft checkpoints, (2) a vLLM-centric training pipeline that synthesizes on-policy data, extracts hidden states, and selects checkpoints by real served acceptance, and (3) ROCm/vLLM speculative serving. The released AMD Quark toolkit provides the quantization workflows; EAGLE3 draft-training support on AMD Instinct GPUs is planned for the next AMD Quark release.
Acknowledgements
We would like to thank the AMD Quark team, the AMD ROCm and vLLM contributors, the InferenceX maintainers and reviewers, and the EAGLE3 research community for their work and feedback. Special thanks to Chang Liu, Xinjun Niu, Wei Luo, Lin Zhao.