要点速览
- Speculators v0.3.0 提供 Eagle3 draft model 端到端训练(含 MoE verifier),产物可一键部署到 vLLM。
- Eagle3 训练数据四要素:三层 hidden states、token ids、loss mask、verifier 输出概率。
- 数据生成离线三段式:预处理、经 vLLM 插件在 prefill 捕获 hidden states、异步落盘 .pt。
- 训练用 train-time-testing 模拟多步采样,FlexAttention 处理稀疏 mask,序列拼接式 batching。
- 支持 Llama 3.x(8B-70B)、Qwen3 dense/MoE(至 235B-A22B)、GPT-OSS;Llama 4 仅支持 serving。
解决什么问题
推测解码能把模型延迟降低 1.5-3x,但前提是拥有与 verifier 高度对齐的专用 draft model,而为每个 LLM 训练 draft model 困难且耗时,面向 vLLM 的生产级训练工具也十分稀缺。这篇文章解决的问题是:如何端到端地生成训练数据、训练 Eagle3 draft model,并让训练产物能像普通模型一样在 vLLM 中无缝部署。
核心思路
Speculators v0.3.0 把流程拆为三段:先做数据预处理(会话重排、应用 chat template、tokenize、计算 loss mask、统计 token 频率);再通过 vLLM 插件系统以自定义 worker 扩展 patch 模型 forward,在 prefill 阶段拦截捕获三个中间层的 hidden states,并用 ThreadPoolExecutor 异步写盘。训练阶段用 Eagle3 的 train-time-testing 模拟多步 draft 采样,借助 FlexAttention 与 torch.compile 高效处理稀疏 attention mask,变长样本则沿 sequence 维拼接并用 attention mask 区分。训练产物自带 speculators_config 自描述配置,一条 vllm serve 命令即可同时加载 draft 与 verifier 并启用推测解码,也可用 --speculative-config 长格式换 verifier 或调参数。
关键要点
- 为什么需要 Speculators — 推测解码在低吞吐场景(GPU 未饱和、能利用 verifier 并行生成多 token)效果最好,且 draft model 必须与 verifier 紧密对齐,因此通常要为每个 verifier 单独训练。此前缺少面向 vLLM 的生产级训练工具链,Speculators v0.3.0 补上了从数据生成、训练到部署的完整环节,支持单层与多层 draft model、MoE 与非 MoE verifier。
- Eagle3 原理与训练数据四要素 — Eagle3(Zhang et al., 2025)是当前 SOTA 推测解码算法:draft 模型以 verifier 模型三个中间层的 hidden states(捕获 latent features)加 token ids 为输入,自回归生成 draft token。训练 Eagle3 因此需要含四类成分的数据集:三层 verifier hidden states、token ids、loss mask(只训模型回复、忽略用户 prompt)、verifier 输出概率(训练目标)。
- 离线数据生成流水线 — 预处理阶段完成会话格式化与归一化、应用 chat template、tokenize、基于 assistant 回复区间计算 loss mask,并统计 token 频率;针对只在最后一轮插入 thinking token 的 reasoning 模型,提供随机丢弃对话轮次的开关以覆盖不同会话长度。hidden states generator 利用 vLLM 插件系统注册自定义 worker 扩展,patch 模型 forward 在 prefill 阶段拦截中间 hidden states,借助 multiprocess executor 高效批量推理并支持 tensor parallelism。每个样本保存为独立 .pt 文件(input_ids、hidden_states、loss_mask),配合 data_config.json 与 token_freq.pt,写盘用 ThreadPoolExecutor 异步并行以最大化吞吐。
- draft 词表压缩(t2d/d2t 映射) — token 频率数据用于构建 target-to-draft(t2d)与 draft-to-target(d2t)映射文件,在 verifier 全词表与 draft 的小词表之间转换。压缩后的 draft 词表只保留最高频的 token(典型 10k-32k),从而提升 draft 模型的效率。相关脚本为 data_generation_offline.py 与 build_vocab_mapping.py。
- 训练:train-time-testing + FlexAttention + 拼接式 batching — 训练采用 Eagle3 作者提出的 train-time-testing:在训练中模拟多步 draft 采样——对每个前缀生成第一个 token,对前缀加第一步的结果再生成第二个,依此类推——确保模型学会预测第一个之后的 token。该过程的 attention mask 稀疏,常规实现难以高效处理,Speculators 用 FlexAttention 将 mask 分块、只计算非空区域,配合 torch.compile 加速并大幅降低反向传播所需激活显存。变长样本不靠 padding,而是沿 sequence 维拼接后用 attention mask 视为独立序列,配合智能 batch 采样将样本紧凑装填到接近最大序列长度。全部能力可通过单个 train.py 脚本使用。
- 一键部署与长格式配置 — 训练完成后生成带扩展 config.json(内含 speculators_config)的完整模型工件,vllm serve RedHatAI/Llama-3.1-8B-Instruct-speculator.eagle3 一条命令即可:vLLM 读取其中的推测解码设置(如 verifier 名称),把 draft 与 verifier 加载进同一 server 并启用推测解码。需要更多控制时可用长格式:以 --speculative-config 指定 draft 模型、method 与 num_speculative_tokens,例如用 FP8 量化的 Qwen3-8B 替代默认 BF16 verifier,并把 speculative tokens 从默认 3 提到 5 以追求更高吞吐。
- speculators_config 的结构 — 配置分三块:模型身份(architectures 如 Eagle3Speculator、auto_map 保证 HuggingFace 兼容加载、Speculators_model_type);draft 模型架构(transformer_layer_config 完整描述 draft 的 transformer 层、draft_vocab_size 缩减词表);推测解码配置(algorithm、proposal_methods 中的 speculative_tokens/verifier_accept_k/accept_tolerance,以及 verifier 的 name_or_path 与 architectures 兼容性校验)。这种标准化格式让模型自包含、知道自己该如何运行。
- 支持矩阵与下一步规划 — vLLM serving 与 Speculators 训练均支持:Llama 3.1/3.2/3.3(8B 到 70B)、Qwen3 dense(8B/14B/32B)、Qwen3 MoE(235B-A22B)、GPT-OSS(20B/120B);Llama 4 视觉语言模型目前仅支持 vLLM serving。下一步计划:online data generation(训练时直接生成 hidden states、不落盘)、视觉语言模型的数据生成、以及 regenerating verifier responses(用 verifier 自己生成的回复替换数据集回复,获得更对齐的训练数据)。
关键数据
| 指标 | 数值 | 条件 |
|---|---|---|
| 推测解码的延迟降低幅度 | 1.5-3x | 文章对推测解码总体效果的综述性描述,未限定具体模型/硬件 |
| draft model 典型规模 | 单个 transformer block | Eagle3 类推测解码中 draft 模型的常见配置(往往只有一个 transformer 块) |
| draft model 输入的 verifier hidden states 层数 | 3 层 | Eagle3 算法:取 verifier 模型三个中间层的 hidden states 作为 draft 输入 |
| draft 词表规模 | 典型 10k-32k tokens(示例配置 draft_vocab_size 为 10000) | Llama-3.1-8B-Instruct 的 Eagle3 speculator 模型配置 |
| 默认与调优后的 speculative tokens 数 | 默认 3,示例调至 5 | Qwen3-8B FP8 量化 verifier + Eagle3 draft,通过 vLLM --speculative-config 调整 |
| 训练+推理均支持的 verifier 参数范围(Llama 系列) | 8B 到 70B | Llama 3.1/3.2/3.3 系列,Speculators 训练与 vLLM serving 双向支持 |
| 支持的最大 MoE verifier 规模 | 235B-A22B(mixture-of-experts) | Qwen3 MoE,Speculators 训练 + vLLM serving 支持矩阵 |
“Altogether this can reduce model latency by 1.5-3x resulting in significantly faster generation.”
“The draft model which is cheap and fast to run (often just a single transformer block) does the heavy lifting and auto-regressively predicts several tokens.”
“Eagle3 draft models take the hidden states from three layers of the verifier model as input, capturing the verifier’s latent features.”
前置知识
推测解码基本原理(draft/verifier 分工与并行验证),建议先读 2024-10-17 入门篇 · EAGLE/Eagle3 算法的大致结构(复用 verifier 的 hidden states 起草) · HuggingFace 模型 config.json、chat template 与 tokenizer 的基本概念 · 训练基础:attention mask、padding/截断、torch.compile · MoE(mixture-of-experts)模型结构 · vLLM serving 基本用法(vllm serve 及 --speculative-config)
术语表
Speculators: vLLM 项目下的库,提供推测解码 draft model 的端到端训练工具链(数据生成、训练、配置),产物可直接被 vLLM 加载服务。Eagle3: 当前 SOTA 的推测解码算法:draft 模型以 verifier 三个中间层的 hidden states 加 token ids 为输入,自回归生成 draft token。Verifier Model: 验证模型:被服务的原始 LLM,并行处理 draft 提议的 token 并逐个判断接受或拒绝;拒绝后其余序列被丢弃。Hidden States: 隐藏状态:transformer 各中间层的激活输出,是 Eagle3 训练数据的核心成分,需在 prefill 阶段从 verifier 中捕获。Loss Mask: 损失掩码:标记哪些 token 参与损失计算的二值掩码,用于只训练模型回复、忽略用户 prompt 部分。Train-time-testing: Eagle3 作者提出的训练技巧:在训练中模拟多步 draft 采样过程,使模型学会预测第一个 token 之后的后续 token。FlexAttention: PyTorch 的注意力实现,将 attention mask 划分为块并只计算非空区域,配合 torch.compile 可加速计算并大幅降低反向传播的激活显存。t2d/d2t Mapping: target-to-draft 与 draft-to-target 词表映射,把 verifier 的全词表压缩为 draft 模型的高频小子词表以提升效率。MoE: Mixture-of-Experts,混合专家模型架构;Speculators 支持为 MoE verifier 训练 draft model。speculators_config: 嵌入模型 config.json 的自描述配置,记录 draft 架构、算法参数与 verifier 信息,使一条 vllm serve 命令即可完成推测解码部署。Draft Vocabulary: draft 模型使用的缩减词表(典型 10k-32k token),仅包含最高频 token,通过 t2d/d2t 映射与 verifier 全词表对接。
Diving into speculative decoding training support for vLLM with Speculators v0.3.0
Key Highlights
- Speculative decoding serves as an optimization to improve inference performance; however, training a unique draft model for each LLM can be difficult and time-consuming, while production-ready training utilities for generating models for vLLM are scarce
- Speculators v0.3.0 provides end-to-end training support for Eagle3 draft models that can seamlessly run with vLLM
- Support for training includes offline data generation using vLLM as well as training capabilities for single- and multi-layer draft models, for both MoE and non-MoE verifiers
Inference at scale
Over the past decade, LLMs have expanded rapidly in both scale and capability, bringing with it increasing demands on inference performance. As LLMs generate tokens sequentially—with each token requiring a full forward pass through billions of parameters—the cost of generation scales quickly. As model sizes continue to rise, this sequential computation becomes a significant bottleneck, making today’s LLMs incredibly capable yet often slow.
One promising optimization to alleviate this challenge is speculative decoding, which accelerates generation by allowing smaller draft models to propose tokens that the larger model can quickly verify.
This blog will explore speculative decoding as an optimization technique, introduce the Speculators library, and dive into it and its recent v0.3.0 release. Speculators provides researchers, engineers, and ML practitioners the tools to generate speculative decoding models end-to-end with seamless vLLM integration.
What is speculative decoding?
Speculative decoding allows LLMs to generate multiple tokens in a single forward pass. It works by utilizing a small “draft” model in conjunction with the full sized “verifier” model (i.e, the original LLM that you are trying to serve). The draft model which is cheap and fast to run (often just a single transformer block) does the heavy lifting and auto-regressively predicts several tokens. The verifier model processes these tokens in parallel. For each token, the verifier determines if it agrees with the draft’s prediction or not. If the verifier rejects a token, the rest of the sequence is discarded, otherwise the tokens are included in the verifier model’s response.
The advantages of this approach are: 1. The final response comes from the same distribution as using the verifier model alone, which ensures there is no degradation in model performance using speculative decoding. 2. The verifier model is able to generate multiple tokens in parallel. 3. Because the draft model is small, it usually produces minimal overhead to run
Altogether this can reduce model latency by 1.5-3x resulting in significantly faster generation.
Using speculative decoding models in vLLM
vLLM and Speculators make running speculative decoding models as easy as serving any other model with vllm serve. In particular, speculative decoding performs best in low-throughput scenarios, where GPUs are not fully saturated and can take advantage of the verifier model’s parallel token generation. It is also important for the draft model to align closely with the verifier model, which is why we train draft models specific to each verifier. However, having to train an LLM-specific draft model can be difficult and time consuming. Fortunately, the Speculators library simplifies this training process and enables users to produce draft models with seamless integration into vLLM.
Creating new draft models
The current SOTA for speculative decoding algorithms is Eagle3 (Zhang et al., 2025).
Eagle3 draft models take the hidden states from three layers of the verifier model as input, capturing the verifier’s latent features. Combined with the token ids, these hidden states are passed through the smaller draft model, which auto-regressively generates draft tokens.
This means that training an Eagle3 draft model requires a dataset of sample sequences with the following components: 1. Verifier model hidden states (from three intermediate layers) 2. Token ids 3. Loss mask (used to train only on model responses, ignoring user prompts) 4. Verifier model output probabilities (the training target for the draft model)
Data Generation
Extracting these values directly from vLLM is non-trivial. Fortunately, Speculators v0.3.0 supports offline training data generation through a hidden states generator, which produces hidden state tensors from standard LLM text datasets. These hidden state tensors are then saved to disk for later use in the training process.
There are three main parts of data generation: preprocessing, hidden states generation and saving.
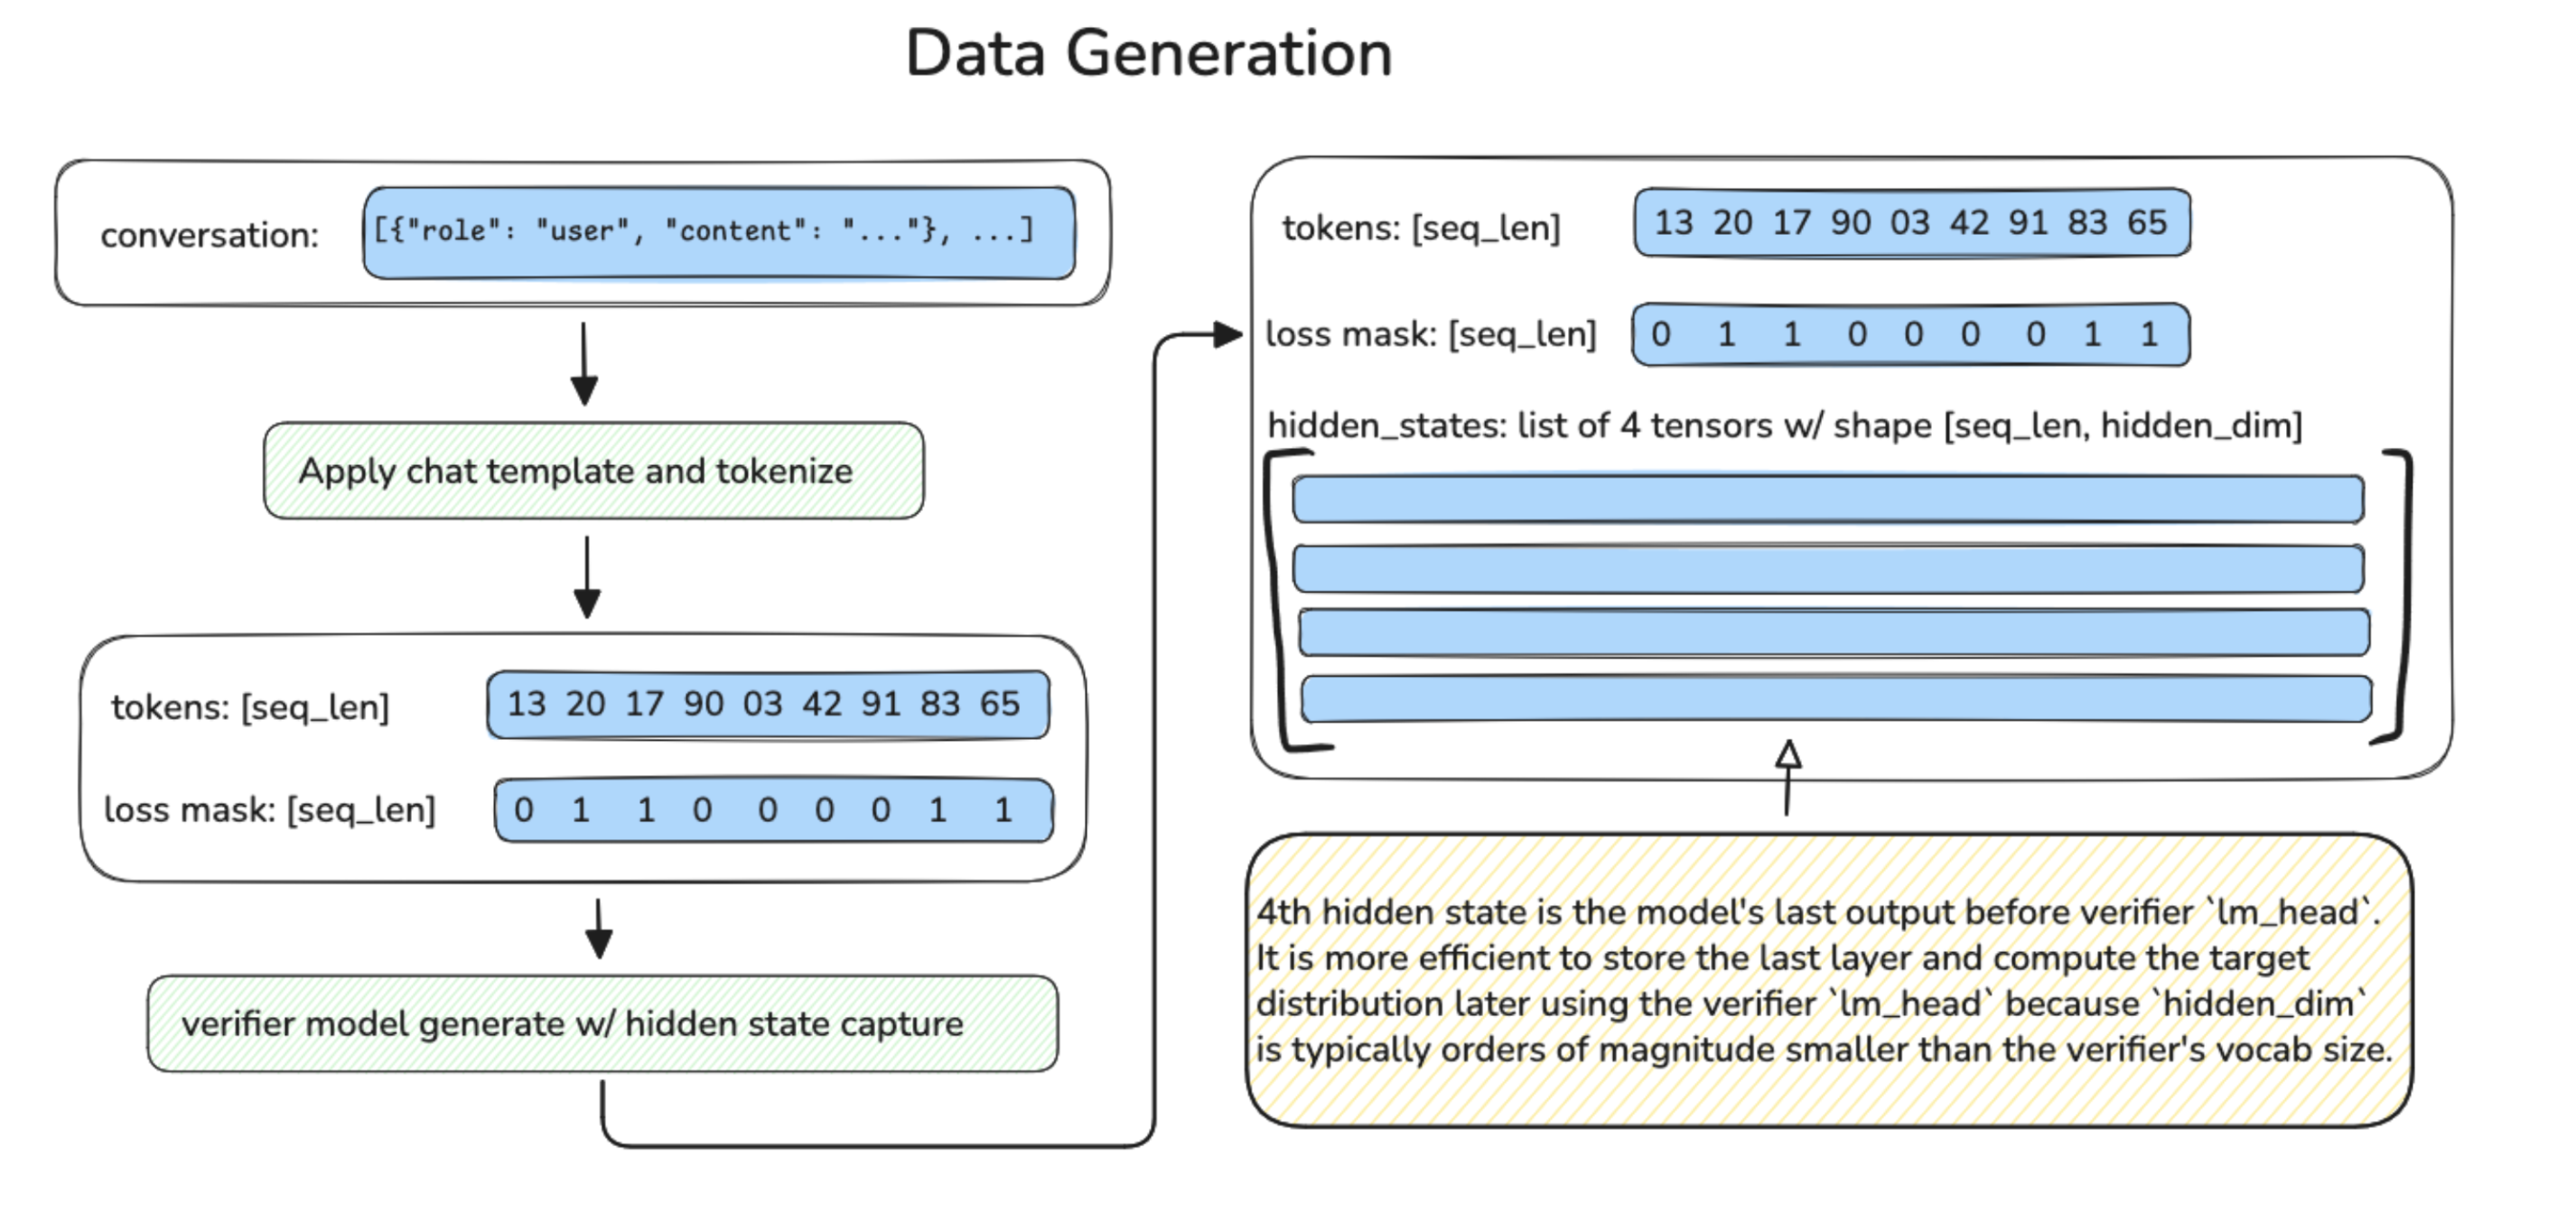
Preprocessing takes in a raw dataset, 1. Reformats and normalizes conversation turns 2. Applies the model’s chat template 3. Tokenizes the conversation 4. Calculates loss masks based on assistant response spans 5. Saves it to disk along with the token IDs 6. Collects statistics on token frequencies, which are saved to disk for later use
The loss masks ensure training focuses only on machine generated tokens. For reasoning models which typically only insert thinking tokens in the last response, Speculators provides an extra flag to randomly drop turns of the conversation to ensure the model trains on a variety of conversation lengths.
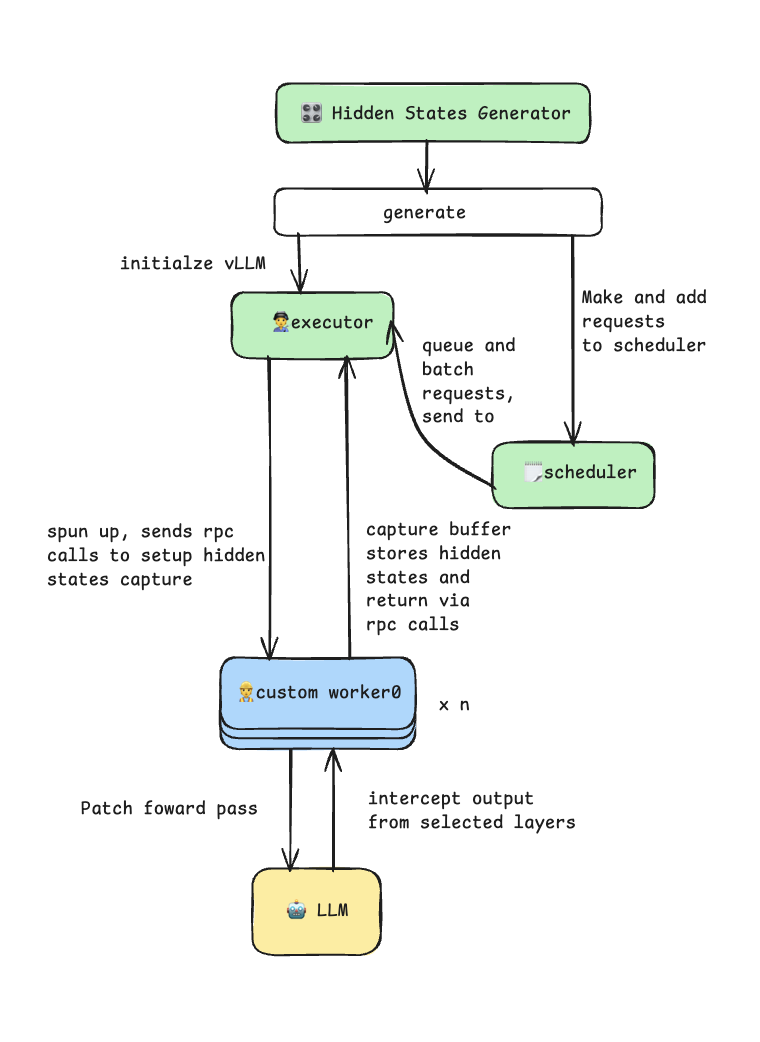
The hidden states generator takes advantage of the vLLM plug-in system through a custom worker extension. It patches the model’s forward pass to intercept and capture intermediate hidden states during the prefill phase. The generator uses vLLM’s multiprocess executor for efficient batch inference and supports tensor parallelism for larger models. This process is illustrated in the diagram below.
During the saving phase, each processed sample is saved as an individual .pt file on disk, containing:
- input_ids: tokenized input sequences
- hidden_states: list of tensors on per captured layer
- loss_mask: binary mask indicating trainable tokens
The generator uses asynchronous I/O with ThreadPoolExecutor to parallelize disk write while hidden states generation continues, maximizing throughput.
Along with the data files, two additional files are saved to disk:
- data_config.json, which contains metadata about the data generation
- token_freq.pt, which contains information about token frequencies
The frequency data stored in token_freq.pt is used to build additional target-to-draft (t2d) and draft-to-target (d2t) files. These files act as mappings between the verifier’s full vocabulary and the smaller vocabulary of the draft model. This reduced “draft” vocabulary improves the efficiency of the draft model by including only the most frequently occurring tokens.
The following scripts can be used to enable offline data generation:
- data_generation_offline.py: preprocesses data, saves token-frequency distribution, and generates hidden states
- build_vocab_mapping.py: builds t2d and d2t tensors
Training
Speculators v0.3.0 supports training Eagle3 draft models. Training takes as input the generated samples and vocabulary mapping files from the previous steps, along with model configuration information and initializes a new Eagle3DraftModel instance. This model is then trained using a technique introduced by the Eagle3 authors called “train-time-testing”. Train-time-testing simulates the multi-step draft sampling process during training to ensure the model learns to predict not just the first token, but also subsequent ones.
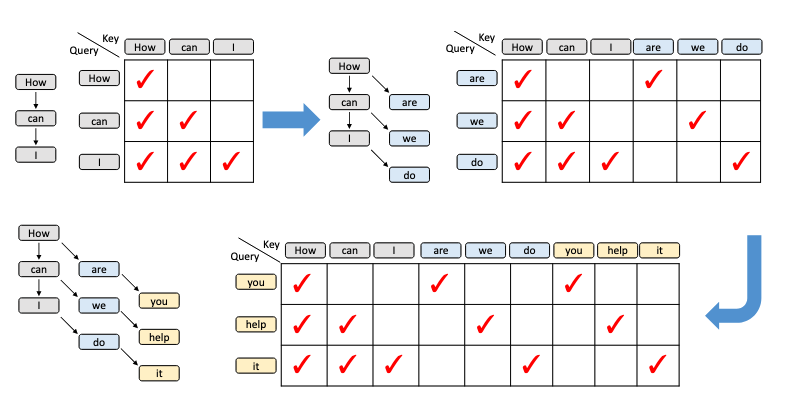
Diagram from Eagle3 (Zhang et al., 2025) paper.
The diagram above shows the train-time-testing process, and the attention mask at each step. For every prefix, the draft model generates a next token (blue). Then for every prefix plus first generation step, the model generates a second token (yellow), and so on.
Train-time-testing is challenging to implement because the attention mask is sparse which typical attention implementations struggle to handle in a compute and memory efficient way. That is why Speculators uses FlexAttention (He et al., 2024) for attention computations. FlexAttention splits the attention mask into blocks and only computes attention in non-empty regions. Combined with torch.compile, this speeds up computation while drastically reducing the activation VRAM required for the backward pass.
Another important feature for any training implementation is batching. Batching samples for LLM training is made more complicated by the fact that sequences are typically different lengths. There are two approaches to this problem, the first is to make the sequences the same length using some combination of truncation and padding. This works well for datasets with uniform lengths, but can lead to wasted compute on datasets that need a lot of padding. Instead, Speculators v0.3.0 uses the second approach, which is to concatenate sequences along the “sequence” dimension, and then configure the attention masks to treat them as separate sequences. This integrates well with the FlexAttention implementation, and results in better performance, particularly when combined with an intelligent batch sampling algorithm which efficiently packs samples into batches that are close to the max sequence length.
Together these components make Speculators Eagle3 model training fast and memory efficient, all of which can be applied using a single train.py script.
Running Speculators models in vLLM
Once training is complete, the library generates a complete model artifact with an extended config.json file that includes a speculators_config. Models can then be run seamlessly in vLLM using a simple vllm serve command:
vllm serve RedHatAI/Llama-3.1-8B-Instruct-speculator.eagle3
When running this command, vLLM will read the speculative decoding settings (e.g., the name of the verifier model) stored in the speculators_config. This information is used to load both the draft model and the verifier model into the same server and set up speculative decoding. The speculators_config provides a standardized configuration format, enabling a self-contained model that knows how it should run while making deployment of speculative decoding models as simple as running any other LLM. For further details on the speculators_config, see an example below.
While the simplified one-command deployment is perfect for getting started, vLLM also provides a long-form syntax when you need more control. This is useful for:
- Using a different verifier model than the one in the config
- Tuning for speculative decoding parameters, such as the number of speculative tokens
The long-form command serves the base (verifier) model and specifies the speculator via the --speculative-config flag.
This flexibility is crucial for experimentation and optimization. For example, you might want to swap in a quantized version of the verifier to further improve performance:
vllm serve RedHatAI/Qwen3-8B-FP8-dynamic \
  --tensor-parallel-size 1 \
  --gpu-memory-utilization 0.9 \
  --speculative-config '{"model": "RedHatAI/Qwen3-8B-speculator.eagle3", "num_speculative_tokens": 5, "method": "eagle3"}'
In this example, we're using the FP8-quantized Qwen3-8B as the verifier (instead of the default BF16 version referenced in the speculators_config) and increasing the number of speculative tokens from the default 3 to 5 for potentially higher throughput.
vLLM Integration: Production-Ready Speculative Decoding
The tight integration between Speculators and vLLM transforms speculative decoding from a research technique into a production-ready feature. vLLM's support for Eagle3 enables seamless deployment across diverse model architectures and configurations:
vLLM serving and Speculators training: - Llama (3.1, 3.2, 3.3): 8B to 70B parameters - Qwen3: 8B, 14B, 32B parameters - Qwen3 MoE: 235B-A22B parameters (mixture-of-experts) - GPT-OSS: 20B, 120B parameters
vLLM serving only: - Multimodal: Llama 4 vision-language models
What’s Next?
Speculators will be focusing on the following next set of features: - Online data generation (generate hidden states while training, with no intermediate caching to disk) - Data generation support for Vision Language models - Regenerating verifier responses (replace the dataset “assistant” response with one generated by the verifier for better aligned training data)
Get involved!
Interested in learning more about speculative decoding? Check out the Speculators repository and help grow the repository by checking out Good First Issues!
For additional resources, documentation, and slack channels, check out:
- Speculators Documentation: https://docs.vllm.ai/projects/speculators/en/latest/
- vLLM slack channels: #speculators, #feat-spec-decode
- Data Generation and Training Scripts: https://github.com/vllm-project/speculators/blob/main/scripts/README.md
- End-to-end examples: https://github.com/vllm-project/Speculators/tree/main/examples/data_generation_and_training
- For a list of already trained Speculators models, check out the Red Hat AI Hub
Appendix
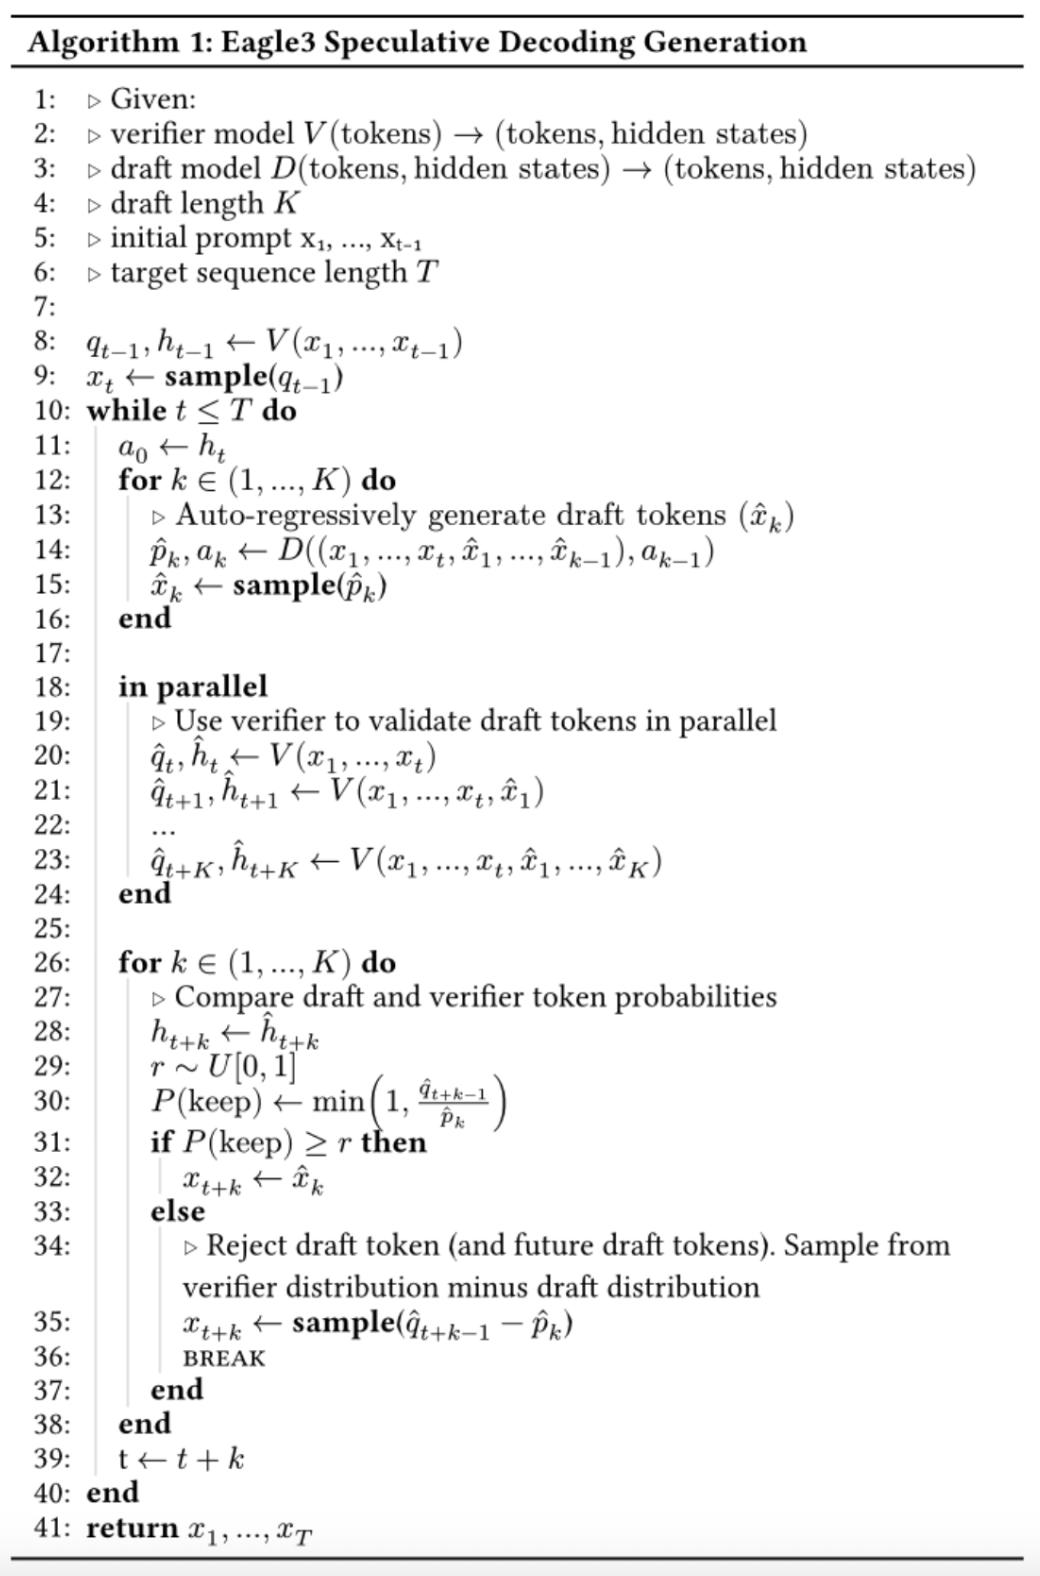
Eagle3 Algorithm
speculators_config:
{
  "architectures": ["Eagle3Speculator"],
  "auto_map": {"": "eagle3.Eagle3SpeculatorConfig"},
  "Speculators_model_type": "eagle3",
  "Speculators_version": "0.3.0",

  "draft_vocab_size": 10000,
  "transformer_layer_config": {
    "num_hidden_layers": 1,
    "hidden_size": 4096,
    ...
  },

  "Speculators_config": {
    "algorithm": "eagle3",
    "proposal_methods": [{
      "proposal_type": "greedy",
      "speculative_tokens": 3,
      ...
    }],
    "verifier": {
      "name_or_path": "meta-llama/Llama-3.1-8B-Instruct",
      "architectures": ["LlamaForCausalLM"]
    }
  }
}
This config defines the speculator as a complete model with:
- Model Identity:
architectures: The speculator's model class (e.g., Eagle3Speculator)auto_map: Custom model loading for Hugging Face compatibilitySpeculators_model_type: The specific speculator implementation
- Draft Model Architecture:
transformer_layer_config: Full specification of the draft model's transformer layersdraft_vocab_size: Reduced vocabulary size for efficient draft generation (typically 10k-32k tokens)- Model-specific configuration options
- Speculative Decoding Configuration:
algorithm: The spec decoding algorithm (EAGLE3)proposal_methods: Token generation strategies with parametersspeculative_tokens: Number of draft tokens to generate per stepverifier_accept_k: How many top-k predictions to consider during verificationaccept_tolerance: Probability threshold for accepting draft tokens
verifier: Which verifier model to use and validate againstname_or_path: HuggingFace model ID or local patharchitectures: Expected verifier architecture for compatibility checks