要点速览
- 推测解码采用 draft-and-verify:轻量 draft 组件提出候选 token,目标模型单次验证即可提交多个 token,且不改变目标模型输出行为。
- 五种方法分三类:原生 MTP 模块、独立 MTP drafter(Gemma 4)、专用 draft 网络(EAGLE-3/DFlash/DSpark)。
- EAGLE-3 自回归起草;DFlash 一次前向并行预测整个 draft block;DSpark 加轻量 Markov head 引入依赖。
- vLLM 用 --speculative-config 启用,关键参数是 method、model 与 num_speculative_tokens。
- MI300X/MI355X 实测:多个模型-负载组合加速超 2×,最高 2.87×(DFlash,gemma-4-26B-A4B-it,MATH500)。
- 最优 N 随模型与负载变化(DFlash 常在 N=7 附近最优);需用代表性负载扫参并监控接受率、MAL 与逐位置接受率。
解决什么问题
标准自回归解码每个 decode 步只能提交一个 token,长生成场景下这一逐 token 循环主导延迟并限制服务吞吐。这篇文章系统解答:在 vLLM(尤其是 AMD Instinct GPU + ROCm 环境)中推测解码有哪些方法、各自机制如何、怎样启用和调参、实际能带来多大加速,以及如何为没有现成 draft 模型的目标模型训练 speculator。
核心思路
文章先从自回归基线出发引出 draft-and-verify 核心机制,并用 accept/reject 示例讲清『从左到右验证、首个拒绝位置由目标模型给替换 token』的规则。随后按三类架构(原生 MTP 模块、独立 MTP drafter、专用 target-conditioned draft 网络)逐一拆解五种方法的条件信息来源与顺序/并行生成方式。接着给出 vLLM --speculative-config 配置表、预训练 draft 模型来源,以及在 9 个目标模型 × GSM8K/MATH500/HumanEval/MBPP 上的吞吐与接受率测量。最后沉淀调优方法论(扫 N、监控接受行为、按负载匹配)与 speculator 训练 workflow,附录提供逐位置接受率热图与每个模型的完整 serving 命令。
关键要点
- 自回归基线与 draft-and-verify 核心机制 — 标准自回归解码中每个输出 token 都需要一次模型 decode 步骤,长生成时该循环成为延迟与吞吐瓶颈。推测解码将『提出』与『验证』分离:draft 组件一次提出若干候选未来 token,目标模型在单次 verification pass 中从左到右检查;被接受的 token 直接提交,首个被拒绝的位置由目标模型给出替换 token,其后候选全部丢弃。这样一次目标模型前向可提交多个输出 token,同时保持目标模型的输出行为。
- 三种 draft 架构类别与五种方法总览 — 作者把五种方法归为三类:原生 MTP 模块(内置于目标模型架构,顺序生成候选)、独立 MTP drafter(Gemma 4 MTP,独立 checkpoint 但推理时与目标模型紧密耦合)、专用 target-conditioned draft 网络(EAGLE-3、DFlash、DSpark,为特定目标模型单独训练)。差异体现在三方面:从目标模型接收的信息类型(hidden 表示、多层 hidden states、KV cache 等)、信息如何进入起草过程、候选 token 是顺序还是并行生成。一个目标模型可以同时拥有原生 MTP 与单独训练的 EAGLE-3/DFlash/DSpark draft 模型。
- Native MTP:模型内置的辅助预测路径 — 第一步将目标模型 hidden 表示与当前 token 信息(如 shifted input-token embedding)沿 hidden 维度融合,经模型特定的 fusion/projection 进入辅助预测层得到第一个 draft token;后续步骤用上一个 MTP 步产生的 hidden state 加最新 draft token 继续预测。num_speculative_tokens 可超过 checkpoint 自带的 MTP 深度,vLLM 会通过额外前向复用 MTP 路径,因此更大的 N 意味着更多顺序起草工作。由于 MTP 路径常与目标模型共享组件(如 embedding 表、输出头),额外显存开销相对较小。
- Gemma 4 MTP:共享 KV cache 的独立 drafter — Gemma 4 的 MTP 是单独打包的 checkpoint,与特定目标模型配对,推理时使用目标模型产生的 activations 并直接共享目标模型的 KV cache,从而复用目标模型已算好的上下文而非独立重算已接受前缀。候选 token 仍按顺序生成;draft 组件层数与配置的推测长度是两个独立概念。
- EAGLE-3:三层 hidden states 融合 + 自回归起草 — EAGLE-3 在目标模型前向中记录靠近开头、中部与结尾三个阶段的 hidden states,拼接并投影成单一 fused target feature,再与采样 token 的 embedding 结合送入 draft decoder。draft token 逐个自回归生成:首个 token 用融合特征 + 采样 token embedding,后续位置因目标模型尚未处理这些 speculative 位置,改用上一个 draft 组件输出作为条件。token 间存在直接依赖,但更长的推测长度意味着更多顺序起草开销。
- DFlash:一次前向并行预测整个 draft block — 每个 draft block 以一个已确认的 anchor token 开头(通常是上一轮验证返回的目标模型 token),其余位置全部 masked,由单次 draft 网络前向并行预测。与 EAGLE-3 只在输入端融合不同,DFlash 把融合后的目标上下文转换为每一层都可用的额外 Key/Value 表示,masked 位置的 query 同时 attend 目标侧 K/V 与 draft block 自身 K/V。由于同一 pass 内后面位置看不到前面位置的采样结果,去掉了自回归反馈,长 block 后段的效果依赖训练质量与负载。
- DSpark:并行主干 + 轻量 Markov 纠正 — DSpark 用修改版 DFlash 作为并行主干,一次前向产出所有 draft 位置的 hidden states 与 base logits;随后一个轻量 Markov head 从左到右用上一个已选 draft token 生成 bias 修正各位置 logits,避免纯并行预测产生『of problem』这类不一致组合,而无需每个位置重跑完整 draft 网络。其设计还包含按置信度选择更短验证前缀的 confidence head,但文中实验所用 vLLM 路径未启用该功能,基准结果只反映并行网络 + Markov 纠正。
- vLLM 配置方式与 draft 模型来源 — 统一通过 --speculative-config 启用,method 取值 mtp/eagle3/dflash/dspark;除原生 MTP(无需 model 字段)外,都需在 model 字段指向与目标模型匹配的 draft checkpoint,并设置 num_speculative_tokens。启用前应确认 vLLM 版本支持该方法和架构、draft checkpoint 兼容、N 与 checkpoint 兼容、model card 支持目标硬件与 backend。预训练 draft 模型来源:Google(Gemma 4 MTP assistants)、Red Hat AI(-speculator.eagle3/dflash/dspark 系列)、Z-Lab(<target>-DFlash)、DeepSeek DeepSpec(eagle3/dflash/dspark 三种方法)、LightSeek(Kimi EAGLE)与 Inferact(MiniMax/Kimi)。注意独立 draft 权重需要预留 GPU 显存余量。
- 实验设置与主要基准结论 — 在 8× MI300X(MiniMax-M3-MXFP8 实验用 8× MI355X)、ROCm 环境下,覆盖 9 个目标模型与 GSM8K/MATH500/HumanEval/MBPP 任务级基准,指标为输出吞吐相对非推测基线的加速比、mean accepted length 与接受率。gemma-4-26B-A4B-it 上各方法最佳加速为 2.11×–2.87×;gemma-4-31B-it 上 DFlash 达 2.34×;Qwen3-8B 上 DSpark 1.15×–1.63×(EAGLE-3 在 MATH500 上甚至低于基线);Qwen3.5/3.6 系列原生 MTP 最高 2.20×;Kimi-K2.5 上 DFlash 达 2.68×。加速比随模型、draft checkpoint、负载与 N 变化,部分配置低于基线,同家族不同模型(如 Qwen3.6-27B 与 35B-A3B)结果也可能明显不同。
- 调优方法与 speculator 训练 workflow — 把推测解码视为运行时优化而非固定设置:从 checkpoint 推荐配置起步(原生 MTP 可从 N=1 保守起步),用代表性负载扫 N——顺序方法常先升后进入平台,DFlash 常在 N=7 附近最优(部分负载 N=11),block_size=16 的 DFlash checkpoint 上限是 N=15。同时监控吞吐、MAL、整体与逐位置接受率:若前几个位置接受率高而后面位置贡献很小,应减小 N。为新目标模型训练 speculator 时,训练响应必须由目标模型自己生成(tokenizer/chat template/thinking 模式都要匹配部署),hidden states 可选 online/offline/hybrid 三种获取模式,训练后以接受长度、接受率、draft 延迟、显存与端到端吞吐评判,而非只看训练 loss。
关键数据
| 指标 | 数值 | 条件 |
|---|---|---|
| 实验硬件配置 | Hardware 1: 8× MI300X (gfx942) + 2× EPYC 9654;Hardware 2: 8× MI355X (gfx950) + 2× EPYC 9575F(仅用于 MiniMax-M3-MXFP8 实验) | 全部吞吐与接受率测量的硬件条件;软件栈为 ROCm/HIP 7.2.53211、vLLM 0.23.1rc1.dev、PyTorch 2.11.0 |
| 全文观测到的最大加速比(DFlash,gemma-4-26B-A4B-it) | 2.87×(DFlash,MATH500);同目标上 Gemma 4 MTP 达 2.83×;Kimi-K2.5 上 DFlash 达 2.68× | AMD MI300X,扫 num_speculative_tokens 后各实验的最大吞吐比 |
| gemma-4-26B-A4B-it 各方法最大加速比 | Gemma 4 MTP 2.74×(GSM8K)/2.62×(MBPP);DFlash 2.87×(MATH500)/2.79×(HumanEval);EAGLE-3 2.11×–2.27× | google/gemma-4-26B-A4B-it,四种任务基准,MI300X,在测试的 N 扫描范围内取最大值 |
| gemma-4-31B-it 各方法最大加速比 | Gemma 4 MTP 2.00×(GSM8K)/1.99×(MBPP);DFlash 2.34×(MATH500)/2.05×(HumanEval) | google/gemma-4-31B-it,EAGLE-3 与 DSpark 在四个数据集上也都高于基线;最大吞吐对应的 N 随负载变化 |
| Qwen3-8B 上 DSpark 与 DFlash 加速范围 | DSpark 1.15×(MATH500)–1.63×(GSM8K);DFlash 1.08×–1.27×;EAGLE-3 在 MATH500 上最大值低于基线 | Qwen/Qwen3-8B(单卡),MI300X;显示同一目标模型上不同方法差异可达约 0.5× |
| Qwen3.5/Qwen3.6 系列原生 MTP 最大加速比 | 该组最大 2.20×(Qwen3.5-122B-A10B,MATH500);原生 MTP 最大值普遍高于同组 DFlash;最佳 N 在 4–7 之间 | Qwen3.5-27B、Qwen3.5-122B-A10B、Qwen3.6-27B(MI300X,TP=2 或 4) |
| Qwen3.6-35B-A3B 上 DFlash 与原生 MTP 对比 | DFlash 1.77×–2.06×(四个数据集最大值均在 N=7);原生 MTP 1.28×–1.49×(最大值在 N=6) | Qwen/Qwen3.6-35B-A3B,MI300X;与 Qwen3.6-27B 结果不同,说明同家族模型间差异明显 |
| Kimi-K2.5 与 MiniMax-M3-MXFP8 加速比 | Kimi-K2.5:EAGLE-3 最高 2.33×、DFlash 最高 2.68×;MiniMax-M3-MXFP8:EAGLE-3 达 2.09×(HumanEval,N=4) | Kimi-K2.5(TP=4,MI300X);MiniMax-M3-MXFP8(TP=8,MI355X);EAGLE-3 最大值多在 N=4,DFlash 多在 N=7 |
| 逐位置接受率衰减示例(Gemma 4 MTP,N=5) | p1=94%、p2=87%、p3=80%、p4=73%、p5=66%;整体 AR 80.0%,MAL 5.00,吞吐 6,434 tok/s(2.74×,基线 2,344 tok/s) | google/gemma-4-26B-A4B-it / Gemma 4 MTP / GSM8K / N=5,MI300X;说明后面位置贡献递减,是调 N 的关键依据 |
“Hardware 1: 8× AMD Instinct™ MI300X GPUs (gfx942) with 2× AMD EPYC™ 9654 96-Core Processor.”
“Examples at the upper end of the observed range included 2.87× for DFlash on gemma-4-26B-A4B-it, 2.83× for Gemma 4 MTP on the same target, and 2.68× for DFlash on Kimi-K2.5.”
“For gemma-4-26B-A4B-it, the largest measured throughput ratios within the tested sweep were 2.74× and 2.62× for Gemma 4 MTP on GSM8K and MBPP, respectively, and 2.87× and 2.79× for DFlash on MATH500 and HumanEval. The EAGLE-3 measurements ranged from 2.11× to 2.27× across the four datasets.”
前置知识
LLM 自回归解码流程与 KV cache 的作用 · Transformer 内部表示:hidden states、logits、token embedding · vLLM 基本使用:serving 启动参数与 tensor parallelism · 推测解码的基本目标:在不改变目标模型输出分布的前提下降低每 token 成本 · 常见任务基准:GSM8K、MATH500(数学)、HumanEval、MBPP(代码) · (可选)AMD ROCm 生态与 MI300X/MI355X 硬件背景
术语表
Speculative Decoding: 推测解码。通过 draft-and-verify 机制让目标模型一次验证多个候选 token,在不改变输出的前提下加速解码。Draft model / Speculator: 草稿模型(推测器)。为特定目标模型训练的轻量网络,负责提出候选未来 token。Target model: 目标模型。原始完整模型,负责验证候选 token 并决定最终提交的输出。MTP (Multi-Token Prediction): 多 token 预测。模型原生的辅助预测机制,预测紧邻下一个 token 之外的更多未来 token。EAGLE-3: 一种专用自回归 draft 网络,融合目标模型早/中/晚三个阶段的 hidden states 作为条件逐个生成 draft token。DFlash: 一种并行 draft 网络,draft block 以 anchor token 开头,单次前向同时预测全部 masked 位置。DSpark: 在 DFlash 式并行主干上增加轻量 Markov head(与置信度前缀选择)的 draft 方法。num_speculative_tokens (N): 每轮推测请求的候选 token 数量,即推测长度,是主要调优参数。Acceptance rate: 接受率。提出的 draft token 中被目标模型接受的比例。Mean accepted length (MAL): 平均接受长度。每轮推测平均被提交的 token 数。Anchor token: DFlash draft block 第一位置上由目标模型产生或确认的已知 token,draft 网络无需预测它。Markov head: DSpark 中用上一个已选 draft token 产生 logit bias 的轻量顺序纠正头。KV cache: 键值缓存。注意力计算中缓存的历史 K/V,Gemma 4 MTP 等 drafter 可直接共享复用。
Exploring Speculative Decoding in vLLM on AMD GPUs
TL;DR: Speculative decoding allows vLLM to verify multiple drafted tokens in a single target-model pass. In our experiments, its effect on output-token throughput varied across drafting methods and proposal lengths, and also depended on the model family, draft checkpoint, workload, and acceptance behavior.
Introduction
Large language models support a wide range of applications, but serving them at scale requires careful optimization. Standard autoregressive decoding is the baseline used by most LLM serving systems: the model generates one token, appends it to the sequence, and then uses the updated sequence to generate the next token. This process is simple and reliable, but the serving loop still advances one committed token at a time because output tokens must be produced in strict left-to-right order.
Speculative decoding [1] builds on this baseline through a draft-and-verify mechanism. A lightweight draft component proposes candidate future tokens, and the target model verifies those candidates before they are committed. When several draft tokens are accepted, the system can commit multiple output tokens from a single target-model verification step while preserving the target model's output behavior.
This post explores how speculative decoding works in vLLM and shares measurements from our test environment. We first review the autoregressive decoding baseline and the draft-and-verify process. We then examine five speculative-drafting approaches: native MTP, Gemma 4 MTP, EAGLE-3, DFlash, and DSpark. These methods differ in how the draft component receives information from the target model and whether candidate tokens are generated sequentially, autoregressively, in parallel, or through a hybrid approach. Finally, we show how to enable the methods tested in our environment, report measurements from our experiments on AMD Instinct™ MI300X and MI355X GPUs using the ROCm™ open software platform, and discuss practical tuning and observability considerations.
The autoregressive decoding baseline
In standard autoregressive decoding, each decode step produces and commits one new token. For example, generating four output tokens requires four sequential decode steps:
After each step, the generated token is appended to the sequence and becomes part of the input for the next step. This makes the decoding loop straightforward, but it also requires one model decode step for every output token. During long generations, this token-by-token loop can dominate latency and limit serving throughput.
The key question behind speculative decoding is therefore:
Can we preserve the output behavior of the original model while reducing how often generation advances by only one token at a time?
Speculative decoding addresses this by separating proposal from verification. A draft component first proposes several candidate future tokens. The original model, acting as the target model, then verifies those candidates before they are committed.
Core idea of speculative decoding
Speculative decoding does not replace the original model. Instead, it keeps the original model as the target model, which remains responsible for the final output, and adds a faster proposal stage in front of it.
The process has two parts:
- Draft: propose several candidate future tokens.
- Verify: use the target model to check those candidates.
During each speculative decoding round, as illustrated in Figure 1, a lightweight draft component proposes one or more future tokens. These tokens are only candidates and are not committed immediately. The target model then evaluates the candidate token sequence in one verification pass.
Verification proceeds from left to right. Each draft token is checked using the target model's result at the corresponding position. Accepted tokens are committed to the output sequence. When a draft token is rejected, later candidates from the same proposal are no longer accepted.
If a draft token is rejected, the target model provides the next token. The remaining draft tokens are discarded, and generation continues from the updated sequence.
Conceptually, standard autoregressive decoding advances like this:
Speculative decoding instead allows several candidate positions to be evaluated together:
This can reduce the number of target-model decoding rounds when multiple candidates are accepted. When the draft component produces tokens that the target model accepts, several output tokens can be committed from one target-model verification step. When a proposal is rejected, the target-side result determines how generation continues.
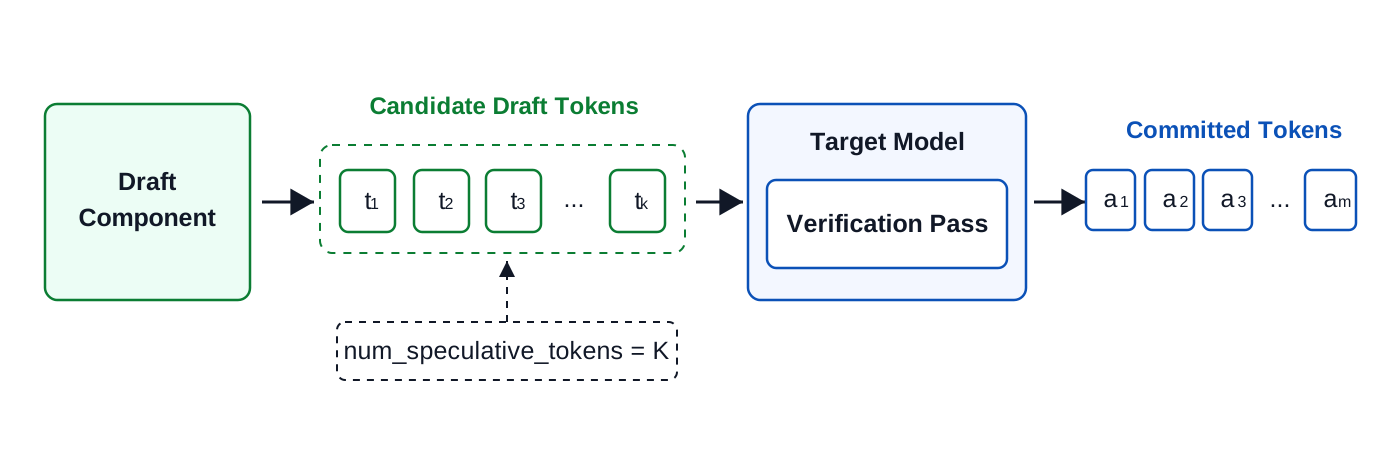
Figure 1. Speculative decoding flow: a draft component proposes candidate future tokens, and the target model verifies them before output tokens are committed.
A simple accept/reject example
Figure 2 gives an example of one speculative decoding round. Green boxes are draft tokens that survive verification, the red box marks the first rejected draft token, and the gray box is a later draft token that is discarded. The blue token in the output comes from the target model, not from the draft proposal.
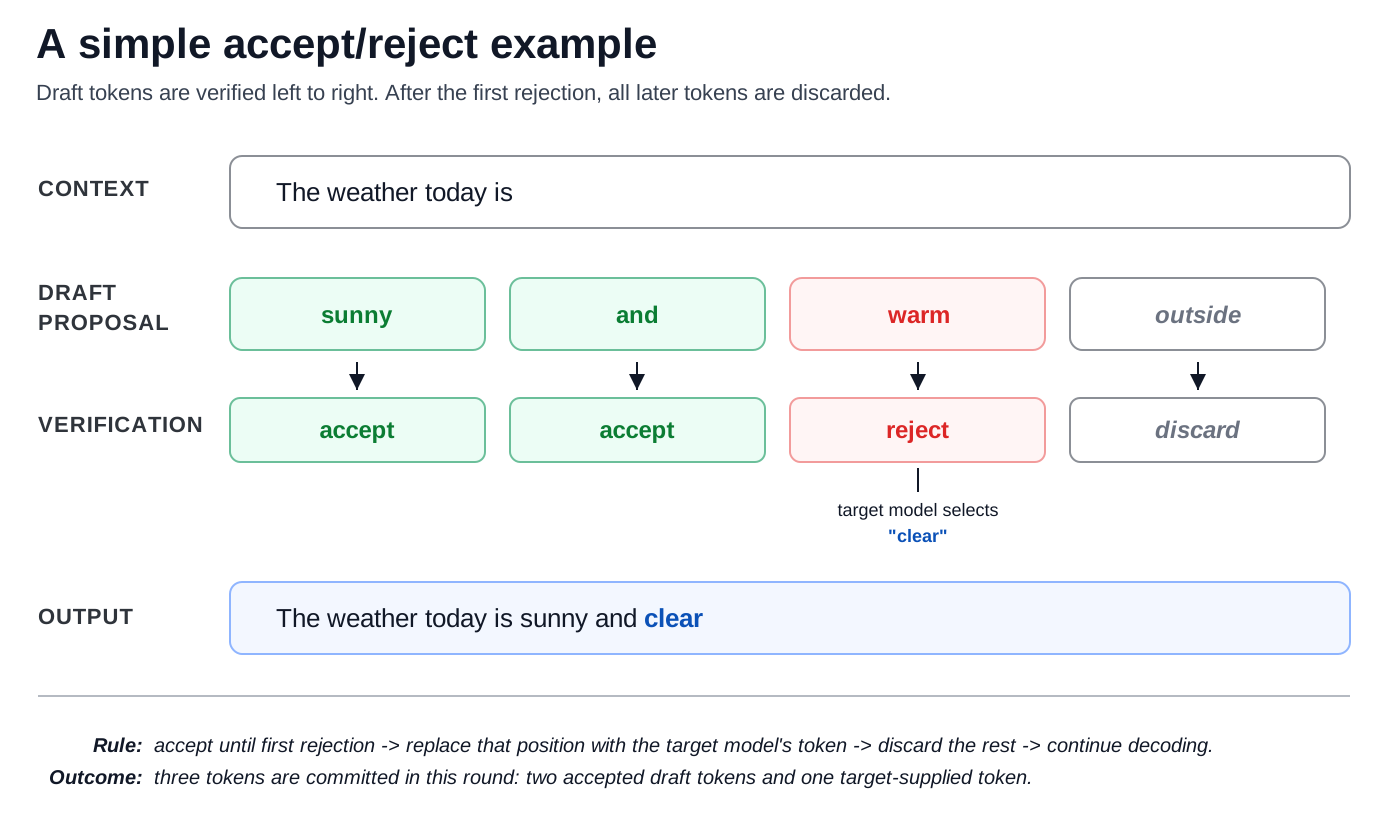
Figure 2. Left-to-right verification of a draft proposal. The first two draft tokens are accepted, the rejected position uses a target-model token, and the remaining candidate is discarded.
Suppose the current prompt is:
The draft component proposes several future tokens:
The target model verifies the draft tokens from left to right:
The first two draft tokens, sunny and and, are accepted. At the third position, the draft proposes warm, but the target model selects clear. The remaining candidate, outside, is discarded because it follows the first rejected position.
The next decoding round therefore continues from:
How the drafting methods work
Although all speculative decoding methods follow the same overall draft-and-verify process, they differ in how the draft component is designed and how it works with the target model.
The main differences are:
- The type of information received from the target model.
- How this information is incorporated into the drafting process.
- Whether candidate tokens are generated sequentially or in parallel.
Based on these differences, the drafting methods discussed in this post can be grouped into three broad categories: native MTP modules, separate MTP drafters, and dedicated target-conditioned draft networks.
- Native MTP modules: built directly into the target-model architecture; use a model-native auxiliary prediction path; generate candidate tokens sequentially.
- Separate MTP drafters: use a separate checkpoint paired with a specific target model; use target-model activations and shared KV-cache information during inference; generate candidate tokens sequentially.
- Dedicated target-conditioned draft networks: use separate speculator models trained for a specific target model, including EAGLE-3, DFlash, and DSpark. EAGLE-3 drafts autoregressively from target-model hidden states, DFlash drafts parallel blocks from target-model hidden states, and DSpark adds lightweight causal correction and confidence-based prefix selection.
These categories describe the draft component architecture, not the target-model family. A target model may support native MTP while also having separately trained EAGLE-3, DFlash, or DSpark draft models.
The draft component does not operate entirely on its own. Depending on the method, the draft component may receive:
- A hidden representation from the target model.
- Hidden states from several selected target layers.
- The target model's KV cache.
- Features produced by combining multiple target-model representations.
The following sections explain how each method uses this information and how it generates candidate tokens.
Native MTP
Multi-Token Prediction, or MTP, refers to a family of model-native mechanisms for predicting tokens beyond the immediate next token. In vLLM, native MTP is available when the target model includes a compatible auxiliary prediction component [2]. The exact MTP architecture varies across model families, but each implementation provides an auxiliary path for proposing future tokens.
At the first speculative step, the MTP component combines a hidden representation from the target model with information from the current token to predict the first draft token. At subsequent steps, the newly drafted token and the hidden state produced by the previous MTP step are used to predict the next candidate. After the configured number of candidates has been proposed, the target model evaluates them together in one verification pass.
First draft token
Subsequent draft tokens
Many native MTP implementations follow a similar pattern. A hidden representation from the target model or from the previous MTP prediction is combined with the embedding of a shifted input token or the latest drafted token:
The two inputs serve different purposes: (1) the hidden representation carries information about the preceding sequence; and (2) the token embedding identifies the latest token from which drafting continues. In common implementations, they are combined along the hidden dimension and transformed before entering the auxiliary prediction layer.
The number of physical MTP layers and the configured speculative length are separate concepts. When num_speculative_tokens exceeds the prediction depth directly provided by the checkpoint, vLLM can reuse the MTP path through additional forward passes. A larger value therefore proposes more candidates before verification, but also introduces more sequential drafting work.
Native MTP is closely tied to the target-model architecture. In many implementations, parts of the MTP path share components with the target model, which can keep the additional memory overhead relatively modest. However, generating multiple speculative tokens still requires sequential drafting before verification.
Gemma 4 MTP
Gemma 4 uses a separately packaged MTP draft component paired with a specific target model [3]. Although the draft component has its own checkpoint, it remains closely connected to the target model during inference.
The draft component uses activations produced by the target model and shares the target model's KV cache. This allows it to reuse contextual information that the target has already computed instead of processing the accepted prefix independently.
As with native MTP, the number of layers in the draft component is separate from the configured speculative length. When several candidate tokens are requested, the draft component generates them sequentially:
EAGLE-3
EAGLE-3 uses a dedicated draft network trained for a specific target model. The draft component has its own execution path, but it remains closely conditioned on information produced by the target model [4].
During the target-model forward pass, EAGLE-3 records hidden states from three stages of the target Transformer: near the beginning, around the middle, and near the end. These are contextual representations of the same accepted sequence at different stages of target-model processing.
The three hidden states are concatenated and projected into a single fused target feature. This fused representation is then combined with the embedding of the sampled token before entering the EAGLE-3 draft decoder.
The two inputs serve different purposes:
- The fused target feature summarizes the accepted sequence using information from several stages of the target-model forward pass.
- The sampled-token embedding identifies the token from which drafting continues.
EAGLE-3 generates draft tokens autoregressively. For the first draft token, it uses the fused target feature computed from the accepted sequence together with the sampled-token embedding. After a draft token is produced, its embedding is fed into the next drafting stage.
Because the target model has not yet processed the later speculative positions, target-model hidden states for those positions are not available. EAGLE-3 therefore uses the previous draft-component output when continuing the draft sequence.
First draft token
Subsequent draft tokens
This sequential feedback gives later draft tokens direct dependence on earlier drafted tokens along the proposed sequence. However, generating more speculative tokens also requires more sequential drafting work before verification.
DFlash
DFlash uses a dedicated draft network trained for a specific target model. Unlike MTP and EAGLE-3, which generate candidate tokens sequentially, DFlash predicts a whole block of future positions in parallel [5].
DFlash begins each draft block with an anchor token. The anchor is a known token produced or confirmed by the target model, so DFlash does not need to predict it. Instead, it provides a known starting point for the masked positions that follow. In later decoding rounds, this is typically the additional target token returned by the previous verification pass.
The anchor occupies the first position of the block, while the remaining positions are masked and predicted in parallel:
A draft block starts with a confirmed anchor token, followed by masked positions:
Here, anchor is the known target-model token, while the masked positions are predicted by DFlash.
A single DFlash forward pass predicts all masked positions together:
Like EAGLE-3, DFlash first combines hidden states from several target-model layers into a fused representation.
The main difference is how this fused representation is used. EAGLE-3 combines it with the sampled-token embedding at the input of its autoregressive draft network. DFlash instead converts the fused target context into additional Key and Value representations that are available in every layer of the draft network.
Queries from the masked draft positions can therefore attend to both:
- Key and Value representations derived from the target model.
- Key and Value representations produced from the draft block itself.
Available in every draft layer
The target-model context therefore remains available throughout the draft network, rather than being supplied only once at its input.
After the draft block has been generated, the target model evaluates all proposed tokens in one verification pass. The acceptance decision is then applied from left to right: accepted tokens are committed until the first rejection, and the remaining candidates are discarded.
Here, the target-model token replaces the first rejected draft token, while the remaining draft tokens are discarded.
A defining characteristic of DFlash is that all masked positions are predicted together in one draft-network forward pass.
This differs from sequential drafting:
Because all masked positions are predicted together, a later position is not conditioned on the sampled output of an earlier position during the same pass. This removes the token-by-token feedback used by autoregressive drafting. The effectiveness of later positions therefore depends on the trained checkpoint and workload, particularly when longer draft blocks are used.
DSpark
DSpark extends parallel drafting with two additional mechanisms:
- A lightweight sequential head that introduces dependence between tokens within the draft block.
- Confidence-based selection of the prefix submitted for target-model verification.
DSpark uses a modified DFlash model as its parallel backbone [6]. The backbone performs the main draft computation for all positions in one forward pass, producing a hidden state and a set of base logits for each draft position. It therefore inherits the target-context conditioning described in the DFlash section.
A fully parallel draft component predicts every position without first seeing the tokens selected at earlier positions in the same block. When several continuations are plausible, this can produce inconsistent combinations. For example, both "of course" and "no problem" may be reasonable continuations, but independent position-wise predictions could produce "of problem."
DSpark addresses this behavior by applying a lightweight sequential head after the parallel backbone. The backbone still computes the base logits for every position together. The sequential head then selects tokens from left to right, adjusting each position using information from the previously selected draft tokens.
DSpark applies a lightweight Markov head that introduces dependence between the selected draft tokens. For each position, the Markov head uses the immediately preceding selected token to produce a small bias. This bias adjusts the base logits produced by the parallel backbone:
The main draft network processes all candidate positions together in one forward pass. After that, only the lightweight Markov head runs from left to right to adjust each position using the previously selected draft token.
This allows later draft tokens to depend on tokens already selected within the same block without running the full draft network again for every position.
The DSpark design also includes a confidence head that can select a shorter draft prefix for target-model verification. This feature was not active in the vLLM path used for our experiments, so the benchmark results reflect only the parallel draft network and lightweight Markov correction.
The target model evaluates the proposed sequence in one verification pass, and draft tokens are committed from left to right until the first rejection.
Summary of the drafting methods
Figure 3 gives a visual side-by-side view of the five drafting methods: what the draft component looks like, which target-model information it uses, and whether candidate tokens are generated sequentially or in parallel. The table below the figure restates the same comparison in a compact form. In all five methods, the target model still evaluates the proposed sequence in one verification pass, and the acceptance decision is applied from left to right until the first rejected draft token.
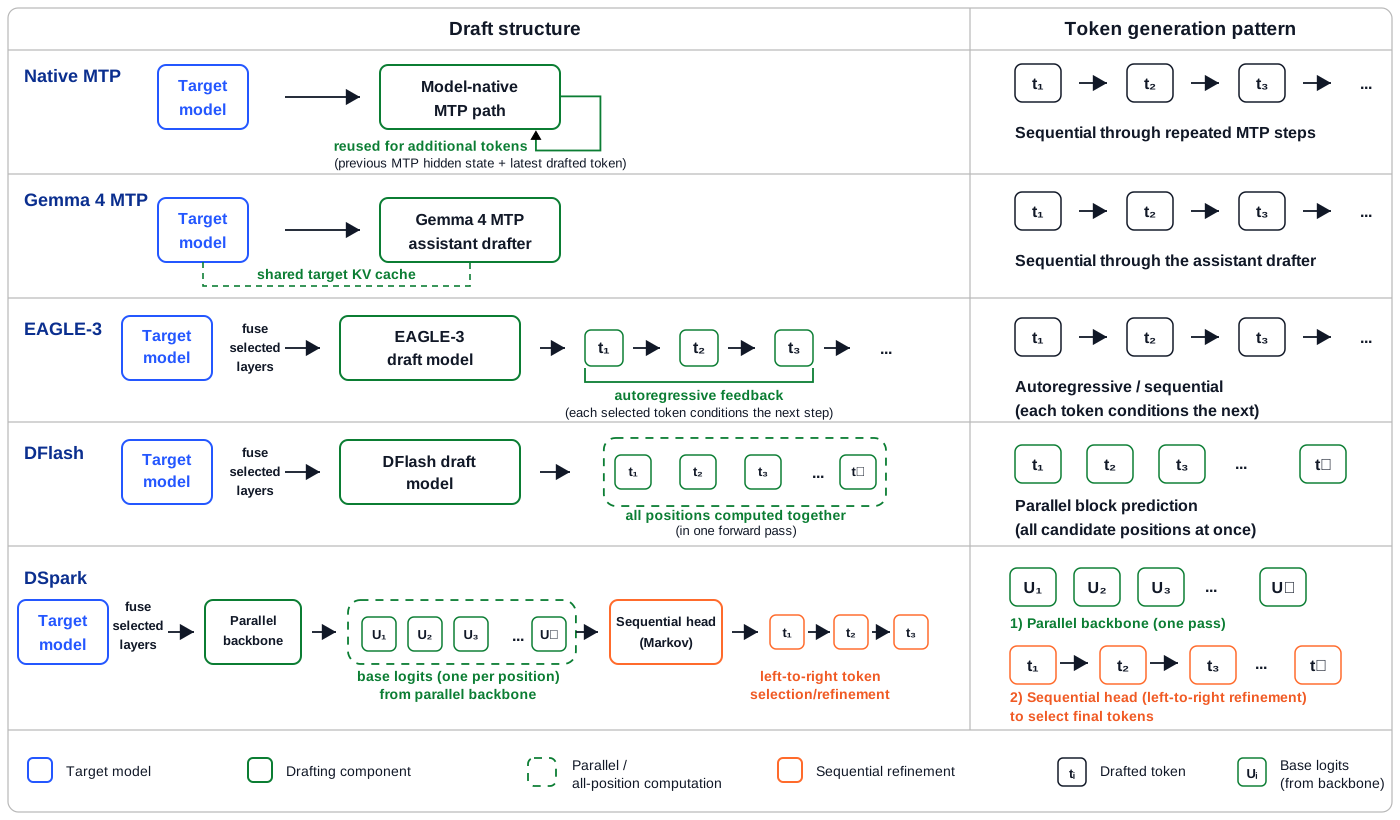
Figure 3. Draft structure and token generation patterns for the five speculative decoding methods discussed in this post.
| Method | Draft component | Target-model information used | How draft tokens are generated |
|---|---|---|---|
| Native MTP | Model-native auxiliary MTP path | A target-model or previous MTP hidden representation combined with current draft-token information | Sequentially through repeated use of the MTP path |
| Gemma 4 MTP | Separate MTP draft component paired with the target model | Target-model activations and the shared target KV cache | Sequentially through the paired MTP component |
| EAGLE-3 | Dedicated autoregressive draft network | Hidden states captured near the beginning, around the middle, and near the end of the target-model forward pass, fused into one representation | Sequentially, with each drafted token influencing the next |
| DFlash | Dedicated parallel draft network | Fused target-model hidden states provided as additional Key and Value information in every draft layer | All candidate positions are predicted together in one parallel forward pass |
| DSpark | DFlash-style parallel draft network with a lightweight Markov head | The same target-conditioned information used by the parallel draft network | One parallel forward pass followed by lightweight sequential adjustment of token selection |
How to enable speculative decoding in vLLM
In vLLM, speculative decoding is configured through --speculative-config. The main differences are the method name, whether a separate draft checkpoint is required, and the number of candidate tokens requested. Current vLLM supports mtp, eagle3, dflash, and dspark as method values.
| Method | Separate draft checkpoint | Typical configuration |
|---|---|---|
| Native MTP | No |
"method": "mtp""num_speculative_tokens": <N>
|
| Gemma 4 MTP | Yes |
"method": "mtp""model": "<matching-assistant>""num_speculative_tokens": <N>
|
| EAGLE-3 | Yes |
"method": "eagle3""model": "<matching-speculator>""num_speculative_tokens": <N>
|
| DFlash | Yes |
"method": "dflash""model": "<matching-speculator>""num_speculative_tokens": <N>
|
| DSpark | Yes |
"method": "dspark""model": "<matching-speculator>""num_speculative_tokens": <N>
|
For native MTP, the draft component is included with the target model, so the model field is omitted:
vllm serve <target-model> \
  --speculative-config '{
    "method": "mtp",
    "num_speculative_tokens": <N>
  }'
For Gemma 4 MTP, EAGLE-3, DFlash, and DSpark, the model field normally points to a checkpoint trained for the target model:
vllm serve <target-model> \
  --speculative-config '{
    "method": "<method>",
    "model": "<matching-draft-checkpoint>",
    "num_speculative_tokens": <N>
  }'
Gemma 4 assistant checkpoints use the MTP path even though they are supplied through the model field. vLLM connects the assistant component to the target model and allows it to share the target KV cache.
Before enabling a method, check that:
- The installed vLLM version supports the method and model architecture.
- The draft checkpoint is compatible with the target model and method.
num_speculative_tokensis compatible with the checkpoint.- The model card supports the intended hardware and inference backend.
Memory considerations
Native MTP does not load a separate draft checkpoint and may share components such as the embedding table or output head with the target model. Gemma 4 MTP, EAGLE-3, DFlash, and DSpark load additional draft weights, so sufficient GPU memory headroom should be reserved. The actual overhead depends on the draft-component size, numerical precision, tensor-parallel configuration, and runtime buffers.
Where to find the pretrained draft models
Several organizations now publish pretrained draft models on Hugging Face. Google provides MTP assistants for Gemma 4, while Z-Lab maintains a collection of DFlash checkpoints. Red Hat AI offers draft models across EAGLE-3, DFlash, and DSpark, and DeepSeek's DeepSpec collection provides matched checkpoints for all three methods. LightSeek focuses on EAGLE-based draft models for Kimi, while Inferact publishes draft models for MiniMax and Kimi.
| Draft-model publisher | Methods | Representative models and targets |
|---|---|---|
| Gemma 4 MTP | Assistant checkpoints for Gemma 4 E2B, E4B, 12B, 26B-A4B, and 31B target models. [7] | |
| LightSeek Foundation | EAGLE-3 and EAGLE-3.1 | EAGLE-based draft models for Kimi-K2.5, Kimi-K2.6, and Kimi-K2.7-Coder, including standard and MLA variants. [8] |
| Red Hat AI | EAGLE-3, DFlash, and DSpark | A collection covering target families such as Llama, Qwen, Gemma, GPT-OSS, GLM, Nemotron, and Mistral. Common suffixes include -speculator.eagle3, -speculator.dflash, and -speculator.dspark. [9] |
| Z-Lab | DFlash | DFlash checkpoints for targets including Qwen3, Qwen3.5, Qwen3.6, Gemma 4, Kimi, MiniMax, GPT-OSS, and Llama. Checkpoint names generally follow the <target>-DFlash pattern. [10] |
| DeepSeek AI | EAGLE-3, DFlash, and DSpark | The DeepSpec collection provides versions of all three methods for Qwen3-4B, Qwen3-8B, and Qwen3-14B, as well as Gemma 4 12B. Examples include eagle3_qwen3_8b_ttt7, dflash_qwen3_8b_block7, and dspark_qwen3_8b_block7. [11] |
| Inferact | EAGLE-3 and DSpark | Draft models including Inferact/MiniMax-M3-EAGLE3, its GQA variants, and Inferact/Kimi-K3-DSpark. [12] |
Experimental setup and measurements
After enabling speculative decoding, the practical question is whether the additional drafting work improves end-to-end serving performance. Candidate tokens do not need to be correct at every position because the target model evaluates them before they are committed. Performance therefore depends on how many proposed tokens are accepted and whether the saved target-model decoding work outweighs the cost of drafting and verification.
We evaluate model quality and serving performance using task-grounded benchmarks rather than random token sequences. Acceptance behavior depends on the structure and predictability of actual model outputs, so task-based prompts provide a more representative view of practical performance.
The main performance indicators are:
- Output-token throughput and speedup over the non-speculative baseline.
- Mean accepted length and draft-token acceptance rates, where available.
- Model quality relative to the non-speculative baseline.
Models and experiment coverage
The experiments cover five speculative-drafting approaches across several target-model families. A check mark indicates that benchmark results are available for that target-method combination; a dash indicates that the combination was not included in the current experiments.
| Target model | Native MTP | Gemma 4 MTP | EAGLE-3 | DFlash | DSpark |
|---|---|---|---|---|---|
| google/gemma-4-26B-A4B-it | - | ✓Red Hat AI | ✓Z-Lab | - | |
| google/gemma-4-31B-it | - | ✓Red Hat AI | ✓Z-Lab | ✓Red Hat AI | |
| Qwen/Qwen3-8B | - | - | ✓Red Hat AI | ✓Z-Lab | ✓DeepSeek |
| Qwen/Qwen3.5-27B | ✓Built-in | - | - | ✓Z-Lab | - |
| Qwen/Qwen3.5-122B-A10B | ✓Built-in | - | - | ✓Z-Lab | - |
| Qwen/Qwen3.6-27B | ✓Built-in | - | - | ✓Z-Lab | - |
| Qwen/Qwen3.6-35B-A3B | ✓Built-in | - | - | ✓Z-Lab | - |
| moonshotai/Kimi-K2.5 | - | - | ✓LightSeek | ✓Z-Lab | - |
| MiniMaxAI/MiniMax-M3-MXFP8 | - | - | ✓Inferact | - | - |
The table summarizes the target-method combinations included in the experiments and shows how speculative decoding behaves across different models, workloads, and proposal lengths. Each result should be interpreted within its test configuration, since model architecture, active parameter count, draft-component size, workload, and serving conditions can all affect performance.
Throughput measurements
For throughput, we measure generated tokens per second against a standard autoregressive baseline and sweep the number of speculative tokens to study how speculation depth affects end-to-end serving throughput.
Figure 4. Measured output throughput by method and experiment, with the non-speculative baseline included as a reference. Use the selector to switch target models; hover over bars to see speedup and selected proposal length N.
Main observations
The measurements varied by target model, drafting method, workload, and proposal length.
For gemma-4-26B-A4B-it, the largest measured throughput ratios within the tested sweep were 2.74× and 2.62× for Gemma 4 MTP on GSM8K and MBPP, respectively, and 2.87× and 2.79× for DFlash on MATH500 and HumanEval. The EAGLE-3 measurements ranged from 2.11× to 2.27× across the four datasets.
For gemma-4-31B-it, Gemma 4 MTP measurements reached 2.00× on GSM8K and 1.99× on MBPP, while DFlash reached 2.34× on MATH500 and 2.05× on HumanEval. The EAGLE-3 and DSpark measurements were also above baseline across the four evaluated datasets. The proposal length associated with the largest measured throughput varied by workload.
For Qwen3-8B, the DSpark measurements ranged from 1.15× on MATH500 to 1.63× on GSM8K. DFlash measurements ranged from 1.08× to 1.27×. EAGLE-3 was above baseline on GSM8K, HumanEval, and MBPP, while its largest measured MATH500 value remained below the baseline.
For Qwen3.5-27B, Qwen3.5-122B-A10B, and Qwen3.6-27B, the maximum measured native-MTP values within the tested sweeps were higher than the corresponding maximum DFlash values. The largest ratio in this group was 2.20× for Qwen3.5-122B-A10B on MATH500. The native-MTP proposal length associated with the largest measured throughput ranged from N=4 to N=7, depending on the model and dataset.
For Qwen3.6-35B-A3B, the DFlash measurements ranged from 1.77× to 2.06×, with the largest value occurring at N=7 for each of the four datasets. Native-MTP measurements ranged from 1.28× to 1.49×, with the largest values occurring at N=6. The difference from the Qwen3.6-27B measurements shows that results can vary between models in the same family.
For MiniMax-M3-MXFP8, the EAGLE-3 measurements reached 2.09× on HumanEval at N=4. For Kimi-K2.5, EAGLE-3 measurements reached up to 2.33× and DFlash measurements reached up to 2.68×. Within the tested sweeps, the largest EAGLE-3 values generally occurred at N=4, while the largest DFlash values occurred at N=7.
Across the experiments, the proposal length associated with the largest measured throughput was not constant. For the sequential methods, throughput often increased over the first few values of N before reaching a plateau. For DFlash and DSpark, N=7 was frequently among the higher-throughput settings, while larger values did not consistently increase throughput.
These observations reflect the hardware, software, target model, draft checkpoint, workload, and sweep settings used in this study.
Tuning considerations
Speculative decoding should be treated as a runtime optimization rather than a fixed setting that works equally well for every workload. The value of num_speculative_tokens associated with the highest throughput depends on how many proposed tokens are accepted and whether the avoided target-model decode work outweighs the cost of drafting and verification.
Observability is therefore important. A model-card recommendation or example configuration provides a useful starting point, but the final setting should be selected using representative workloads and end-to-end measurements. Useful signals include throughput, mean accepted length, overall acceptance rate, and per-position acceptance rate.
A larger proposal window gives the system more opportunities to commit several tokens in one verification pass. However, acceptance may decrease at later draft positions. When this happens, the additional candidates contribute little while still adding drafting and verification work, causing throughput to flatten or regress.
Start from a supported configuration
For native MTP, N=1 is a conservative starting point because it introduces the least additional sequential drafting work:
{"method": "mtp", "num_speculative_tokens": 1}
After confirming correctness and stability, sweep larger values such as 2, 3, 4, 5, 6, and 7.
In our measurements, the native-MTP setting associated with the largest measured throughput varied by target model and workload. For Qwen3.5-27B, the largest measured throughput occurred at N=5 for GSM8K and MATH500, N=4 for HumanEval and MBPP, and N=3 for MT-Bench. For Qwen3.5-122B-A10B, the largest measured throughput across the four listed reasoning and code datasets occurred at N=7.
The Qwen3.6 measurements also show that this setting can change between models in the same family. For Qwen3.6-27B, the largest measured values occurred at N=4 or N=5, while throughput for the tested Qwen3.6-35B-A3B configurations increased through N=6.
For Gemma 4 MTP and EAGLE-3, increasing N also adds sequential drafting work. A short sweep is therefore useful even when the checkpoint provides a recommended configuration. In our Gemma 4 and EAGLE-3 experiments, measured throughput generally increased over the first few values of N before reaching a plateau.
For DFlash, begin with the proposal lengths recommended or supported by the draft checkpoint. Many DFlash checkpoints are trained with a fixed block size. For example, when:
block_size = 16
the maximum proposal length is normally:
num_speculative_tokens = 15
because the first position is the confirmed anchor token and the remaining 15 positions are draft candidates.
This is the maximum supported proposal length, not necessarily the highest-throughput setting. In practice, it is useful to test smaller values such as:
N = 3, 7, 11, 15
Across our DFlash experiments, N=7 was frequently among the higher-throughput settings. For some workloads, the largest measured throughput occurred at N=11.
For DSpark, num_speculative_tokens sets the number of candidate tokens generated in each speculative round. In our vLLM experiments, the full configured proposal was submitted for target-model verification, so values such as N=3 and N=7 should be compared using end-to-end throughput.
Monitor acceptance behavior
Relevant signals to monitor include:
| Signal | What it shows |
|---|---|
| Throughput | How end-to-end serving performance changes relative to the non-speculative baseline |
| Mean accepted length | How many draft tokens are committed per speculative round on average |
| Overall acceptance rate | What proportion of proposed draft tokens are accepted |
| Per-position acceptance rate | Whether later positions in the proposal remain useful |
Per-position acceptance is particularly helpful when tuning proposal length. If the first few positions are accepted frequently but later positions contribute very little, reducing num_speculative_tokens may improve throughput by avoiding unnecessary draft work.
Acceptance metrics should be interpreted together with throughput. A method may show higher throughput relative to baseline even with a lower acceptance rate when draft generation is inexpensive. Conversely, a high acceptance rate does not necessarily correspond to higher throughput when the draft component adds additional overhead.
Match the sweep to the workload
Different workloads can produce different acceptance patterns.
In our GSM8K and MATH500 measurements, medium or deeper proposal lengths were often associated with higher measured throughput within the tested sweeps. For native MTP on Qwen3.5-122B-A10B, measured throughput increased through N=7. For DFlash, higher measured values frequently occurred at N=7 or N=11.
For HumanEval and MBPP, moderate proposal lengths were often among the higher-throughput settings. Code contains predictable local structure, but formatting, identifiers, and implementation choices can cause an otherwise plausible continuation to diverge.
Example tuning workflow
-
Begin with a configuration supported or recommended for the checkpoint.
-
Benchmark using representative prompts and generation settings.
-
Record throughput, mean accepted length, and acceptance rates.
-
Sweep several smaller and larger proposal lengths.
-
Select a setting based on the metric most relevant to the intended workload. In these experiments, end-to-end serving throughput was the primary selection metric.
The selected configuration does not necessarily have the longest proposal, the highest acceptance rate, or the largest mean accepted length. Selection should consider the trade-off among drafting cost, verification cost, accepted tokens, and the metric most relevant to the intended workload.
Training a speculator for a new target model
This guide does not cover speculator training in depth. The following workflow summarizes practical considerations from the referenced vLLM Speculators and DeepSpec resources [13], [14], and [15].
A typical workflow is:
- Prepare representative prompts.
- Generate responses with the target model.
- Choose a hidden-state generation mode.
- Collect the required target-model hidden states.
- Train the speculator.
- Test acceptance and serving throughput.
Prepare representative prompts
Start with prompts that reflect the expected workload, such as chat, mathematics, code generation, tool use, or multilingual tasks. Keep a separate set of prompts for evaluation.
The responses used for training should be generated by the exact target model that the speculator will support. The tokenizer, chat template, thinking mode, and generation configuration should also match the intended deployment. The vLLM documentation emphasizes that applying the target model's tokenizer or chat template to existing responses does not make the data target-specific; the responses themselves must come from the target model.
Choose how to obtain hidden states
The speculator receives internal hidden states from the target model during training. The vLLM Speculators workflow supports three ways to provide them:
| Training mode | How it works | Main consideration |
|---|---|---|
| Online | Hidden states are generated by a running vLLM server when needed and discarded afterward | Avoids a large disk cache but requires resources for target inference and training at the same time |
| Offline | Hidden states are generated and stored before training begins | Frees all GPUs for training afterward but requires substantial storage |
| Hybrid | Hidden states are generated and cached during the first epoch, then reused | Pays the generation cost once without requiring a separate preprocessing stage |
The selected mode changes where the hidden states come from; the remaining training workflow is largely the same.
Collect target-model information
A vLLM server can run the target model and expose hidden states from the layers required by the selected drafting method. When custom target layers are chosen, the same layer selections must also be used in the speculator-training configuration.
The information collected depends on the method:
- EAGLE-3 uses hidden states from selected target-model layers for autoregressive drafting. [4]
- DFlash uses target-model features to train a network that predicts a block of future positions in parallel. [16]
- DSpark adds lightweight sequential and confidence heads to a DFlash-style draft network. [6]
- MTP training fine-tunes the target model's own MTP component and therefore requires a target model that already contains compatible MTP layers. [13]
Train and test the speculator
The speculator configuration must match the target model's hidden size, vocabulary, tokenizer, and selected target layers. Method-specific settings such as draft-network depth, block size, sequence length, and learning rate must also be selected.
After training, inspect the checkpoint and serve it together with the target model in vLLM. Training loss alone is not enough to judge the result; the important measurements are accepted length, acceptance rate, draft latency, GPU memory use, and end-to-end serving throughput. The vLLM Speculators tutorial covers the complete path from data preparation and hidden-state extraction to checkpoint testing and serving.
When acceptance is weak for a particular workload, the prompt mixture or training configuration can be adjusted and the process repeated. The main principle is to use the same target model, generation mode, and representative workload that the speculator is expected to support.
Summary
This blog explored speculative decoding in vLLM as a draft-and-verify approach for LLM serving. A draft component proposes candidate future tokens, and the target model evaluates the proposal before any tokens are committed.
We examined five drafting approaches: native MTP, Gemma 4 MTP, EAGLE-3, DFlash, and DSpark. They differ mainly in how they use information from the target model and whether candidate tokens are generated sequentially, in parallel, or through a combination of parallel prediction and lightweight sequential correction.
The experiments covered selected Gemma, Qwen, MiniMax, and Kimi models on AMD Instinct™ MI300X and MI355X GPUs using the ROCm™ software platform. Measured throughput varied across target models, draft checkpoints, workloads, proposal lengths, and serving configurations.
Across the tested configurations, some settings produced smaller changes or throughput below the non-speculative baseline, while several model-workload combinations produced throughput ratios above 2×. Examples at the upper end of the observed range included 2.87× for DFlash on gemma-4-26B-A4B-it, 2.83× for Gemma 4 MTP on the same target, and 2.68× for DFlash on Kimi-K2.5.
Proposal length was also an important experimental variable. Increasing num_speculative_tokens sometimes increased throughput over the first few settings, while larger values could lead to a plateau or lower throughput. Checkpoint recommendations can provide starting points, but representative workload measurements and acceptance metrics are needed when selecting a deployment configuration.
Future work
Future benchmarking could include non-learned approaches such as n-gram speculation and suffix decoding, particularly for workloads with repeated token patterns such as code editing and agentic loops.
Broader evaluation across concurrency levels, prompt and output lengths, batch sizes, and sampling settings would also help show how speculative decoding behaves under different serving conditions.
Another useful direction is to study how speculator training data affects acceptance across code, mathematics, chat, multilingual prompts, tool use, and structured output. This could provide clearer guidance when choosing or training a draft checkpoint for a specific workload.
Finally, deeper profiling of draft generation, target verification, KV-cache behavior, graph execution, and scheduling would help explain the performance differences observed across target models and workloads.
References
- vLLM documentation, "Speculative Decoding" https://docs.vllm.ai/en/latest/features/speculative_decoding/
- vLLM documentation, "MTP Speculative Decoding" https://docs.vllm.ai/en/latest/features/speculative_decoding/mtp/
- Google Developers Blog, "Multi-token prediction in Gemma 4" https://blog.google/innovation-and-ai/technology/developers-tools/multi-token-prediction-gemma-4/
- EAGLE-3 paper, "Scaling up Inference Acceleration of Large Language Models via Training-Time Test" https://arxiv.org/pdf/2503.01840
- Z-Lab, "DFlash" GitHub repository https://github.com/z-lab/dflash
- DSpark paper, arXiv preprint https://arxiv.org/pdf/2607.05147
- Google, "Gemma 4" Hugging Face collection https://huggingface.co/collections/google/gemma-4
- LightSeek Foundation model collection on Hugging Face https://huggingface.co/lightseekorg/models
- Red Hat AI, "Speculator Models" Hugging Face collection https://huggingface.co/collections/RedHatAI/speculator-models
- Z-Lab, "DFlash" Hugging Face collection https://huggingface.co/collections/z-lab/dflash
- DeepSeek-AI, "DeepSpec" Hugging Face collection https://huggingface.co/collections/deepseek-ai/deepspec
- Inferact model collection on Hugging Face https://huggingface.co/Inferact/models
- vLLM Speculators documentation, "Training a Speculator" https://docs.vllm.ai/projects/speculators/en/latest/user_guide/tutorials/train/
- vLLM Project, "Speculators" GitHub repository https://github.com/vllm-project/speculators
- DeepSeek-AI, "DeepSpec" GitHub repository https://github.com/deepseek-ai/DeepSpec
- DFlash paper, arXiv preprint https://arxiv.org/pdf/2602.06036
Appendix
The appendix focuses on acceptance behavior by draft position. Choose a target model, drafting method, and experiment to view one larger per-position acceptance heatmap. Rows are proposal lengths N; columns are draft positions; darker cells indicate higher acceptance. Each row also includes measured speedup and output throughput for context.
google/gemma-4-26B-A4B-it / Gemma 4 MTP / GSM8K
GSM8K baseline 2,344 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.73x | 4,060 tok/sMAL 1.95 | AR 94.8% | 95% | ||||
| N=2 2.28x | 5,334 tok/sMAL 2.83 | AR 91.4% | 95% | 88% | |||
| N=3 2.54x | 5,945 tok/sMAL 3.64 | AR 87.9% | 94% | 88% | 81% | ||
| N=4 2.66x | 6,230 tok/sMAL 4.35 | AR 83.8% | 94% | 87% | 80% | 74% | |
| N=5 2.74x | 6,434 tok/sMAL 5.00 | AR 80.0% | 94% | 87% | 80% | 73% | 66% |
google/gemma-4-26B-A4B-it / Gemma 4 MTP / MATH500
MATH500 baseline 2,181 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.68x | 3,671 tok/sMAL 1.95 | AR 95.1% | 95% | ||||
| N=2 2.27x | 4,961 tok/sMAL 2.84 | AR 91.8% | 95% | 89% | |||
| N=3 2.53x | 5,510 tok/sMAL 3.64 | AR 88.2% | 95% | 88% | 82% | ||
| N=4 2.73x | 5,955 tok/sMAL 4.36 | AR 84.1% | 94% | 88% | 81% | 74% | |
| N=5 2.83x | 6,161 tok/sMAL 5.01 | AR 80.2% | 94% | 87% | 80% | 73% | 66% |
google/gemma-4-26B-A4B-it / Gemma 4 MTP / HumanEval
HumanEval baseline 1,854 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.78x | 3,310 tok/sMAL 1.94 | AR 93.8% | 94% | ||||
| N=2 2.09x | 3,871 tok/sMAL 2.79 | AR 89.7% | 93% | 86% | |||
| N=3 2.33x | 4,326 tok/sMAL 3.56 | AR 85.4% | 93% | 85% | 78% | ||
| N=4 2.50x | 4,642 tok/sMAL 4.24 | AR 81.1% | 93% | 85% | 77% | 70% | |
| N=5 2.59x | 4,810 tok/sMAL 4.81 | AR 76.3% | 92% | 84% | 76% | 69% | 62% |
google/gemma-4-26B-A4B-it / Gemma 4 MTP / MBPP
MBPP baseline 2,163 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.73x | 3,744 tok/sMAL 1.90 | AR 90.5% | 91% | ||||
| N=2 2.26x | 4,882 tok/sMAL 2.70 | AR 84.8% | 90% | 80% | |||
| N=3 2.50x | 5,413 tok/sMAL 3.38 | AR 79.2% | 90% | 79% | 69% | ||
| N=4 2.60x | 5,628 tok/sMAL 3.93 | AR 73.3% | 89% | 78% | 68% | 58% | |
| N=5 2.62x | 5,662 tok/sMAL 4.37 | AR 67.4% | 89% | 77% | 66% | 57% | 49% |
google/gemma-4-26B-A4B-it / EAGLE-3 / GSM8K
GSM8K baseline 2,344 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.55x | 3,624 tok/sMAL 1.83 | AR 83.0% | 83% | ||||
| N=2 2.09x | 4,888 tok/sMAL 2.47 | AR 73.7% | 82% | 65% | |||
| N=3 2.16x | 5,063 tok/sMAL 2.94 | AR 64.7% | 81% | 64% | 49% | ||
| N=4 2.16x | 5,059 tok/sMAL 3.27 | AR 56.7% | 80% | 63% | 48% | 35% | |
| N=5 2.15x | 5,040 tok/sMAL 3.49 | AR 49.7% | 80% | 63% | 47% | 35% | 24% |
google/gemma-4-26B-A4B-it / EAGLE-3 / MATH500
MATH500 baseline 2,181 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.54x | 3,362 tok/sMAL 1.87 | AR 87.2% | 87% | ||||
| N=2 2.07x | 4,516 tok/sMAL 2.57 | AR 78.3% | 86% | 71% | |||
| N=3 2.21x | 4,810 tok/sMAL 3.09 | AR 69.7% | 85% | 69% | 55% | ||
| N=4 2.27x | 4,953 tok/sMAL 3.47 | AR 61.7% | 85% | 68% | 54% | 40% | |
| N=5 2.23x | 4,861 tok/sMAL 3.73 | AR 54.6% | 84% | 68% | 53% | 40% | 29% |
google/gemma-4-26B-A4B-it / EAGLE-3 / HumanEval
HumanEval baseline 1,854 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.51x | 2,802 tok/sMAL 1.80 | AR 79.9% | 80% | ||||
| N=2 1.85x | 3,438 tok/sMAL 2.40 | AR 69.9% | 79% | 61% | |||
| N=3 1.92x | 3,562 tok/sMAL 2.81 | AR 60.3% | 78% | 60% | 44% | ||
| N=4 2.16x | 3,997 tok/sMAL 3.07 | AR 51.7% | 77% | 59% | 42% | 30% | |
| N=5 1.85x | 3,435 tok/sMAL 3.22 | AR 44.4% | 76% | 57% | 41% | 28% | 20% |
google/gemma-4-26B-A4B-it / EAGLE-3 / MBPP
MBPP baseline 2,163 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.54x | 3,328 tok/sMAL 1.79 | AR 79.0% | 79% | ||||
| N=2 2.08x | 4,506 tok/sMAL 2.36 | AR 68.1% | 78% | 58% | |||
| N=3 2.11x | 4,559 tok/sMAL 2.75 | AR 58.3% | 77% | 57% | 42% | ||
| N=4 2.11x | 4,574 tok/sMAL 3.00 | AR 50.0% | 76% | 56% | 40% | 28% | |
| N=5 2.05x | 4,426 tok/sMAL 3.17 | AR 43.3% | 75% | 55% | 39% | 28% | 20% |
google/gemma-4-26B-A4B-it / DFlash / GSM8K
GSM8K baseline 2,344 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 2.43x | 5,697 tok/sMAL 3.36 | AR 78.8% | 90% | 79% | 68% | ||||||||||||
| N=7 2.70x | 6,327 tok/sMAL 5.05 | AR 57.9% | 88% | 76% | 65% | 56% | 48% | 40% | 33% | ||||||||
| N=11 2.44x | 5,724 tok/sMAL 5.71 | AR 42.8% | 87% | 74% | 63% | 54% | 45% | 38% | 31% | 26% | 22% | 17% | 14% | ||||
| N=15 2.12x | 4,973 tok/sMAL 5.89 | AR 32.6% | 86% | 73% | 62% | 53% | 44% | 37% | 30% | 25% | 20% | 17% | 13% | 10% | 8% | 6% | 4% |
google/gemma-4-26B-A4B-it / DFlash / MATH500
MATH500 baseline 2,181 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 2.49x | 5,427 tok/sMAL 3.43 | AR 80.9% | 91% | 81% | 71% | ||||||||||||
| N=7 2.87x | 6,267 tok/sMAL 5.26 | AR 60.9% | 88% | 77% | 67% | 59% | 52% | 45% | 39% | ||||||||
| N=11 2.70x | 5,888 tok/sMAL 6.09 | AR 46.3% | 87% | 75% | 65% | 56% | 49% | 42% | 37% | 32% | 27% | 23% | 19% | ||||
| N=15 2.40x | 5,232 tok/sMAL 6.40 | AR 36.0% | 86% | 74% | 63% | 55% | 47% | 41% | 35% | 30% | 26% | 22% | 18% | 15% | 12% | 10% | 7% |
google/gemma-4-26B-A4B-it / DFlash / HumanEval
HumanEval baseline 1,854 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 2.29x | 4,238 tok/sMAL 3.29 | AR 76.3% | 88% | 76% | 66% | ||||||||||||
| N=7 2.79x | 5,183 tok/sMAL 4.90 | AR 55.7% | 85% | 71% | 61% | 53% | 46% | 40% | 35% | ||||||||
| N=11 2.41x | 4,465 tok/sMAL 5.50 | AR 40.9% | 83% | 69% | 57% | 49% | 42% | 36% | 31% | 26% | 23% | 19% | 16% | ||||
| N=15 2.26x | 4,193 tok/sMAL 5.76 | AR 31.8% | 82% | 68% | 57% | 48% | 41% | 35% | 30% | 26% | 22% | 18% | 15% | 13% | 10% | 8% | 6% |
google/gemma-4-26B-A4B-it / DFlash / MBPP
MBPP baseline 2,163 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 2.34x | 5,065 tok/sMAL 3.08 | AR 69.4% | 84% | 69% | 56% | ||||||||||||
| N=7 2.41x | 5,214 tok/sMAL 4.22 | AR 45.9% | 80% | 64% | 52% | 42% | 34% | 27% | 22% | ||||||||
| N=11 2.14x | 4,621 tok/sMAL 4.56 | AR 32.4% | 79% | 62% | 49% | 39% | 32% | 26% | 21% | 17% | 14% | 11% | 8% | ||||
| N=15 1.86x | 4,018 tok/sMAL 4.69 | AR 24.6% | 79% | 62% | 49% | 38% | 31% | 25% | 20% | 16% | 13% | 10% | 8% | 6% | 5% | 4% | 3% |
google/gemma-4-31B-it / Gemma 4 MTP / GSM8K
GSM8K baseline 1,631 tok/s
| N | p1 | p2 | p3 | p4 |
|---|---|---|---|---|
| N=1 1.52x | 2,475 tok/sMAL 1.95 | AR 95.4% | 95% | |||
| N=2 1.78x | 2,906 tok/sMAL 2.85 | AR 92.3% | 95% | 89% | ||
| N=3 1.94x | 3,160 tok/sMAL 3.66 | AR 88.7% | 95% | 89% | 82% | |
| N=4 2.00x | 3,267 tok/sMAL 4.40 | AR 84.9% | 95% | 88% | 82% | 75% |
google/gemma-4-31B-it / Gemma 4 MTP / MATH500
MATH500 baseline 1,365 tok/s
| N | p1 | p2 | p3 | p4 |
|---|---|---|---|---|
| N=1 1.54x | 2,097 tok/sMAL 1.96 | AR 95.6% | 96% | |||
| N=2 1.86x | 2,542 tok/sMAL 2.85 | AR 92.5% | 95% | 90% | ||
| N=3 2.09x | 2,851 tok/sMAL 3.67 | AR 88.9% | 95% | 89% | 83% | |
| N=4 2.20x | 3,006 tok/sMAL 4.41 | AR 85.2% | 95% | 88% | 82% | 75% |
google/gemma-4-31B-it / Gemma 4 MTP / HumanEval
HumanEval baseline 1,228 tok/s
| N | p1 | p2 | p3 | p4 |
|---|---|---|---|---|
| N=1 1.46x | 1,793 tok/sMAL 1.96 | AR 95.8% | 96% | |||
| N=2 1.76x | 2,163 tok/sMAL 2.86 | AR 92.8% | 95% | 90% | ||
| N=3 1.97x | 2,419 tok/sMAL 3.70 | AR 90.0% | 95% | 90% | 85% | |
| N=4 1.97x | 2,424 tok/sMAL 4.43 | AR 85.7% | 95% | 88% | 83% | 77% |
google/gemma-4-31B-it / Gemma 4 MTP / MBPP
MBPP baseline 1,519 tok/s
| N | p1 | p2 | p3 | p4 |
|---|---|---|---|---|
| N=1 1.55x | 2,360 tok/sMAL 1.91 | AR 91.2% | 91% | |||
| N=2 1.81x | 2,743 tok/sMAL 2.72 | AR 85.9% | 91% | 81% | ||
| N=3 1.97x | 2,997 tok/sMAL 3.39 | AR 79.7% | 90% | 79% | 70% | |
| N=4 1.99x | 3,020 tok/sMAL 3.95 | AR 73.7% | 90% | 79% | 68% | 59% |
google/gemma-4-31B-it / EAGLE-3 / GSM8K
GSM8K baseline 1,631 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.48x | 2,420 tok/sMAL 1.88 | AR 87.5% | 88% | ||||
| N=2 1.69x | 2,756 tok/sMAL 2.60 | AR 80.0% | 87% | 73% | |||
| N=3 1.79x | 2,915 tok/sMAL 3.18 | AR 72.7% | 86% | 72% | 60% | ||
| N=4 1.77x | 2,883 tok/sMAL 3.63 | AR 65.8% | 85% | 71% | 59% | 48% | |
| N=5 1.79x | 2,913 tok/sMAL 3.99 | AR 59.7% | 85% | 71% | 59% | 47% | 37% |
google/gemma-4-31B-it / EAGLE-3 / MATH500
MATH500 baseline 1,365 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.54x | 2,106 tok/sMAL 1.91 | AR 90.7% | 91% | ||||
| N=2 1.85x | 2,521 tok/sMAL 2.69 | AR 84.4% | 90% | 79% | |||
| N=3 2.05x | 2,796 tok/sMAL 3.33 | AR 77.8% | 89% | 78% | 66% | ||
| N=4 2.03x | 2,768 tok/sMAL 3.84 | AR 71.1% | 89% | 77% | 65% | 54% | |
| N=5 2.12x | 2,891 tok/sMAL 4.24 | AR 64.8% | 88% | 76% | 64% | 53% | 43% |
google/gemma-4-31B-it / EAGLE-3 / HumanEval
HumanEval baseline 1,228 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.43x | 1,757 tok/sMAL 1.87 | AR 87.4% | 87% | ||||
| N=2 1.68x | 2,059 tok/sMAL 2.60 | AR 79.8% | 86% | 73% | |||
| N=3 1.81x | 2,221 tok/sMAL 3.19 | AR 72.9% | 86% | 73% | 60% | ||
| N=4 1.80x | 2,209 tok/sMAL 3.64 | AR 66.0% | 85% | 72% | 59% | 48% | |
| N=5 1.86x | 2,278 tok/sMAL 3.97 | AR 59.4% | 85% | 71% | 58% | 46% | 37% |
google/gemma-4-31B-it / EAGLE-3 / MBPP
MBPP baseline 1,519 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.52x | 2,306 tok/sMAL 1.85 | AR 84.7% | 85% | ||||
| N=2 1.73x | 2,626 tok/sMAL 2.52 | AR 75.8% | 84% | 68% | |||
| N=3 1.84x | 2,793 tok/sMAL 3.03 | AR 67.6% | 83% | 67% | 54% | ||
| N=4 1.80x | 2,736 tok/sMAL 3.41 | AR 60.2% | 82% | 66% | 52% | 41% | |
| N=5 1.80x | 2,730 tok/sMAL 3.67 | AR 53.3% | 81% | 65% | 51% | 40% | 30% |
google/gemma-4-31B-it / DFlash / GSM8K
GSM8K baseline 1,631 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.85x | 3,012 tok/sMAL 3.51 | AR 83.7% | 93% | 84% | 74% | ||||||||||||
| N=7 1.95x | 3,183 tok/sMAL 5.54 | AR 64.8% | 92% | 82% | 72% | 64% | 55% | 48% | 41% | ||||||||
| N=11 1.76x | 2,877 tok/sMAL 6.47 | AR 49.7% | 91% | 80% | 70% | 61% | 53% | 46% | 39% | 33% | 28% | 24% | 20% | ||||
| N=15 1.53x | 2,489 tok/sMAL 6.84 | AR 38.9% | 91% | 80% | 70% | 60% | 52% | 44% | 37% | 32% | 27% | 23% | 19% | 16% | 13% | 11% | 9% |
google/gemma-4-31B-it / DFlash / MATH500
MATH500 baseline 1,365 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 2.03x | 2,770 tok/sMAL 3.56 | AR 85.5% | 94% | 86% | 77% | ||||||||||||
| N=7 2.34x | 3,197 tok/sMAL 5.76 | AR 68.0% | 93% | 83% | 74% | 67% | 59% | 53% | 47% | ||||||||
| N=11 2.15x | 2,934 tok/sMAL 6.88 | AR 53.4% | 92% | 82% | 72% | 64% | 56% | 50% | 44% | 39% | 34% | 30% | 26% | ||||
| N=15 1.91x | 2,605 tok/sMAL 7.39 | AR 42.6% | 91% | 81% | 71% | 62% | 55% | 48% | 42% | 37% | 33% | 28% | 25% | 21% | 18% | 15% | 12% |
google/gemma-4-31B-it / DFlash / HumanEval
HumanEval baseline 1,228 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.88x | 2,309 tok/sMAL 3.60 | AR 86.8% | 94% | 87% | 79% | ||||||||||||
| N=7 2.02x | 2,482 tok/sMAL 5.82 | AR 68.9% | 92% | 83% | 75% | 67% | 61% | 55% | 49% | ||||||||
| N=11 2.05x | 2,514 tok/sMAL 7.00 | AR 54.5% | 92% | 82% | 72% | 64% | 57% | 51% | 46% | 41% | 36% | 32% | 28% | ||||
| N=15 1.85x | 2,274 tok/sMAL 7.51 | AR 43.4% | 91% | 80% | 70% | 62% | 55% | 49% | 44% | 39% | 35% | 30% | 26% | 23% | 19% | 16% | 13% |
google/gemma-4-31B-it / DFlash / MBPP
MBPP baseline 1,519 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.89x | 2,873 tok/sMAL 3.31 | AR 77.1% | 90% | 77% | 65% | ||||||||||||
| N=7 1.92x | 2,914 tok/sMAL 4.82 | AR 54.5% | 88% | 73% | 61% | 51% | 43% | 36% | 30% | ||||||||
| N=11 1.65x | 2,512 tok/sMAL 5.38 | AR 39.8% | 87% | 72% | 59% | 48% | 40% | 33% | 28% | 23% | 19% | 16% | 13% | ||||
| N=15 1.40x | 2,127 tok/sMAL 5.56 | AR 30.4% | 87% | 71% | 57% | 47% | 39% | 32% | 26% | 22% | 18% | 15% | 12% | 10% | 8% | 7% | 5% |
google/gemma-4-31B-it / DSpark / GSM8K
GSM8K baseline 1,631 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.62x | 2,635 tok/sMAL 3.33 | AR 77.7% | 88% | 78% | 68% | ||||||||||||
| N=7 1.82x | 2,971 tok/sMAL 5.07 | AR 58.1% | 88% | 77% | 67% | 57% | 47% | 39% | 33% | ||||||||
| N=11 1.52x | 2,484 tok/sMAL 5.51 | AR 41.0% | 85% | 74% | 63% | 54% | 44% | 37% | 30% | 24% | 18% | 13% | 9% | ||||
| N=15 1.32x | 2,155 tok/sMAL 5.69 | AR 31.3% | 86% | 75% | 65% | 54% | 45% | 37% | 30% | 25% | 19% | 13% | 9% | 5% | 3% | 2% | 1% |
google/gemma-4-31B-it / DSpark / MATH500
MATH500 baseline 1,365 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.98x | 2,703 tok/sMAL 3.45 | AR 81.7% | 91% | 82% | 73% | ||||||||||||
| N=7 2.20x | 3,004 tok/sMAL 5.30 | AR 61.4% | 89% | 78% | 69% | 60% | 52% | 44% | 38% | ||||||||
| N=11 1.91x | 2,612 tok/sMAL 5.96 | AR 45.1% | 89% | 77% | 67% | 58% | 50% | 42% | 36% | 29% | 22% | 16% | 11% | ||||
| N=15 1.61x | 2,197 tok/sMAL 6.05 | AR 33.7% | 88% | 77% | 67% | 57% | 50% | 42% | 35% | 28% | 22% | 16% | 10% | 7% | 4% | 2% | 1% |
google/gemma-4-31B-it / DSpark / HumanEval
HumanEval baseline 1,228 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.34x | 1,648 tok/sMAL 3.36 | AR 78.7% | 89% | 79% | 68% | ||||||||||||
| N=7 1.98x | 2,425 tok/sMAL 5.05 | AR 57.8% | 88% | 77% | 66% | 56% | 47% | 39% | 31% | ||||||||
| N=11 1.73x | 2,121 tok/sMAL 5.47 | AR 40.6% | 87% | 76% | 64% | 54% | 45% | 37% | 30% | 22% | 16% | 10% | 6% | ||||
| N=15 1.47x | 1,811 tok/sMAL 5.55 | AR 30.3% | 88% | 76% | 65% | 54% | 46% | 38% | 30% | 22% | 16% | 10% | 6% | 3% | 2% | 1% | 1% |
google/gemma-4-31B-it / DSpark / MBPP
MBPP baseline 1,519 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.84x | 2,797 tok/sMAL 3.17 | AR 72.4% | 86% | 72% | 60% | ||||||||||||
| N=7 1.80x | 2,730 tok/sMAL 4.41 | AR 48.7% | 84% | 69% | 55% | 45% | 36% | 29% | 23% | ||||||||
| N=11 1.50x | 2,272 tok/sMAL 4.74 | AR 34.0% | 83% | 67% | 54% | 44% | 35% | 28% | 22% | 17% | 12% | 8% | 5% | ||||
| N=15 1.23x | 1,876 tok/sMAL 4.77 | AR 25.2% | 83% | 67% | 54% | 43% | 35% | 28% | 22% | 16% | 12% | 8% | 5% | 3% | 1% | 1% | 0% |
Qwen/Qwen3-8B / EAGLE-3 / GSM8K
GSM8K baseline 3,698 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 0.71x | 2,634 tok/sMAL 1.86 | AR 86.3% | 86% | ||||||
| N=2 0.91x | 3,349 tok/sMAL 2.57 | AR 78.3% | 86% | 71% | |||||
| N=3 0.99x | 3,645 tok/sMAL 3.12 | AR 70.6% | 85% | 70% | 57% | ||||
| N=4 1.10x | 4,079 tok/sMAL 3.54 | AR 63.5% | 84% | 69% | 56% | 45% | |||
| N=5 1.18x | 4,347 tok/sMAL 3.86 | AR 57.3% | 84% | 68% | 56% | 44% | 35% | ||
| N=6 1.17x | 4,322 tok/sMAL 4.09 | AR 51.5% | 84% | 68% | 55% | 43% | 34% | 26% | |
| N=7 1.17x | 4,327 tok/sMAL 4.25 | AR 46.5% | 83% | 67% | 54% | 43% | 34% | 26% | 19% |
Qwen/Qwen3-8B / EAGLE-3 / MATH500
MATH500 baseline 3,530 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 0.44x | 1,563 tok/sMAL 1.89 | AR 89.0% | 89% | ||||||
| N=2 0.61x | 2,141 tok/sMAL 2.64 | AR 82.2% | 88% | 76% | |||||
| N=3 0.72x | 2,527 tok/sMAL 3.27 | AR 75.6% | 88% | 75% | 64% | ||||
| N=4 0.78x | 2,753 tok/sMAL 3.75 | AR 68.7% | 87% | 74% | 62% | 52% | |||
| N=5 0.83x | 2,935 tok/sMAL 4.14 | AR 62.8% | 87% | 73% | 61% | 51% | 42% | ||
| N=6 0.85x | 3,010 tok/sMAL 4.43 | AR 57.2% | 86% | 73% | 61% | 50% | 41% | 33% | |
| N=7 0.88x | 3,105 tok/sMAL 4.68 | AR 52.5% | 86% | 72% | 60% | 50% | 41% | 33% | 27% |
Qwen/Qwen3-8B / EAGLE-3 / HumanEval
HumanEval baseline 3,226 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 0.61x | 1,955 tok/sMAL 1.84 | AR 83.6% | 84% | ||||||
| N=2 0.86x | 2,776 tok/sMAL 2.50 | AR 74.8% | 83% | 67% | |||||
| N=3 1.00x | 3,238 tok/sMAL 2.97 | AR 65.8% | 81% | 65% | 51% | ||||
| N=4 1.04x | 3,346 tok/sMAL 3.36 | AR 58.9% | 81% | 65% | 50% | 39% | |||
| N=5 1.05x | 3,376 tok/sMAL 3.59 | AR 51.9% | 80% | 64% | 49% | 38% | 29% | ||
| N=6 1.04x | 3,369 tok/sMAL 3.80 | AR 46.7% | 80% | 63% | 49% | 38% | 29% | 22% | |
| N=7 1.03x | 3,337 tok/sMAL 3.96 | AR 42.2% | 80% | 63% | 48% | 37% | 28% | 22% | 17% |
Qwen/Qwen3-8B / EAGLE-3 / MBPP
MBPP baseline 3,268 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 0.80x | 2,621 tok/sMAL 1.81 | AR 81.3% | 81% | ||||||
| N=2 0.91x | 2,985 tok/sMAL 2.43 | AR 71.6% | 81% | 63% | |||||
| N=3 1.00x | 3,254 tok/sMAL 2.89 | AR 63.1% | 80% | 62% | 47% | ||||
| N=4 1.11x | 3,631 tok/sMAL 3.23 | AR 55.7% | 79% | 62% | 47% | 35% | |||
| N=5 1.16x | 3,798 tok/sMAL 3.42 | AR 48.5% | 79% | 60% | 45% | 34% | 24% | ||
| N=6 1.07x | 3,513 tok/sMAL 3.64 | AR 43.9% | 79% | 61% | 46% | 34% | 25% | 18% | |
| N=7 1.06x | 3,475 tok/sMAL 3.68 | AR 38.3% | 78% | 60% | 45% | 33% | 24% | 17% | 12% |
Qwen/Qwen3-8B / DFlash / GSM8K
GSM8K baseline 3,698 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.23x | 4,535 tok/sMAL 3.23 | AR 74.3% | 87% | 74% | 62% | ||||||||||||
| N=7 1.25x | 4,608 tok/sMAL 4.84 | AR 54.9% | 86% | 73% | 61% | 51% | 44% | 38% | 32% | ||||||||
| N=11 1.27x | 4,678 tok/sMAL 5.51 | AR 41.0% | 85% | 71% | 58% | 49% | 41% | 35% | 30% | 26% | 22% | 19% | 16% | ||||
| N=15 1.20x | 4,442 tok/sMAL 6.04 | AR 33.6% | 87% | 73% | 60% | 50% | 42% | 35% | 30% | 26% | 22% | 19% | 16% | 14% | 12% | 10% | 8% |
Qwen/Qwen3-8B / DFlash / MATH500
MATH500 baseline 3,530 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 0.99x | 3,487 tok/sMAL 3.41 | AR 80.3% | 90% | 80% | 71% | ||||||||||||
| N=7 1.07x | 3,794 tok/sMAL 5.53 | AR 64.7% | 89% | 79% | 70% | 62% | 56% | 51% | 45% | ||||||||
| N=11 1.08x | 3,828 tok/sMAL 6.69 | AR 51.7% | 89% | 77% | 67% | 59% | 53% | 48% | 43% | 39% | 35% | 32% | 28% | ||||
| N=15 1.10x | 3,868 tok/sMAL 7.52 | AR 43.5% | 90% | 78% | 68% | 59% | 53% | 47% | 42% | 38% | 34% | 31% | 28% | 25% | 22% | 20% | 17% |
Qwen/Qwen3-8B / DFlash / HumanEval
HumanEval baseline 3,226 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.20x | 3,866 tok/sMAL 3.45 | AR 81.6% | 91% | 81% | 73% | ||||||||||||
| N=7 1.27x | 4,103 tok/sMAL 5.27 | AR 61.1% | 88% | 77% | 66% | 58% | 52% | 46% | 41% | ||||||||
| N=11 1.27x | 4,081 tok/sMAL 5.68 | AR 42.5% | 85% | 71% | 59% | 50% | 42% | 36% | 32% | 28% | 24% | 22% | 19% | ||||
| N=15 1.20x | 3,877 tok/sMAL 6.15 | AR 34.3% | 87% | 72% | 59% | 49% | 41% | 35% | 31% | 27% | 24% | 21% | 18% | 16% | 14% | 12% | 10% |
Qwen/Qwen3-8B / DFlash / MBPP
MBPP baseline 3,268 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.21x | 3,952 tok/sMAL 3.44 | AR 81.5% | 91% | 81% | 73% | ||||||||||||
| N=7 1.22x | 3,982 tok/sMAL 4.79 | AR 54.2% | 86% | 71% | 60% | 50% | 43% | 37% | 32% | ||||||||
| N=11 1.22x | 3,974 tok/sMAL 5.23 | AR 38.5% | 84% | 69% | 56% | 46% | 38% | 32% | 27% | 23% | 19% | 16% | 14% | ||||
| N=15 1.13x | 3,695 tok/sMAL 5.59 | AR 30.6% | 86% | 71% | 57% | 47% | 38% | 32% | 26% | 22% | 18% | 15% | 13% | 11% | 9% | 8% | 6% |
Qwen/Qwen3-8B / DSpark / GSM8K
GSM8K baseline 3,698 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.08x | 4,001 tok/sMAL 3.68 | AR 89.3% | 95% | 89% | 84% | ||||||||||||
| N=7 1.63x | 6,032 tok/sMAL 6.49 | AR 78.4% | 95% | 89% | 83% | 78% | 73% | 68% | 63% | ||||||||
| N=11 1.58x | 5,841 tok/sMAL 7.63 | AR 60.3% | 94% | 87% | 80% | 73% | 67% | 61% | 56% | 48% | 40% | 32% | 24% | ||||
| N=15 1.31x | 4,857 tok/sMAL 7.17 | AR 41.2% | 94% | 87% | 79% | 70% | 62% | 54% | 46% | 38% | 30% | 22% | 15% | 10% | 6% | 4% | 2% |
Qwen/Qwen3-8B / DSpark / MATH500
MATH500 baseline 3,530 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 0.73x | 2,589 tok/sMAL 3.67 | AR 88.9% | 95% | 89% | 83% | ||||||||||||
| N=7 1.15x | 4,048 tok/sMAL 6.39 | AR 77.1% | 94% | 88% | 82% | 77% | 71% | 66% | 61% | ||||||||
| N=11 1.12x | 3,937 tok/sMAL 7.18 | AR 56.2% | 93% | 86% | 78% | 71% | 64% | 57% | 50% | 42% | 34% | 25% | 18% | ||||
| N=15 0.96x | 3,376 tok/sMAL 6.83 | AR 38.8% | 93% | 86% | 77% | 69% | 61% | 52% | 42% | 33% | 25% | 17% | 12% | 8% | 5% | 3% | 2% |
Qwen/Qwen3-8B / DSpark / HumanEval
HumanEval baseline 3,226 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 0.96x | 3,090 tok/sMAL 3.53 | AR 84.4% | 92% | 85% | 76% | ||||||||||||
| N=7 1.48x | 4,769 tok/sMAL 5.87 | AR 69.6% | 92% | 84% | 76% | 69% | 62% | 56% | 50% | ||||||||
| N=11 1.32x | 4,271 tok/sMAL 6.28 | AR 48.0% | 91% | 82% | 71% | 62% | 54% | 46% | 39% | 31% | 24% | 17% | 11% | ||||
| N=15 1.04x | 3,357 tok/sMAL 5.81 | AR 32.0% | 91% | 82% | 70% | 60% | 50% | 39% | 30% | 22% | 15% | 10% | 6% | 3% | 2% | 1% | 1% |
Qwen/Qwen3-8B / DSpark / MBPP
MBPP baseline 3,268 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.20x | 3,919 tok/sMAL 3.42 | AR 80.6% | 91% | 81% | 71% | ||||||||||||
| N=7 1.51x | 4,936 tok/sMAL 5.56 | AR 65.1% | 91% | 82% | 72% | 63% | 56% | 49% | 43% | ||||||||
| N=11 1.39x | 4,536 tok/sMAL 5.90 | AR 44.6% | 90% | 79% | 68% | 58% | 50% | 42% | 35% | 27% | 20% | 14% | 9% | ||||
| N=15 1.16x | 3,779 tok/sMAL 5.40 | AR 29.3% | 90% | 78% | 66% | 55% | 44% | 35% | 26% | 18% | 12% | 7% | 4% | 2% | 1% | 1% | 0% |
Qwen/Qwen3.5-27B / Native MTP / GSM8K
GSM8K baseline 1,555 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 1.11x | 1,724 tok/sMAL 1.97 | AR 96.5% | 97% | ||||||
| N=2 1.37x | 2,133 tok/sMAL 2.86 | AR 92.8% | 96% | 89% | |||||
| N=3 1.50x | 2,337 tok/sMAL 3.65 | AR 88.2% | 96% | 89% | 80% | ||||
| N=4 1.62x | 2,522 tok/sMAL 4.32 | AR 83.0% | 96% | 88% | 79% | 70% | |||
| N=5 1.63x | 2,537 tok/sMAL 4.89 | AR 77.9% | 95% | 87% | 78% | 69% | 60% | ||
| N=6 1.66x | 2,575 tok/sMAL 5.37 | AR 72.8% | 95% | 87% | 77% | 68% | 59% | 51% | |
| N=7 1.56x | 2,423 tok/sMAL 5.77 | AR 68.2% | 95% | 86% | 77% | 68% | 59% | 50% | 43% |
Qwen/Qwen3.5-27B / Native MTP / MATH500
MATH500 baseline 1,500 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 1.10x | 1,644 tok/sMAL 1.97 | AR 96.5% | 97% | ||||||
| N=2 1.39x | 2,085 tok/sMAL 2.86 | AR 92.8% | 96% | 89% | |||||
| N=3 1.56x | 2,345 tok/sMAL 3.65 | AR 88.2% | 96% | 89% | 80% | ||||
| N=4 1.66x | 2,489 tok/sMAL 4.32 | AR 83.0% | 96% | 88% | 79% | 70% | |||
| N=5 1.71x | 2,564 tok/sMAL 4.89 | AR 77.8% | 95% | 87% | 78% | 69% | 60% | ||
| N=6 1.70x | 2,549 tok/sMAL 5.35 | AR 72.5% | 95% | 87% | 77% | 67% | 58% | 50% | |
| N=7 1.55x | 2,325 tok/sMAL 5.73 | AR 67.5% | 95% | 86% | 77% | 67% | 58% | 49% | 42% |
Qwen/Qwen3.5-27B / Native MTP / HumanEval
HumanEval baseline 1,256 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 1.15x | 1,439 tok/sMAL 1.97 | AR 96.5% | 97% | ||||||
| N=2 1.20x | 1,507 tok/sMAL 2.86 | AR 92.5% | 96% | 89% | |||||
| N=3 1.53x | 1,917 tok/sMAL 3.63 | AR 87.8% | 95% | 88% | 80% | ||||
| N=4 1.63x | 2,044 tok/sMAL 4.31 | AR 82.7% | 95% | 87% | 79% | 70% | |||
| N=5 1.55x | 1,953 tok/sMAL 4.89 | AR 77.8% | 95% | 87% | 78% | 69% | 61% | ||
| N=6 1.46x | 1,836 tok/sMAL 5.39 | AR 73.1% | 95% | 86% | 77% | 69% | 60% | 52% | |
| N=7 1.41x | 1,766 tok/sMAL 5.73 | AR 67.6% | 94% | 85% | 76% | 67% | 58% | 50% | 43% |
Qwen/Qwen3.5-27B / Native MTP / MBPP
MBPP baseline 1,418 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 1.10x | 1,562 tok/sMAL 1.94 | AR 94.4% | 94% | ||||||
| N=2 1.39x | 1,974 tok/sMAL 2.76 | AR 88.2% | 93% | 83% | |||||
| N=3 1.49x | 2,117 tok/sMAL 3.46 | AR 81.9% | 93% | 82% | 71% | ||||
| N=4 1.60x | 2,268 tok/sMAL 4.03 | AR 75.7% | 93% | 81% | 70% | 59% | |||
| N=5 1.59x | 2,254 tok/sMAL 4.42 | AR 68.3% | 92% | 79% | 67% | 56% | 47% | ||
| N=6 1.57x | 2,233 tok/sMAL 4.77 | AR 62.9% | 92% | 79% | 67% | 56% | 47% | 38% | |
| N=7 1.41x | 1,995 tok/sMAL 5.02 | AR 57.5% | 91% | 78% | 65% | 55% | 46% | 38% | 30% |
Qwen/Qwen3.5-27B / DFlash / GSM8K
GSM8K baseline 1,555 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.45x | 2,247 tok/sMAL 3.57 | AR 85.6% | 95% | 86% | 76% | ||||||||||||
| N=7 1.54x | 2,397 tok/sMAL 5.64 | AR 66.3% | 93% | 83% | 74% | 65% | 57% | 50% | 43% | ||||||||
| N=11 1.50x | 2,335 tok/sMAL 6.63 | AR 51.2% | 92% | 81% | 71% | 62% | 54% | 47% | 41% | 36% | 31% | 27% | 23% | ||||
| N=15 1.32x | 2,054 tok/sMAL 7.11 | AR 40.7% | 92% | 81% | 70% | 61% | 52% | 45% | 39% | 34% | 30% | 26% | 22% | 19% | 16% | 13% | 11% |
Qwen/Qwen3.5-27B / DFlash / MATH500
MATH500 baseline 1,500 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.51x | 2,259 tok/sMAL 3.60 | AR 86.8% | 95% | 87% | 78% | ||||||||||||
| N=7 1.61x | 2,421 tok/sMAL 5.80 | AR 68.6% | 93% | 84% | 75% | 67% | 60% | 53% | 47% | ||||||||
| N=11 1.65x | 2,482 tok/sMAL 6.98 | AR 54.3% | 93% | 82% | 73% | 64% | 57% | 50% | 45% | 40% | 35% | 31% | 27% | ||||
| N=15 1.47x | 2,208 tok/sMAL 7.56 | AR 43.7% | 93% | 82% | 72% | 63% | 56% | 49% | 43% | 38% | 34% | 30% | 26% | 22% | 19% | 16% | 14% |
Qwen/Qwen3.5-27B / DFlash / HumanEval
HumanEval baseline 1,256 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.46x | 1,829 tok/sMAL 3.61 | AR 87.0% | 95% | 87% | 79% | ||||||||||||
| N=7 1.22x | 1,535 tok/sMAL 5.82 | AR 68.9% | 93% | 84% | 75% | 67% | 61% | 55% | 49% | ||||||||
| N=11 1.40x | 1,757 tok/sMAL 6.88 | AR 53.5% | 91% | 80% | 70% | 62% | 56% | 50% | 45% | 40% | 36% | 32% | 28% | ||||
| N=15 1.40x | 1,761 tok/sMAL 7.57 | AR 43.8% | 92% | 81% | 70% | 62% | 55% | 49% | 43% | 38% | 34% | 31% | 27% | 24% | 21% | 18% | 14% |
Qwen/Qwen3.5-27B / DFlash / MBPP
MBPP baseline 1,418 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.44x | 2,042 tok/sMAL 3.37 | AR 79.0% | 91% | 79% | 67% | ||||||||||||
| N=7 1.38x | 1,963 tok/sMAL 4.91 | AR 55.9% | 88% | 74% | 61% | 52% | 45% | 39% | 33% | ||||||||
| N=11 1.25x | 1,770 tok/sMAL 5.51 | AR 41.0% | 87% | 70% | 57% | 48% | 41% | 35% | 30% | 26% | 23% | 19% | 16% | ||||
| N=15 1.06x | 1,504 tok/sMAL 5.99 | AR 33.3% | 87% | 72% | 58% | 48% | 41% | 35% | 30% | 26% | 22% | 19% | 16% | 14% | 12% | 10% | 8% |
Qwen/Qwen3.5-122B-A10B / Native MTP / GSM8K
GSM8K baseline 1,494 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 1.02x | 1,528 tok/sMAL 1.96 | AR 96.0% | 96% | ||||||
| N=2 1.47x | 2,202 tok/sMAL 2.85 | AR 92.6% | 96% | 89% | |||||
| N=3 1.64x | 2,445 tok/sMAL 3.64 | AR 87.9% | 95% | 88% | 80% | ||||
| N=4 1.81x | 2,697 tok/sMAL 4.31 | AR 82.8% | 95% | 87% | 79% | 71% | |||
| N=5 1.98x | 2,958 tok/sMAL 4.93 | AR 78.6% | 95% | 87% | 79% | 70% | 62% | ||
| N=6 1.98x | 2,953 tok/sMAL 5.42 | AR 73.6% | 95% | 87% | 78% | 69% | 61% | 53% | |
| N=7 2.08x | 3,107 tok/sMAL 5.85 | AR 69.3% | 95% | 86% | 77% | 69% | 60% | 53% | 46% |
Qwen/Qwen3.5-122B-A10B / Native MTP / MATH500
MATH500 baseline 1,446 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 1.06x | 1,529 tok/sMAL 1.97 | AR 96.5% | 97% | ||||||
| N=2 1.58x | 2,280 tok/sMAL 2.86 | AR 93.0% | 96% | 90% | |||||
| N=3 1.82x | 2,625 tok/sMAL 3.67 | AR 89.0% | 96% | 90% | 82% | ||||
| N=4 1.97x | 2,843 tok/sMAL 4.37 | AR 84.3% | 96% | 89% | 81% | 72% | |||
| N=5 2.14x | 3,088 tok/sMAL 4.98 | AR 79.6% | 95% | 88% | 80% | 72% | 63% | ||
| N=6 2.13x | 3,078 tok/sMAL 5.49 | AR 74.9% | 95% | 88% | 79% | 71% | 62% | 55% | |
| N=7 2.20x | 3,183 tok/sMAL 5.91 | AR 70.1% | 95% | 87% | 78% | 70% | 61% | 54% | 46% |
Qwen/Qwen3.5-122B-A10B / Native MTP / HumanEval
HumanEval baseline 1,105 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 1.02x | 1,131 tok/sMAL 1.97 | AR 96.6% | 97% | ||||||
| N=2 1.46x | 1,610 tok/sMAL 2.86 | AR 93.1% | 96% | 90% | |||||
| N=3 1.69x | 1,868 tok/sMAL 3.68 | AR 89.3% | 96% | 90% | 82% | ||||
| N=4 1.69x | 1,869 tok/sMAL 4.38 | AR 84.6% | 95% | 89% | 81% | 73% | |||
| N=5 1.83x | 2,017 tok/sMAL 5.03 | AR 80.5% | 95% | 88% | 80% | 73% | 66% | ||
| N=6 1.83x | 2,021 tok/sMAL 5.65 | AR 77.6% | 95% | 89% | 81% | 74% | 67% | 60% | |
| N=7 1.85x | 2,044 tok/sMAL 6.07 | AR 72.4% | 95% | 87% | 80% | 72% | 65% | 57% | 51% |
Qwen/Qwen3.5-122B-A10B / Native MTP / MBPP
MBPP baseline 1,459 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 |
|---|---|---|---|---|---|---|---|
| N=1 0.99x | 1,447 tok/sMAL 1.95 | AR 95.0% | 95% | ||||||
| N=2 1.43x | 2,092 tok/sMAL 2.86 | AR 92.8% | 96% | 90% | |||||
| N=3 1.60x | 2,336 tok/sMAL 3.56 | AR 85.4% | 94% | 86% | 77% | ||||
| N=4 1.66x | 2,422 tok/sMAL 4.19 | AR 79.7% | 93% | 85% | 75% | 66% | |||
| N=5 1.75x | 2,558 tok/sMAL 4.68 | AR 73.5% | 93% | 83% | 73% | 64% | 56% | ||
| N=6 1.84x | 2,678 tok/sMAL 5.16 | AR 69.4% | 93% | 83% | 73% | 64% | 56% | 49% | |
| N=7 1.88x | 2,747 tok/sMAL 5.56 | AR 65.1% | 93% | 83% | 73% | 64% | 55% | 48% | 41% |
Qwen/Qwen3.5-122B-A10B / DFlash / GSM8K
GSM8K baseline 1,494 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.41x | 2,111 tok/sMAL 3.26 | AR 75.4% | 88% | 75% | 63% | ||||||||||||
| N=7 1.58x | 2,356 tok/sMAL 4.19 | AR 45.6% | 81% | 65% | 52% | 41% | 33% | 26% | 21% | ||||||||
| N=11 1.38x | 2,066 tok/sMAL 4.17 | AR 28.8% | 78% | 61% | 47% | 36% | 27% | 21% | 15% | 11% | 9% | 6% | 5% | ||||
| N=15 1.01x | 1,508 tok/sMAL 3.81 | AR 18.7% | 77% | 58% | 43% | 31% | 23% | 16% | 11% | 8% | 5% | 4% | 2% | 2% | 1% | 1% | 0% |
Qwen/Qwen3.5-122B-A10B / DFlash / MATH500
MATH500 baseline 1,446 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.62x | 2,336 tok/sMAL 3.34 | AR 78.0% | 89% | 78% | 67% | ||||||||||||
| N=7 1.78x | 2,572 tok/sMAL 4.45 | AR 49.2% | 84% | 68% | 56% | 45% | 37% | 30% | 25% | ||||||||
| N=11 1.64x | 2,367 tok/sMAL 4.50 | AR 31.9% | 82% | 65% | 51% | 40% | 31% | 24% | 19% | 14% | 11% | 8% | 6% | ||||
| N=15 1.25x | 1,805 tok/sMAL 4.01 | AR 20.0% | 80% | 60% | 45% | 33% | 25% | 18% | 13% | 9% | 6% | 4% | 3% | 2% | 1% | 1% | 1% |
Qwen/Qwen3.5-122B-A10B / DFlash / HumanEval
HumanEval baseline 1,105 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.40x | 1,551 tok/sMAL 3.40 | AR 79.9% | 90% | 80% | 70% | ||||||||||||
| N=7 1.66x | 1,838 tok/sMAL 4.53 | AR 50.5% | 84% | 69% | 57% | 47% | 38% | 32% | 26% | ||||||||
| N=11 1.20x | 1,331 tok/sMAL 4.56 | AR 32.4% | 82% | 64% | 51% | 40% | 31% | 25% | 20% | 16% | 12% | 9% | 7% | ||||
| N=15 0.94x | 1,042 tok/sMAL 4.05 | AR 20.3% | 79% | 60% | 45% | 34% | 25% | 19% | 14% | 10% | 7% | 5% | 3% | 2% | 2% | 1% | 1% |
Qwen/Qwen3.5-122B-A10B / DFlash / MBPP
MBPP baseline 1,459 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.38x | 2,019 tok/sMAL 3.29 | AR 76.3% | 88% | 76% | 65% | ||||||||||||
| N=7 1.05x | 1,529 tok/sMAL 4.12 | AR 44.6% | 80% | 62% | 49% | 40% | 33% | 27% | 22% | ||||||||
| N=11 1.34x | 1,958 tok/sMAL 4.21 | AR 29.1% | 80% | 59% | 45% | 35% | 27% | 21% | 17% | 13% | 10% | 8% | 6% | ||||
| N=15 0.95x | 1,386 tok/sMAL 3.68 | AR 17.9% | 75% | 53% | 38% | 28% | 21% | 15% | 11% | 9% | 6% | 4% | 3% | 2% | 1% | 1% | 1% |
Qwen/Qwen3.6-27B / Native MTP / GSM8K
GSM8K baseline 1,521 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.20x | 1,830 tok/sMAL 1.95 | AR 94.5% | 95% | ||||
| N=2 1.45x | 2,212 tok/sMAL 2.79 | AR 89.7% | 94% | 85% | |||
| N=3 1.61x | 2,441 tok/sMAL 3.53 | AR 84.2% | 94% | 84% | 75% | ||
| N=4 1.69x | 2,570 tok/sMAL 4.15 | AR 78.7% | 93% | 83% | 74% | 65% | |
| N=5 1.72x | 2,609 tok/sMAL 4.66 | AR 73.3% | 93% | 82% | 73% | 64% | 55% |
Qwen/Qwen3.6-27B / Native MTP / MATH500
MATH500 baseline 1,514 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.20x | 1,820 tok/sMAL 1.96 | AR 95.9% | 96% | ||||
| N=2 1.48x | 2,235 tok/sMAL 2.84 | AR 91.9% | 96% | 88% | |||
| N=3 1.64x | 2,488 tok/sMAL 3.61 | AR 87.1% | 95% | 87% | 79% | ||
| N=4 1.75x | 2,647 tok/sMAL 4.28 | AR 82.1% | 95% | 87% | 78% | 69% | |
| N=5 1.78x | 2,701 tok/sMAL 4.83 | AR 76.7% | 94% | 86% | 77% | 68% | 59% |
Qwen/Qwen3.6-27B / Native MTP / HumanEval
HumanEval baseline 1,481 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.19x | 1,756 tok/sMAL 1.93 | AR 92.9% | 93% | ||||
| N=2 1.42x | 2,101 tok/sMAL 2.73 | AR 86.6% | 92% | 81% | |||
| N=3 1.53x | 2,270 tok/sMAL 3.40 | AR 80.2% | 92% | 80% | 69% | ||
| N=4 1.60x | 2,373 tok/sMAL 3.94 | AR 73.6% | 91% | 79% | 67% | 57% | |
| N=5 1.60x | 2,365 tok/sMAL 4.36 | AR 67.2% | 90% | 78% | 66% | 56% | 47% |
Qwen/Qwen3.6-27B / Native MTP / MBPP
MBPP baseline 1,495 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.22x | 1,827 tok/sMAL 1.92 | AR 91.7% | 92% | ||||
| N=2 1.44x | 2,156 tok/sMAL 2.69 | AR 84.6% | 91% | 78% | |||
| N=3 1.57x | 2,341 tok/sMAL 3.31 | AR 77.2% | 90% | 77% | 64% | ||
| N=4 1.61x | 2,411 tok/sMAL 3.80 | AR 70.0% | 89% | 76% | 63% | 52% | |
| N=5 1.60x | 2,389 tok/sMAL 4.16 | AR 63.3% | 89% | 74% | 62% | 50% | 41% |
Qwen/Qwen3.6-27B / DFlash / GSM8K
GSM8K baseline 1,521 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.39x | 2,112 tok/sMAL 3.48 | AR 82.6% | 93% | 83% | 72% | ||||||||||||
| N=7 1.43x | 2,176 tok/sMAL 5.34 | AR 62.0% | 91% | 80% | 69% | 60% | 52% | 44% | 38% | ||||||||
| N=11 1.42x | 2,160 tok/sMAL 6.18 | AR 47.1% | 90% | 78% | 67% | 57% | 49% | 42% | 36% | 31% | 26% | 22% | 19% | ||||
| N=15 1.24x | 1,883 tok/sMAL 6.52 | AR 36.8% | 90% | 77% | 66% | 56% | 48% | 41% | 34% | 29% | 25% | 21% | 18% | 15% | 13% | 11% | 9% |
Qwen/Qwen3.6-27B / DFlash / MATH500
MATH500 baseline 1,514 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.44x | 2,185 tok/sMAL 3.58 | AR 85.9% | 94% | 86% | 77% | ||||||||||||
| N=7 1.54x | 2,339 tok/sMAL 5.73 | AR 67.6% | 93% | 83% | 74% | 66% | 59% | 53% | 46% | ||||||||
| N=11 1.59x | 2,411 tok/sMAL 6.86 | AR 53.3% | 92% | 81% | 72% | 63% | 56% | 49% | 44% | 39% | 34% | 30% | 26% | ||||
| N=15 1.41x | 2,136 tok/sMAL 7.37 | AR 42.5% | 91% | 80% | 70% | 61% | 54% | 47% | 42% | 37% | 32% | 28% | 25% | 22% | 19% | 16% | 14% |
Qwen/Qwen3.6-27B / DFlash / HumanEval
HumanEval baseline 1,481 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.40x | 2,067 tok/sMAL 3.44 | AR 81.4% | 92% | 82% | 70% | ||||||||||||
| N=7 1.40x | 2,070 tok/sMAL 5.19 | AR 59.9% | 91% | 78% | 67% | 57% | 49% | 42% | 36% | ||||||||
| N=11 1.39x | 2,061 tok/sMAL 5.96 | AR 45.1% | 90% | 76% | 64% | 54% | 45% | 39% | 33% | 29% | 25% | 22% | 20% | ||||
| N=15 1.21x | 1,793 tok/sMAL 6.27 | AR 35.2% | 89% | 75% | 62% | 52% | 43% | 36% | 31% | 27% | 23% | 20% | 18% | 15% | 14% | 12% | 10% |
Qwen/Qwen3.6-27B / DFlash / MBPP
MBPP baseline 1,495 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.38x | 2,069 tok/sMAL 3.33 | AR 77.7% | 91% | 78% | 65% | ||||||||||||
| N=7 1.37x | 2,047 tok/sMAL 4.81 | AR 54.4% | 89% | 74% | 61% | 51% | 42% | 35% | 29% | ||||||||
| N=11 1.29x | 1,925 tok/sMAL 5.37 | AR 39.7% | 88% | 73% | 59% | 48% | 40% | 32% | 27% | 22% | 19% | 16% | 13% | ||||
| N=15 1.11x | 1,658 tok/sMAL 5.57 | AR 30.5% | 87% | 72% | 58% | 47% | 38% | 31% | 26% | 21% | 18% | 15% | 12% | 10% | 9% | 7% | 6% |
Qwen/Qwen3.6-35B-A3B / Native MTP / GSM8K
GSM8K baseline 2,275 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 |
|---|---|---|---|---|---|---|
| N=1 0.89x | 2,023 tok/sMAL 1.94 | AR 93.7% | 94% | |||||
| N=2 1.12x | 2,544 tok/sMAL 2.77 | AR 88.5% | 93% | 84% | ||||
| N=3 1.27x | 2,894 tok/sMAL 3.49 | AR 82.8% | 93% | 83% | 73% | |||
| N=4 1.25x | 2,854 tok/sMAL 4.07 | AR 76.8% | 92% | 82% | 72% | 62% | ||
| N=5 1.31x | 2,976 tok/sMAL 4.57 | AR 71.4% | 92% | 81% | 71% | 61% | 53% | |
| N=6 1.43x | 3,253 tok/sMAL 4.97 | AR 66.1% | 91% | 80% | 70% | 60% | 52% | 44% |
Qwen/Qwen3.6-35B-A3B / Native MTP / MATH500
MATH500 baseline 2,235 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 |
|---|---|---|---|---|---|---|
| N=1 0.88x | 1,973 tok/sMAL 1.95 | AR 95.5% | 96% | |||||
| N=2 1.13x | 2,515 tok/sMAL 2.83 | AR 91.3% | 95% | 88% | ||||
| N=3 1.29x | 2,889 tok/sMAL 3.59 | AR 86.3% | 95% | 87% | 78% | |||
| N=4 1.28x | 2,871 tok/sMAL 4.24 | AR 81.0% | 94% | 86% | 77% | 68% | ||
| N=5 1.35x | 3,020 tok/sMAL 4.79 | AR 75.7% | 94% | 85% | 76% | 67% | 58% | |
| N=6 1.49x | 3,334 tok/sMAL 5.25 | AR 70.8% | 93% | 84% | 75% | 66% | 57% | 50% |
Qwen/Qwen3.6-35B-A3B / Native MTP / HumanEval
HumanEval baseline 2,193 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 |
|---|---|---|---|---|---|---|
| N=1 0.87x | 1,900 tok/sMAL 1.92 | AR 91.6% | 92% | |||||
| N=2 1.07x | 2,346 tok/sMAL 2.70 | AR 84.8% | 91% | 79% | ||||
| N=3 1.20x | 2,640 tok/sMAL 3.33 | AR 77.7% | 90% | 77% | 66% | |||
| N=4 1.17x | 2,559 tok/sMAL 3.85 | AR 71.3% | 90% | 77% | 65% | 54% | ||
| N=5 1.18x | 2,587 tok/sMAL 4.21 | AR 64.2% | 89% | 75% | 62% | 52% | 43% | |
| N=6 1.28x | 2,811 tok/sMAL 4.51 | AR 58.4% | 88% | 74% | 61% | 50% | 42% | 35% |
Qwen/Qwen3.6-35B-A3B / Native MTP / MBPP
MBPP baseline 2,258 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 |
|---|---|---|---|---|---|---|
| N=1 0.89x | 2,005 tok/sMAL 1.90 | AR 90.5% | 91% | |||||
| N=2 1.10x | 2,480 tok/sMAL 2.66 | AR 82.9% | 90% | 76% | ||||
| N=3 1.23x | 2,773 tok/sMAL 3.26 | AR 75.2% | 89% | 75% | 62% | |||
| N=4 1.19x | 2,676 tok/sMAL 3.72 | AR 67.9% | 88% | 74% | 61% | 50% | ||
| N=5 1.22x | 2,747 tok/sMAL 4.08 | AR 61.5% | 87% | 73% | 59% | 49% | 40% | |
| N=6 1.29x | 2,903 tok/sMAL 4.34 | AR 55.6% | 87% | 72% | 58% | 47% | 39% | 31% |
Qwen/Qwen3.6-35B-A3B / DFlash / GSM8K
GSM8K baseline 2,275 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.54x | 3,510 tok/sMAL 3.47 | AR 82.4% | 92% | 82% | 73% | ||||||||||||
| N=7 1.88x | 4,276 tok/sMAL 5.42 | AR 63.1% | 90% | 79% | 69% | 61% | 54% | 48% | 42% | ||||||||
| N=11 1.70x | 3,871 tok/sMAL 6.40 | AR 49.1% | 89% | 77% | 66% | 58% | 51% | 45% | 39% | 35% | 30% | 27% | 23% | ||||
| N=15 1.49x | 3,394 tok/sMAL 6.88 | AR 39.2% | 89% | 75% | 65% | 56% | 49% | 43% | 37% | 33% | 29% | 25% | 22% | 20% | 17% | 15% | 13% |
Qwen/Qwen3.6-35B-A3B / DFlash / MATH500
MATH500 baseline 2,235 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.64x | 3,655 tok/sMAL 3.58 | AR 86.1% | 94% | 86% | 78% | ||||||||||||
| N=7 2.06x | 4,600 tok/sMAL 5.82 | AR 68.8% | 93% | 83% | 74% | 67% | 61% | 55% | 50% | ||||||||
| N=11 1.97x | 4,404 tok/sMAL 7.13 | AR 55.7% | 91% | 80% | 71% | 64% | 58% | 52% | 47% | 43% | 39% | 35% | 31% | ||||
| N=15 1.76x | 3,938 tok/sMAL 7.80 | AR 45.3% | 91% | 79% | 70% | 62% | 55% | 50% | 45% | 40% | 36% | 32% | 29% | 27% | 24% | 22% | 19% |
Qwen/Qwen3.6-35B-A3B / DFlash / HumanEval
HumanEval baseline 2,193 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.58x | 3,476 tok/sMAL 3.42 | AR 80.7% | 92% | 80% | 70% | ||||||||||||
| N=7 1.84x | 4,036 tok/sMAL 5.22 | AR 60.3% | 90% | 77% | 66% | 57% | 50% | 44% | 38% | ||||||||
| N=11 1.63x | 3,584 tok/sMAL 6.01 | AR 45.6% | 89% | 75% | 63% | 53% | 46% | 39% | 34% | 30% | 27% | 24% | 22% | ||||
| N=15 1.52x | 3,334 tok/sMAL 6.39 | AR 35.9% | 88% | 73% | 61% | 51% | 43% | 37% | 32% | 28% | 25% | 22% | 20% | 18% | 16% | 14% | 13% |
Qwen/Qwen3.6-35B-A3B / DFlash / MBPP
MBPP baseline 2,258 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.53x | 3,462 tok/sMAL 3.34 | AR 77.9% | 91% | 78% | 66% | ||||||||||||
| N=7 1.77x | 3,990 tok/sMAL 4.87 | AR 55.3% | 88% | 74% | 61% | 52% | 44% | 37% | 32% | ||||||||
| N=11 1.53x | 3,444 tok/sMAL 5.52 | AR 41.1% | 87% | 72% | 59% | 49% | 41% | 35% | 30% | 25% | 22% | 19% | 16% | ||||
| N=15 1.38x | 3,127 tok/sMAL 5.81 | AR 32.1% | 87% | 71% | 57% | 47% | 39% | 33% | 28% | 24% | 20% | 17% | 15% | 13% | 11% | 10% | 9% |
moonshotai/Kimi-K2.5 / EAGLE-3 / GSM8K
GSM8K baseline 324 tok/s
| N | p1 | p2 | p3 | p4 |
|---|---|---|---|---|
| N=1 1.54x | 499 tok/sMAL 1.92 | AR 91.6% | 92% | |||
| N=2 1.85x | 600 tok/sMAL 2.72 | AR 85.8% | 91% | 81% | ||
| N=3 2.09x | 677 tok/sMAL 3.40 | AR 80.0% | 90% | 80% | 70% | |
| N=4 2.24x | 728 tok/sMAL 3.96 | AR 73.9% | 89% | 78% | 68% | 60% |
moonshotai/Kimi-K2.5 / EAGLE-3 / MATH500
MATH500 baseline 310 tok/s
| N | p1 | p2 | p3 | p4 |
|---|---|---|---|---|
| N=1 1.54x | 480 tok/sMAL 1.94 | AR 93.6% | 94% | |||
| N=2 1.88x | 584 tok/sMAL 2.77 | AR 88.6% | 93% | 84% | ||
| N=3 2.14x | 664 tok/sMAL 3.48 | AR 82.7% | 92% | 83% | 73% | |
| N=4 2.33x | 722 tok/sMAL 4.09 | AR 77.2% | 92% | 82% | 72% | 63% |
moonshotai/Kimi-K2.5 / EAGLE-3 / HumanEval
HumanEval baseline 301 tok/s
| N | p1 | p2 | p3 | p4 |
|---|---|---|---|---|
| N=1 1.51x | 456 tok/sMAL 1.90 | AR 90.3% | 90% | |||
| N=2 1.81x | 546 tok/sMAL 2.67 | AR 83.6% | 89% | 78% | ||
| N=3 2.03x | 610 tok/sMAL 3.30 | AR 76.8% | 89% | 76% | 66% | |
| N=4 2.16x | 649 tok/sMAL 3.79 | AR 69.8% | 87% | 74% | 63% | 54% |
moonshotai/Kimi-K2.5 / EAGLE-3 / MBPP
MBPP baseline 311 tok/s
| N | p1 | p2 | p3 | p4 |
|---|---|---|---|---|
| N=1 1.52x | 472 tok/sMAL 1.88 | AR 88.1% | 88% | |||
| N=2 1.78x | 553 tok/sMAL 2.59 | AR 79.6% | 87% | 72% | ||
| N=3 1.95x | 608 tok/sMAL 3.14 | AR 71.5% | 86% | 71% | 58% | |
| N=4 1.99x | 619 tok/sMAL 3.53 | AR 63.4% | 84% | 69% | 56% | 45% |
moonshotai/Kimi-K2.5 / DFlash / GSM8K
GSM8K baseline 324 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 2.01x | 651 tok/sMAL 3.30 | AR 76.6% | 89% | 77% | 64% | ||||||||||||
| N=7 2.37x | 768 tok/sMAL 4.80 | AR 54.3% | 87% | 73% | 61% | 51% | 43% | 36% | 29% | ||||||||
| N=11 2.23x | 723 tok/sMAL 5.06 | AR 36.9% | 86% | 71% | 58% | 47% | 38% | 31% | 25% | 19% | 15% | 11% | 7% | ||||
| N=15 2.05x | 665 tok/sMAL 5.02 | AR 26.8% | 85% | 70% | 56% | 46% | 37% | 30% | 24% | 18% | 14% | 10% | 6% | 4% | 2% | 1% | 1% |
moonshotai/Kimi-K2.5 / DFlash / MATH500
MATH500 baseline 310 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 2.12x | 659 tok/sMAL 3.49 | AR 83.1% | 93% | 83% | 73% | ||||||||||||
| N=7 2.68x | 832 tok/sMAL 5.38 | AR 62.6% | 91% | 80% | 70% | 61% | 53% | 46% | 39% | ||||||||
| N=11 2.64x | 818 tok/sMAL 5.90 | AR 44.5% | 90% | 77% | 66% | 56% | 48% | 41% | 34% | 28% | 22% | 17% | 12% | ||||
| N=15 2.42x | 750 tok/sMAL 5.86 | AR 32.4% | 89% | 76% | 65% | 55% | 47% | 39% | 32% | 26% | 20% | 14% | 10% | 6% | 4% | 2% | 1% |
moonshotai/Kimi-K2.5 / DFlash / HumanEval
HumanEval baseline 301 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 2.02x | 609 tok/sMAL 3.32 | AR 77.4% | 90% | 77% | 66% | ||||||||||||
| N=7 2.42x | 727 tok/sMAL 4.87 | AR 55.3% | 87% | 73% | 61% | 52% | 44% | 38% | 32% | ||||||||
| N=11 2.32x | 699 tok/sMAL 5.24 | AR 38.6% | 86% | 71% | 57% | 47% | 39% | 32% | 27% | 22% | 18% | 14% | 11% | ||||
| N=15 2.20x | 661 tok/sMAL 5.34 | AR 28.9% | 86% | 71% | 58% | 47% | 39% | 32% | 27% | 22% | 17% | 13% | 9% | 6% | 4% | 2% | 1% |
moonshotai/Kimi-K2.5 / DFlash / MBPP
MBPP baseline 311 tok/s
| N | p1 | p2 | p3 | p4 | p5 | p6 | p7 | p8 | p9 | p10 | p11 | p12 | p13 | p14 | p15 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| N=3 1.96x | 609 tok/sMAL 3.17 | AR 72.4% | 87% | 72% | 58% | ||||||||||||
| N=7 2.21x | 687 tok/sMAL 4.41 | AR 48.8% | 85% | 69% | 55% | 44% | 36% | 29% | 23% | ||||||||
| N=11 2.04x | 636 tok/sMAL 4.53 | AR 32.1% | 84% | 66% | 52% | 40% | 31% | 24% | 19% | 14% | 11% | 8% | 5% | ||||
| N=15 1.88x | 586 tok/sMAL 4.50 | AR 23.3% | 83% | 66% | 51% | 40% | 31% | 24% | 18% | 13% | 10% | 7% | 4% | 3% | 1% | 1% | 0% |
MiniMaxAI/MiniMax-M3-MXFP8 / EAGLE-3 / GSM8K
GSM8K baseline 2,086 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.31x | 2,743 tok/sMAL 1.92 | AR 92.2% | 92% | ||||
| N=2 1.56x | 3,249 tok/sMAL 2.73 | AR 86.4% | 91% | 82% | |||
| N=3 1.65x | 3,434 tok/sMAL 3.42 | AR 80.8% | 91% | 81% | 71% | ||
| N=4 1.82x | 3,807 tok/sMAL 4.01 | AR 75.3% | 90% | 80% | 70% | 62% | |
| N=5 1.82x | 3,787 tok/sMAL 4.45 | AR 69.0% | 89% | 78% | 68% | 59% | 52% |
MiniMaxAI/MiniMax-M3-MXFP8 / EAGLE-3 / MATH500
MATH500 baseline 2,468 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.35x | 3,338 tok/sMAL 1.93 | AR 93.0% | 93% | ||||
| N=2 1.64x | 4,047 tok/sMAL 2.74 | AR 87.1% | 92% | 82% | |||
| N=3 1.84x | 4,551 tok/sMAL 3.44 | AR 81.3% | 92% | 81% | 71% | ||
| N=4 1.93x | 4,772 tok/sMAL 4.01 | AR 75.2% | 91% | 80% | 70% | 60% | |
| N=5 1.90x | 4,677 tok/sMAL 4.39 | AR 67.8% | 90% | 78% | 67% | 57% | 49% |
MiniMaxAI/MiniMax-M3-MXFP8 / EAGLE-3 / HumanEval
HumanEval baseline 2,317 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.39x | 3,224 tok/sMAL 1.93 | AR 93.1% | 93% | ||||
| N=2 1.70x | 3,931 tok/sMAL 2.74 | AR 87.1% | 92% | 82% | |||
| N=3 1.82x | 4,208 tok/sMAL 3.43 | AR 81.0% | 91% | 81% | 71% | ||
| N=4 2.09x | 4,835 tok/sMAL 4.05 | AR 76.2% | 91% | 81% | 71% | 62% | |
| N=5 1.95x | 4,529 tok/sMAL 4.46 | AR 69.2% | 90% | 78% | 68% | 59% | 51% |
MiniMaxAI/MiniMax-M3-MXFP8 / EAGLE-3 / MBPP
MBPP baseline 2,277 tok/s
| N | p1 | p2 | p3 | p4 | p5 |
|---|---|---|---|---|---|
| N=1 1.36x | 3,095 tok/sMAL 1.91 | AR 90.6% | 91% | ||||
| N=2 1.68x | 3,825 tok/sMAL 2.68 | AR 84.2% | 90% | 78% | |||
| N=3 1.89x | 4,298 tok/sMAL 3.31 | AR 77.1% | 89% | 77% | 65% | ||
| N=4 1.97x | 4,487 tok/sMAL 3.82 | AR 70.5% | 89% | 76% | 64% | 53% | |
| N=5 1.93x | 4,392 tok/sMAL 4.18 | AR 63.6% | 88% | 75% | 62% | 51% | 43% |
MAL means mean accepted length. AR means acceptance rate.
Example vLLM serve commands used in the experiments
### `google/gemma-4-26B-A4B-it` Baseline:VLLM_USE_V2_MODEL_RUNNER=1 \
vllm serve google/gemma-4-26B-A4B-it \
--trust-remote-code \
--tensor-parallel-size 2 \
--language-model-only \
--reasoning-parser gemma4 \
--enable-auto-tool-choice \
--tool-call-parser gemma4 \
--chat-template /app/vllm/examples/tool_chat_template_gemma4.jinja \
--max-num-batched-tokens 16384 \
--max-model-len 32768
VLLM_USE_V2_MODEL_RUNNER=1 \
vllm serve google/gemma-4-26B-A4B-it \
--tensor-parallel-size 2 \
--language-model-only \
--reasoning-parser gemma4 \
--enable-auto-tool-choice \
--tool-call-parser gemma4 \
--chat-template /app/vllm/examples/tool_chat_template_gemma4.jinja \
--max-num-batched-tokens 16384 \
--max-model-len 32768 \
--speculative-config '{"model":"google/gemma-4-26B-A4B-it-assistant","num_speculative_tokens":4}'
VLLM_USE_V2_MODEL_RUNNER=1 \
vllm serve google/gemma-4-26B-A4B-it \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --language-model-only \
  --reasoning-parser gemma4 \
  --enable-auto-tool-choice \
  --tool-call-parser gemma4 \
  --chat-template /app/vllm/examples/tool_chat_template_gemma4.jinja \
  --max-num-batched-tokens 16384 \
--max-model-len 32768 \
--gpu-memory-utilization 0.8 \
--speculative-config '{"model":"RedHatAI/gemma-4-26B-A4B-it-speculator.eagle3","num_speculative_tokens":1,"method":"eagle3"}'
VLLM_USE_V2_MODEL_RUNNER=1 \
vllm serve google/gemma-4-26B-A4B-it \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --attention-backend triton_attn \
  --language-model-only \
  --reasoning-parser gemma4 \
  --enable-auto-tool-choice \
  --tool-call-parser gemma4 \
  --chat-template /app/vllm/examples/tool_chat_template_gemma4.jinja \
  --max-num-batched-tokens 16384 \
  --max-model-len 32768 \
  --gpu-memory-utilization 0.8 \
  --speculative-config '{"method":"dflash","model":"z-lab/gemma-4-26B-A4B-it-DFlash","num_speculative_tokens":15,"attention_backend":"triton_attn"}'
vllm serve google/gemma-4-31B-it \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --language-model-only \
  --reasoning-parser gemma4 \
  --enable-auto-tool-choice \
  --tool-call-parser gemma4 \
  --chat-template /app/vllm/examples/tool_chat_template_gemma4.jinja \
  --max-num-batched-tokens 16384 \
  --max-model-len 32768
vllm serve google/gemma-4-31B-it \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --language-model-only \
  --reasoning-parser gemma4 \
  --enable-auto-tool-choice \
  --tool-call-parser gemma4 \
  --chat-template /app/vllm/examples/tool_chat_template_gemma4.jinja \
  --max-num-batched-tokens 16384 \
  --max-model-len 32768 \
  --speculative-config '{"model":"google/gemma-4-31B-it-assistant","num_speculative_tokens":1}'
vllm serve google/gemma-4-31B-it \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --language-model-only \
  --reasoning-parser gemma4 \
  --enable-auto-tool-choice \
  --tool-call-parser gemma4 \
  --max-num-batched-tokens 16384 \
  --max-model-len 32768 \
  --speculative-config '{"model":"RedHatAI/gemma-4-31B-it-speculator.eagle3","num_speculative_tokens":3,"method":"eagle3"}'
vllm serve google/gemma-4-31B-it \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --attention-backend triton_attn \
  --language-model-only \
  --reasoning-parser gemma4 \
  --enable-auto-tool-choice \
  --tool-call-parser gemma4 \
  --max-num-batched-tokens 16384 \
  --max-model-len 32768 \
  --gpu-memory-utilization 0.85 \
  --speculative-config '{"method":"dflash","model":"z-lab/gemma-4-31B-it-DFlash","num_speculative_tokens":15,"attention_backend":"triton_attn"}'
vllm serve google/gemma-4-31B-it \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --attention-backend triton_attn \
  --language-model-only \
  --reasoning-parser gemma4 \
  --enable-auto-tool-choice \
  --tool-call-parser gemma4 \
  --max-num-batched-tokens 16384 \
  --max-model-len 32768 \
  --gpu-memory-utilization 0.85 \
  --speculative-config '{"model":"RedHatAI/gemma-4-31B-it-speculator.dspark","num_speculative_tokens":7,"method":"dspark","attention_backend":"triton_attn"}'
vllm serve Qwen/Qwen3-8B \
  --trust-remote-code \
  --max-model-len 4096 \
  --gpu-memory-utilization 0.85
vllm serve Qwen/Qwen3-8B \
  --trust-remote-code \
  --max-model-len 4096 \
  --gpu-memory-utilization 0.85 \
  --speculative-config '{"model":"RedHatAI/Qwen3-8B-Thinking-speculator.eagle3","num_speculative_tokens":5,"method":"eagle3"}'
vllm serve Qwen/Qwen3-8B \
  --trust-remote-code \
  --max-num-batched-tokens 16384 \
  --max-model-len 4096 \
  --gpu-memory-utilization 0.85 \
  --speculative-config '{"model":"z-lab/Qwen3-8B-DFlash-b16","method":"dflash","num_speculative_tokens":7}'
vllm serve Qwen/Qwen3-8B \
  --trust-remote-code \
  --max-num-batched-tokens 16384 \
  --max-model-len 4096 \
  --gpu-memory-utilization 0.85 \
  --speculative-config '{"model":"deepseek-ai/dspark_qwen3_8b_block7","method":"dspark","num_speculative_tokens":11}'
vllm serve Qwen/Qwen3.5-27B \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --max-num-batched-tokens 32768
vllm serve Qwen/Qwen3.5-27B \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --max-num-batched-tokens 32768 \
  --speculative-config '{"method":"mtp","num_speculative_tokens":1}'
vllm serve Qwen/Qwen3.5-27B \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --max-num-batched-tokens 32768 \
  --speculative-config '{"method":"dflash","model":"z-lab/Qwen3.5-27B-DFlash","num_speculative_tokens":15}'
vllm serve Qwen/Qwen3.5-122B-A10B \
  --trust-remote-code \
  --tensor-parallel-size 4 \
  --max-num-batched-tokens 32768
vllm serve Qwen/Qwen3.5-122B-A10B \
  --trust-remote-code \
  --tensor-parallel-size 4 \
  --max-num-batched-tokens 32768 \
  --speculative-config '{"method":"mtp","num_speculative_tokens":7}'
vllm serve Qwen/Qwen3.5-122B-A10B \
  --trust-remote-code \
  --tensor-parallel-size 4 \
  --max-num-batched-tokens 32768 \
  --speculative-config '{"method":"dflash","model":"z-lab/Qwen3.5-122B-A10B-DFlash","num_speculative_tokens":15}'
VLLM_USE_V2_MODEL_RUNNER=1 \
vllm serve Qwen/Qwen3.6-27B \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --max-num-batched-tokens 32768
VLLM_USE_V2_MODEL_RUNNER=1 \
vllm serve Qwen/Qwen3.6-27B \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --max-num-batched-tokens 32768 \
  --speculative-config '{"method":"mtp","num_speculative_tokens":3}'
VLLM_USE_V2_MODEL_RUNNER=1 \
vllm serve Qwen/Qwen3.6-27B \
  --tensor-parallel-size 2 \
  --max-num-batched-tokens 32768 \
  --speculative-config '{"method":"dflash","model":"z-lab/Qwen3.6-27B-DFlash","num_speculative_tokens":15}'
VLLM_ROCM_USE_AITER=1 \
vllm serve Qwen/Qwen3.6-35B-A3B \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --reasoning-parser qwen3 \
  --enable-auto-tool-choice \
  --tool-call-parser qwen3_xml \
  --mm-encoder-tp-mode data \
  --max-num-batched-tokens 16384
VLLM_ROCM_USE_AITER=1 \
vllm serve Qwen/Qwen3.6-35B-A3B \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --reasoning-parser qwen3 \
  --enable-auto-tool-choice \
  --tool-call-parser qwen3_xml \
  --mm-encoder-tp-mode data \
  --max-num-batched-tokens 16384 \
  --speculative-config '{"method":"mtp","num_speculative_tokens":3,"moe_backend":"triton"}'
VLLM_ROCM_USE_AITER=1 \
vllm serve Qwen/Qwen3.6-35B-A3B \
  --trust-remote-code \
  --tensor-parallel-size 2 \
  --reasoning-parser qwen3 \
  --enable-auto-tool-choice \
  --tool-call-parser qwen3_xml \
  --mm-encoder-tp-mode data \
  --max-num-batched-tokens 16384 \
  --speculative-config '{"method":"dflash","model":"z-lab/Qwen3.6-35B-A3B-DFlash","num_speculative_tokens":15}'
VLLM_ROCM_USE_AITER=1 \
VLLM_ROCM_QUICK_REDUCE_QUANTIZATION=INT4 \
vllm serve moonshotai/Kimi-K2.5 \
  --trust-remote-code \
  --tensor-parallel-size 4 \
  --language-model-only \
  --reasoning-parser kimi_k2 \
  --enable-auto-tool-choice \
  --tool-call-parser kimi_k2
VLLM_ROCM_USE_AITER=1 \
VLLM_ROCM_QUICK_REDUCE_QUANTIZATION=INT4 \
vllm serve moonshotai/Kimi-K2.5 \
  --trust-remote-code \
  --tensor-parallel-size 4 \
  --language-model-only \
  --reasoning-parser kimi_k2 \
  --enable-auto-tool-choice \
  --tool-call-parser kimi_k2 \
  --speculative-config '{"model":"lightseekorg/kimi-k2.5-eagle3-mla","method":"eagle3","num_speculative_tokens":3}'
VLLM_ROCM_USE_AITER=1 \
VLLM_ROCM_QUICK_REDUCE_QUANTIZATION=INT4 \
vllm serve moonshotai/Kimi-K2.5 \
  --trust-remote-code \
  --tensor-parallel-size 4 \
  --language-model-only \
  --reasoning-parser kimi_k2 \
  --enable-auto-tool-choice \
  --tool-call-parser kimi_k2 \
  --speculative-config '{"model":"z-lab/Kimi-K2.5-DFlash","method":"dflash","num_speculative_tokens":7}'
VLLM_ROCM_USE_AITER=1 \
VLLM_ROCM_USE_AITER_FUSION_SHARED_EXPERTS=1 \
VLLM_ROCM_QUICK_REDUCE_QUANTIZATION=INT4 \
VLLM_USE_BREAKABLE_CUDAGRAPH=0 \
VLLM_ROCM_USE_AITER_MOE=1 \
vllm serve MiniMaxAI/MiniMax-M3-MXFP8 \
  --tensor-parallel-size 8 \
  --block-size 128 \
  --attention_config.indexer_kv_dtype fp8 \
  --linear-backend emulation \
  --attention-backend TRITON_ATTN \
  --language-model-only \
  --reasoning-parser minimax_m3 \
  --enable-auto-tool-choice \
  --tool-call-parser minimax_m3
VLLM_ROCM_USE_AITER=1 \
VLLM_ROCM_USE_AITER_FUSION_SHARED_EXPERTS=1 \
VLLM_ROCM_QUICK_REDUCE_QUANTIZATION=INT4 \
VLLM_USE_BREAKABLE_CUDAGRAPH=0 \
VLLM_ROCM_USE_AITER_MOE=1 \
vllm serve MiniMaxAI/MiniMax-M3-MXFP8 \
  --tensor-parallel-size 8 \
  --block-size 128 \
  --attention_config.indexer_kv_dtype fp8 \
  --linear-backend emulation \
  --attention-backend TRITON_ATTN \
  --language-model-only \
  --reasoning-parser minimax_m3 \
  --enable-auto-tool-choice \
  --tool-call-parser minimax_m3 \
  --speculative-config '{"method":"eagle3","model":"Inferact/MiniMax-M3-EAGLE3","num_speculative_tokens":3,"attention_backend":"TRITON_ATTN"}'
Acknowledgements
We would like to thank everyone who contributed to this collaboration, including Hongxia Yang and Peng Sun from AMD, and Pin Siang Tan, Jun Kang Chow, and Ye Hur Cheong from Embedded LLM.
Disclaimer
Measurements were run on AMD Instinct™ MI300X and MI355X platforms using the configurations below.
Hardware Configuration
- Hardware 1: 8× AMD Instinct™ MI300X GPUs (gfx942) with 2× AMD EPYC™ 9654 96-Core Processor.
- Hardware 2: 8× AMD Instinct™ MI355X GPUs (gfx950) with 2× AMD EPYC™ 9575F 64-Core processors. This platform was used for the MiniMax-M3-MXFP8 experiment.
Software Configuration
Ubuntu 22.04.5 LTS, ROCm/HIP runtime 7.2.53211, vLLM 0.23.1rc1.dev1120+g0f0f28b53, PyTorch 2.11.0+gitd0c8b1f, Transformers 5.13.1, Python 3.12.13.
Server manufacturers may vary configurations, yielding different results. Performance may vary based on configuration, software, vLLM version, and the use of the latest drivers and optimizations.