要点速览
- hybrid 模型(如 Nemotron-H)的 FA 层与 Mamba 层状态布局、大小完全不同,原有单一 KV cache 描述符方案无法复用。
- 核心方案:双描述符视图(FA/Mamba 各一套索引同一物理内存)、物理/逻辑块桥接、DS 布局下的 3 描述符 conv 传输。
- DS 布局使 conv 的 x/B/C 子投影内存连续,异构 TP 下每个 D rank 用连续 RDMA 读取自己的分片,无暂存缓冲、无传输后重排。
- Mamba 描述符按真实 conv+SSM 字节注册而非 HMA padding 后的页大小,bf16 下每请求省约 50 MB 传输。
- 8x H200 实测:高并发下分离式 PD 对 co-located Pareto 占优;功能需 vllm>=v0.20.0,目前仅支持 Mamba2。
解决什么问题
vLLM 已通过 NIXL KV connector 支持标准 transformer 的 prefill/decode 分离,但 hybrid SSM-FA 模型(如 Nemotron-H)里 FA 层与 SSM 层存储的状态在布局、大小上完全不同,而 block manager 与 NIXL connector 原本围绕单一均匀的 KV cache 格式设计。加之 HMA 把两类层的内存池化到同一物理张量并用 padding 对齐页大小,单一 (address, length) 描述符列表无法同时正确索引两种视图。本文解决如何在共享物理内存的前提下完成正确的描述符映射,并支持异构 TP(D TP != P TP)下的 Mamba 状态分片传输。
核心思路
在同一物理 KV cache 内存上注册两套拼接的 NIXL 描述符列表(FA 与 Mamba),由单一传输句柄指向:FA 段用 N_phys 块、Mamba 段用 N_logical 块并加 num_descs 偏移,映射时按组类型选择步长。针对 attention kernel 要求的物理块大小,只在 FA 层应用 logical/physical ratio 换算,SSM 层没有 token 维度、始终直接用逻辑块。对 Mamba conv state 强制 DS (dim, state_len) 布局,使 x/B/C 子投影各自连续,异构 TP 下每个 D rank 用三段连续 RDMA 读精确取回自己的分片。描述符按真实 conv+SSM 字节注册而非 HMA 填充后的页大小,避免传输 padding。全部改动是纯增量扩展,仅在模型含 SSM 层时激活,不影响标准 transformer 的既有流程。
关键要点
- NIXL PD 分离的标准工作流 — 分四个阶段:各 worker 向 NIXL 注册 KV cache 内存区域以便 RDMA 访问;为每个区域创建 (address, length, device_id) 的 per-block descriptor,块是传输的基本单位;P-D 首次配对时 handshake 交换 agent handle、块数、块长等元数据(每对只做一次);调度器告知 D 要拉哪些块,D 将 block_id 映射为 descriptor_id 后发起 RDMA READ 并轮询完成。标准模型中区域 r 的块 b 映射到 descriptor 索引 r * N + b,而 hybrid 模型下这种均匀方案不再成立。
- FA 与 SSM 状态的本质差异 — 标准 transformer 每层 KV cache 形状一致,如 [num_blocks, 2, block_size, num_kv_heads, head_dim],所有层共享同一 block size、page size 与块数。Mamba 层维护的却是 collapsed conv state(如 (3072, 3) bf16)与 temporal SSM state(如 (32, 64, 128) fp32):它们没有 token 概念,是整个序列历史的固定大小摘要。因此 SSM 的 block_size 实际为 1——每个块是一份完整状态快照,而不是一组 per-token 向量。
- HMA 共享张量布局带来的冲突 — vLLM 的 Hybrid Memory Allocator(HMA)按层类型分组(所有 FA 层一组、所有 SSM 层一组)并跨组池化内存,使各组相同位置的层共享同一物理张量,块可互换。HMA 会增大 FA block_size 直到超过 Mamba 所需,再 pad Mamba 行,使两组页大小(字节数)相等。结果是同一张量同时被看作 FA 块和 SSM 块,而 FA 描述符指向 base + b * page_size 且长度为 fa_block_len,Mamba 描述符指向同一地址但长度是 conv_size 或 ssm_size——单一描述符列表无法同时表达,异构 TP 下 K/V 还需分开注册以便分别索引。
- 双描述符视图 — 在同一物理内存上注册两套拼接的描述符列表,由单个 NIXL 传输句柄指向:FA 描述符(按 K、V 分别索引)占前 num_descs = M * N_phys 槽位,Mamba 描述符紧随其后。映射规则:FA 组用 desc_id = region_id * N_phys + block_id;Mamba 组用 desc_id = mamba_region_id * N_log + block_id + num_descs。对同构 TP,Mamba 段简化为 Conv、SSM 两个子区域;异构 TP 下展开为 x、B、C、SSM 四个子区域。
- 物理块与逻辑块的桥接 — FlashInfer 等 attention 后端要求特定物理块大小(如 16 token),可能与用户设定或 HMA 计算的逻辑块大小不同。标准模型用 ratio = logical_block_size / kernel_block_size 换算;hybrid 模型中该 ratio 只作用于 FA 层——SSM 层没有可切分的 token 维度,始终直接使用 logical blocks。因此描述符列表两段的块数不同(FA 段 M * N_phys,Mamba 段 M * N_logical),由 _physical_blocks_per_logical 字段按引擎分别计算(P 与 D 的 TP 大小不同时 ratio 也不同),_get_block_descs_ids 依组类型选择相应步长。
- 3 描述符 conv 传输与 DS 布局 — 同构 TP(P、D 用相同 --tensor-parallel-size)时每个 D rank 直接从对应 P rank 读取 conv+SSM 块;异构 TP(如 P_TP=1、D_TP=4)时四个 D worker 要各自从单个 P worker 读自己的分片。SSM temporal state 沿 heads 维(第一轴)分片,切片平凡;但 conv state 结构为 [x | B | C],在标准 SD 布局 (state_len, dim) 下这些子投影在内存中交错,取非连续字节对零拷贝 RDMA 不可行。方案是强制 DS 布局 (dim, state_len)(经 VLLM_SSM_CONV_STATE_LAYOUT=DS 开启),使 x、B、C 各自连续,每个 D rank 用三段连续 RDMA 读取自己的分片(仍只发一次 NIXL READ);remote_conv_offsets 方法按 TP 比例计算各 D rank 分片在 P 页内的位置。代价是描述符列表更大(每 Mamba 层 4 个区域),但 RDMA 传输本身仍是高效的连续读。
- 零开销设计:不传多余字节 — 替代方案是把整个 conv state 传给每个 D rank 再本地 permute/slice,但本文刻意避免:不分配暂存缓冲——否则每个 D worker 都要为 P 的完整 conv state 分配临时缓冲(Nemotron-H 每块 conv state 就有 3 * 3072 * 2 字节 bf16,乘以数千块与所有 Mamba 层会蚕食 KV cache 空间);无传输后重排——数据直接落入 KV cache 的最终位置,传输完成即可用;只传自己拥有的份额——每个 D rank 只传 1/TP(D_TP=4 时每 rank 数据量是“全传再本地切片”方案的 1/4);跳过 HMA padding——Mamba 描述符按真实 conv_bytes + ssm_bytes 而非 padded page 注册,FA 页远大于原始 SSM 状态时可显著减少每块传输量。作者还指出常规 colocated 场景用 DS 布局未测出 kernel 性能回退,未来可能把 DS 设为默认。
- 端到端示例、性能与限制 — 以 NVIDIA-Nemotron-3-Nano-30B-A3B-FP8 TP=2 分离式 PD 为例:52 层交替 Mamba/FA,HMA 分成 5 组(4 Mamba + 1 FA),池化后 6 个共享 KV cache 张量;FA 布局为 [num_blocks, 2, block_size=400, 4, 128],SSM 为 conv [num_blocks, 3, 3072] + ssm [num_blocks, 48, 64, 128]。传输时 D 用一次 make_prepped_xfer READ 同时携带 FA 与 Mamba 描述符,完成后通知 P 释放块。8x H200(NVLink)上对 Nemotron-3-Super-120B-A12B-FP8 基准:TP=8 co-located 对比 TP=4 prefill + TP=4 decode,ShareGPT 负载、并发 8–256、prefix caching 关闭,高并发下分离式 PD Pareto 占优。限制:仅支持 Mamba2(Mamba1 的 SSM temporal 形状无法重建 conv 分解所需的 intermediate_size)、GDN(Qwen3.5+)在路线图、SSM 传输与 speculative decoding 的交互未充分验证、HMA 下 P/D block_size_ratio > 1 不支持。
关键数据
| 指标 | 数值 | 条件 |
|---|---|---|
| 每请求节省的传输量 | 约 50 MB | Nemotron Super 120B、TP=4、HMA 设定 FA block_size=4224,bf16 KV cache 下对比传输完整 HMA-padded 页的 Naive 基线 |
| 异构 TP 下每 rank 的 conv 传输量 | 仅为“全传再本地切片”方案的 1/4(4x less) | D_TP=4 时每个 D rank 只传自己 1/TP 份额的 conv state |
| 单块 conv state 大小 | 3 * 3072 * 2 bytes(bf16) | Nemotron-H 类模型,用于说明暂存缓冲方案在数千块、所有 Mamba 层上的显存代价 |
| 模型层数与共享张量数 | 52 层、5 组(4 Mamba + 1 FA)、6 个共享 KV cache 张量 | nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-FP8,TP=2 分离式 PD 示例 |
| 并发扫描范围 | 8–256 并发用户 | 8x H200(NVLink)、ShareGPT 负载、Nemotron-3-Super-120B-A12B-FP8,TP=8 co-located 对比 TP=4 prefill + TP=4 decode |
| 基准硬件 | 8x H200 GPU,经 NVLink 互联 | 分离式 PD 与 co-located serving 的对比实验环境 |
| 功能最低版本 | vllm>=v0.20.0 | hybrid SSM 模型的分离式 PD 支持 |
“We then show the savings on a **bf16** setup, where our approach eliminates ~50 MB of unnecessary transfer per request.”
“Each D rank transfers only its `1/TP` share of the conv state, not the full state. For `D_TP=4`, this means 4x less data per rank compared to the "transfer everything, slice locally" approach.”
“With models like Nemotron-H, conv state per block is already significant (`3 * 3072 * 2 bytes` in bf16).”
前置知识
vLLM prefill/decode 分离(PD disaggregation)的基本概念与收益 · NIXL KV connector 的工作方式:内存注册、block descriptor、handshake、RDMA READ · Mamba/SSM 模型基础:conv state 与 temporal SSM state 的含义 · KV cache 分页管理:block_size、page size、逻辑块与物理块 · tensor parallelism(TP)以及 KV/SSM 状态在 TP 间的分片方式 · RDMA 与零拷贝传输的基本概念
术语表
hybrid SSM: 交替堆叠 Mamba 风格 SSM 层与标准全注意力(FA)层的混合架构,如 NVIDIA Nemotron-H,结合 SSM 的线性时间效率与 attention 的表达能力。NIXL: 跨节点内存传输库,vLLM 用它实现 PD 分离时 KV cache 的 RDMA 拉取,block descriptor 是其传输的基本单位。HMA (Hybrid Memory Allocator): vLLM 的混合内存分配器,按层类型分组并跨组池化内存,使各组相同位置的层共享同一物理张量,并通过 padding 使各组页大小(字节数)相等。conv state: Mamba 层的卷积状态,形状如 (conv_dim, state_len),是序列历史的固定大小摘要之一,与 token 数无关。SSM state: Mamba 层的时间状态,形状如 (num_heads, head_dim, state_size),沿 heads 维(第一轴)做 TP 分片。dual descriptor views: 在同一物理内存上注册两套 NIXL 块描述符(FA 与 Mamba),各自用不同的偏移、长度与步长索引同一块内存。DS layout: conv state 的 (dim, state_len) 内存布局,使 x/B/C 子投影各自连续,支持异构 TP 下的零拷贝分片 RDMA 读取;经 VLLM_SSM_CONV_STATE_LAYOUT=DS 开启。heterogeneous TP: prefill 与 decode 实例使用不同 tensor-parallel size 的部署形态,要求状态传输时按 TP 比例切分与定位。RDMA READ: 远程直接内存访问读操作,由 decode 侧主动从 prefill 侧拉取数据,无需对方 CPU 介入。
Disaggregated Serving for Hybrid SSM Models in vLLM
Introduction
Hybrid architectures that interleave Mamba-style SSM layers with standard full-attention (FA) layers — such as NVIDIA Nemotron-H — are gaining traction as a way to combine the linear-time efficiency of state-space models with the expressiveness of attention. vLLM already supports disaggregated prefill/decode (P/D) for standard transformer models through its NIXL-based KV connector: a prefill instance computes KV cache blocks and a decode instance pulls them over RDMA, eliminating redundant recomputation. But extending this to hybrid models is not straightforward. FA and SSM layers store fundamentally different state, in different layouts and different sizes, yet the block manager and NIXL connector were designed around a single, uniform KV cache format.
In this post we describe how we extended the NIXL connector to support hybrid SSM-FA models in disaggregated mode. The key ideas are:
- Dual descriptor views — two sets of NIXL block descriptors that index the same physical memory regions with different offsets and sizes, one for FA blocks and one for SSM blocks.
- Physical/logical block bridging — handling the mismatch between the logical block abstraction seen by the block manager and the physical block sizes required by attention kernels.
- 3-descriptor conv transfer — a decomposition of the Mamba conv state that enables heterogeneous tensor-parallel transfers without reshuffling data on the sender side.
None of these changes modify the existing workflow for standard transformer models. They are purely additive extensions that activate only when the model contains SSM layers.
This feature is available with vllm>=v0.20.0.
This work builds on the HMA interface for NIXL and spans several PRs:
- #36687 — Dual descriptor views and homogeneous-TP support for hybrid SSM-FA models
- #37416 — DS conv state layout for Mamba kernels
- #37635 — Heterogeneous-TP 3-descriptor conv state transfer
- #37310 — N-1 prefill for Mamba P/D disaggregation
Background: The NIXL KV Transfer Workflow
Before diving into the hybrid-model changes, let us briefly recap how NIXL disaggregated P/D works for a standard transformer.
The workflow has four phases:
- Register memory regions — Each worker registers its KV cache tensors with NIXL so they can be accessed via RDMA.
- Create block descriptors — For each registered region, we create per-block descriptors that specify
(address, length, device_id). These descriptors are our unit of transfer: rather than moving entire regions, we transfer individual blocks. - Handshake — When a decode (D) worker first needs to pull from a prefill (P) worker, the two exchange metadata: agent handles, block counts, block lengths, and so on. This is done once per P-D pair.
- Transfer — The scheduler tells D which blocks to pull from P. D maps
block_id -> descriptor_id, issues an RDMA READ, and polls for completion.
For a standard model with M registered regions and N blocks, the descriptor list looks like:
+----------------------------------+
| Region 0: desc_0 ... desc_{N-1}  |
| Region 1: desc_0 ... desc_{N-1}  |
| ...                              |
| Region M: desc_0 ... desc_{N-1}  |
+----------------------------------+
A block ID b in region r maps to descriptor index r * N + b.
The challenge with hybrid models is that this uniform scheme does not hold: FA layers and SSM layers need different descriptor sizes and different block counts.
The Challenge: FA and SSM State Are Fundamentally Different
In a standard transformer, every layer's KV cache has the same shape: [num_blocks, 2, block_size, num_kv_heads, head_dim] (or a layout variant). All layers share the same block size, same page size, and same number of blocks.
Mamba layers store something very different. Instead of per-token K/V pairs, they maintain a collapsed conv state and a temporal SSM state:
Conv state:  (conv_dim, state_len)    e.g. (3072, 3)   -- bf16
SSM state:   (num_heads, head_dim, state_size)   e.g. (32, 64, 128) -- fp32
There is no concept of "tokens" in these states — they are a fixed-size summary of the entire sequence history. This means block_size for SSM is effectively 1: each block is a complete state snapshot, not a group of per-token vectors.
Remember: a block is the single unit of transfer here.
The HMA Shared-Tensor Layout
vLLM's Hybrid Memory Allocator (HMA) groups layers by type: all FA layers in one group, all SSM layers in another, and so on. It then pools memory across groups so that layers at the same position in each group share the same physical tensor. This is efficient (blocks are interchangeable), but it means the same tensor is simultaneously viewed as FA blocks by one group and as SSM blocks by another.
Here is the resulting layout for a model like Nemotron-H:
                KV Cache Tensor (shared via HMA pooling)
                 /                        \
                /                          \
     Attention (FA) View              Mamba View
              |                            |
    +-----------------------+    +-----------------------+
    | Block 0               |    | Block 0               |
    |   Key     |  Value    |    |  Conv |    SSM  |[pad]|
    | Block 1               |    | Block 1               |
    |   Key     |  Value    |    |  Conv |    SSM  |[pad]|
    |  ...                  |    |  ...                  |
    +-----------------------+    +-----------------------+
The page sizes differ: FA pages are governed by block_size * num_kv_heads * head_dim (*2 for K/V), while SSM pages are conv_state_bytes + ssm_state_bytes.
HMA bumps FA block_size until it's bigger than Mamba's, then pads the Mamba rows (+[pad]) so both groups have equal page sizes in bytes, enabling the shared-tensor scheme.
The problem for NIXL: a single descriptor list with uniform (address, length) entries cannot correctly index both views. We need to register K/V (and similary Conv/SSM) on separate descs to allow indexing K/Vs heads on heterogeneous setups (that is when D TP != P TP).
An FA descriptor for block b points at base + b * page_size with length fa_block_len. A Mamba descriptor for the same block b points at the same base + b * page_size with length conv_size or ssm_size. These differ.
Dual Descriptor Views
Our solution is to register two separate descriptor lists over the same physical memory, concatenated and pointed by a single NIXL transfer handle:
+------------------------------------------------------+
|  FA descriptors (M regions x N_phys blocks)          |
|                                                      |
|  Region 0                                            |
|    FA_desc_K[0], FA_desc_K[1], ... FA_desc_K[N-1]    |
|    FA_desc_V[0], FA_desc_V[1], ... FA_desc_V[N-1]    |
|  Region 1                                            |
|    ...                                               |
|  Region M                                            |
|    ...                                               |
|                                                      |   ^
|  --------------------------------------------------- |   | num_descs
|                                                      |   v
|  Mamba descriptors (M regions x N_log blocks)        |
|                                                      |
|  Region 0                                            |
|    Mamba_desc_x[0]   ... Mamba_desc_x[N-1]           |
|    Mamba_desc_B[0]   ... Mamba_desc_B[N-1]           |
|    Mamba_desc_C[0]   ... Mamba_desc_C[N-1]           |
|    Mamba_desc_SSM[0] ... Mamba_desc_SSM[N-1]         |
|  Region 1                                            |
|    ...                                               |
|  Region M                                            |
|    ...                                               |
+------------------------------------------------------+
Note: Mind that we're using
N_phys/_logto indicate physical and logical blocks respectively. You can assumeN_phys=N_log=Nand refer to the next section for when that's not the case.Note: the Mamba section above already reflects the conv-state decomposition into x, B, C sub-projections, explained in The 3-Descriptor Conv Transfer below. For homogeneous TP, these simplify to two sub-regions (Conv, SSM).
The FA descriptors occupy the first num_descs = M * N_phys slots. The Mamba descriptors follow immediately after. Block ID mapping becomes:
if is_fa_group:
    desc_id = region_id * N_phys + block_id
else:  # mamba group
    desc_id = mamba_region_id * N_log + block_id + num_descs
Physical vs. Logical Block Sizes
A second complication arises from attention kernel requirements. Backends like FlashInfer require a specific physical block size (e.g., 16 tokens) that may differ from the logical block size set by the user or computed by HMA.
For standard models, this is handled by a simple ratio:
physical_blocks = logical_blocks * ratio
ratio = logical_block_size / kernel_block_size
For hybrid models, this ratio applies only to FA layers. SSM layers have no "token" dimension to split, so they always use logical_blocks directly. This means the FA and Mamba sections of the descriptor list use different block counts:
FA section:    M regions * N_phys blocks    (N_phys = N_logical * ratio)
Mamba section: M regions * N_logical blocks
This is tracked via the _physical_blocks_per_logical field, which is computed per-engine (since P and D may have different ratios when their TP sizes differ). The block-ID-to-descriptor-ID mapping in _get_block_descs_ids uses the appropriate stride depending on whether it is resolving an FA group or a Mamba group.
The 3-Descriptors Conv Transfer
For homogeneous TP (P and D use the same --tensor-parallel-size), transferring SSM state is straightforward: each D rank reads the corresponding conv + SSM block from the matching P rank.
Heterogeneous TP makes this harder. Consider P_TP=1, D_TP=4: four D workers must each read their shard of the conv and SSM state from a single P worker. The SSM temporal state is sharded along the heads dimension, which is the first axis — so slicing is trivial. But the conv state is structured as:
Conv state = [x | B | C]     where x, B, C are sub-projections
              ^   ^   ^
              |   |   |
     intermediate_size / TP   groups_ss / TP   groups_ss / TP
With the standard SD layout (state_len, dim), these sub-projections are interleaved in memory. A D worker wanting only its portion of x would need to gather non-contiguous bytes — impractical for zero-copy RDMA.
The DS Layout Solution
We require the DS layout (dim, state_len) for conv state (set via VLLM_SSM_CONV_STATE_LAYOUT=DS). In this layout, each sub-projection's data is contiguous in memory:
DS layout within one page:

|--- x (x_bytes) ---|--- B (b_bytes) ---|--- C (b_bytes) ---|--- SSM ---|
Each D rank can now read its slice of x, B, and C with three separate, contiguous RDMA reads — hence "3-descriptor transfer" (we still only issue one NIXL READ).
For heterogeneous TP, the remote_conv_offsets method computes where each D rank's slice lives within the P page, accounting for the TP ratio.
This gives us 4 descriptor regions per Mamba layer (x, B, C, SSM) instead of the 2 regions (Conv, SSM) used in the homogeneous case. The trade-off is a larger descriptor list, but the RDMA transfers themselves remain efficient contiguous reads.
No extra in-memory staging buffer is allocated on either GPU. No data reshuffling is needed on either side.
Note: We have not measured noticeable regressions in kernel performance when using the DS layout for regular colocated setups. We may update the standard layout to be DS at all times in future versions.
Zero-Overhead: No Extra Buffers, No Permutation
A simpler alternative would be to transfer the entire conv state to each D rank and then permute/slice it locally into the right shape. But for Mamba, we deliberately avoid this approach:
- No staging buffer — Permuting on D would require allocating a temporary buffer the size of P's full conv state on every D worker. With models like Nemotron-H, conv state per block is already significant (
3 * 3072 * 2 bytesin bf16). Multiplied across thousands of blocks and all Mamba layers, this overhead adds up and chips space that could be used for KV cache. - No post-transfer reshuffling — With the DS layout, each D rank reads exactly the bytes it needs, directly into their final destination in the KV cache. There is no post-transfer kernel to rearrange data. The transfer completes and the state is immediately usable.
- Transfer only what you own — Each D rank transfers only its
1/TPshare of the conv state, not the full state. ForD_TP=4, this means 4x less data per rank compared to the "transfer everything, slice locally" approach. - Skip HMA padding — Recall that HMA pads SSM pages so they match FA page sizes. The Mamba descriptors are sized to the actual
conv_bytes + ssm_bytes, not the padded page size. This means we never transfer the padding bytes over the wire — only the real state. For models where the padding is substantial (e.g., when FA page sizes are much larger than the raw SSM state), this can meaningfully reduce transfer volume per block.
The figure below validates the zero-overhead transfer optimizations on Nemotron Super 120B at TP=4 (FA block_size=4224, as set by HMA). For each KV cache dtype (bf16 and fp8), we compare a Naive baseline - which transfers full HMA-padded pages for Mamba blocks - against Optimal approach which transfers only the actual conv + SSM bytes, skipping all HMA padding and/or auxiliary buffers. We first validate that our approach matches Optimal as reported by transfer metrics.
For fp8, the FA page size is smaller (1 byte per element vs 2), so the padding is negligible in this configuration. We then show the savings on a bf16 setup, where our approach eliminates ~50 MB of unnecessary transfer per request.
Since Mamba state is a fixed-size per-request summary, transfer size scales with the number of FA blocks as ISL increases.
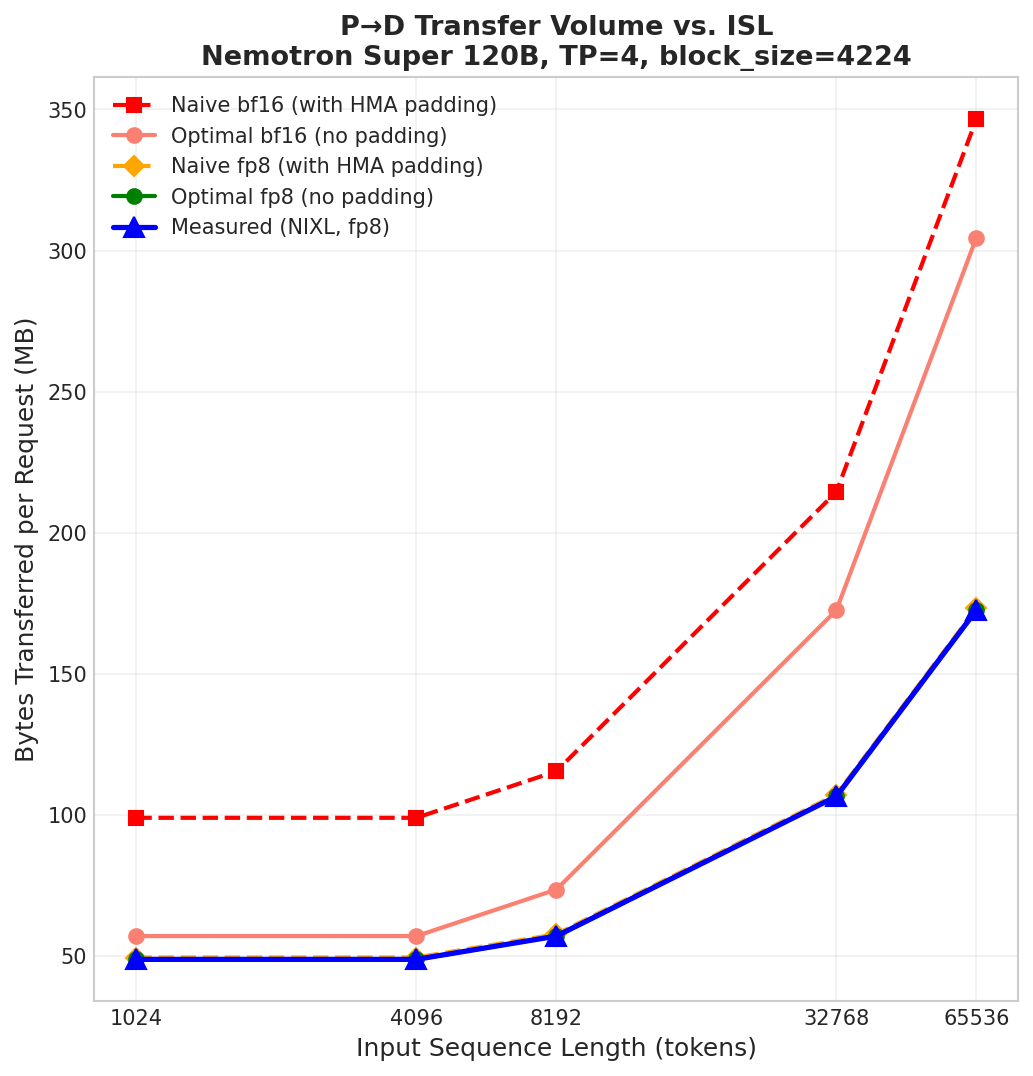
Figure 1: P→D transfer volume vs. input sequence length for Nemotron Super 120B (TP=4, FA block_size=4224). The Naive and Optimal baselines are computed analytically from the model's page sizes and block counts. The Measured line reports the actual bytes transferred (as reported by NIXL) during disaggregated P/D serving. Our approach (Optimal) eliminates HMA padding overhead, which is reflected in the measured transfer.
Putting It Together: Nemotron-H Example
Let us walk through a concrete example: serving nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-FP8 with disaggregated P/D at TP=2.
Model structure: 52 layers total, alternating between Mamba and FA. HMA groups them into 5 groups (4 Mamba, 1 FA). After memory pooling, this yields 6 shared KV cache tensors.
KV cache layout:
FA layers:    [num_blocks, 2, block_size=400, 4, 128]   # K/V with HMA-inflated block_size
SSM layers:   [num_blocks, 3, 3072]  (conv)  +  [num_blocks, 48, 64, 128]  (ssm)
HMA pads the block sizes so both views have the same page size in bytes. The kernel (FlashInfer/FlashAttention) may further subdivide FA blocks, creating a physical/logical ratio.
Descriptor registration:
- The 6 shared tensors are registered as NIXL memory regions (same as dense models).
- FA descriptors are created for all 6 regions x
N_physblocks, indexing K and V separately. - Mamba descriptors are appended: 6 regions x
N_logicalblocks, with 4 sub-regions each (x, B, C, SSM) for the 3-descriptor transfer.
Transfer flow:
- P finishes prefill. The scheduler assigns block IDs per group:
[[fa_block_ids], [mamba_block_ids_g0], [mamba_block_ids_g1], ...]. - D receives the block IDs and maps them to descriptor indices: FA blocks use the standard
region * N + block_idformula; Mamba blocks add thenum_descsoffset and useN_logicalstride. - D issues a single
make_prepped_xferREAD with both FA and Mamba descriptors, then polls for completion. - On completion, D notifies P so it can free the blocks.
The entire transfer is a single async operation from D's perspective. No intermediate buffers, no data reshuffling.
Performance
We benchmark disaggregated P/D against co-located serving on 8x H200 GPUs connected via NVLink. The model is nvidia/NVIDIA-Nemotron-3-Super-120B-A12B-FP8, a recent 120B LatentMoE hybrid architecture with interleaved Mamba2 and full-attention layers.
- Co-located baseline: single instance, TP=8, all 8 GPUs.
- Disaggregated P/D: 1 prefill instance (TP=4, 4 GPUs) + 1 decode instance (TP=4, 4 GPUs), same total GPU count.
We sweep concurrency from 8 to 256 concurrent users and plot output throughput per GPU against per-user output token rate (Interactivity). The workload uses ShareGPT as test dataset.
All runs use a very high warmup value to ensure KV cache gets "scrambled" in order to avoid the initial performance boost you get when request blocks happen to be allocated contiguously. This reflects regular long-running use more accurately. Once can also verify it by checking a constant number of descriptors is reported in the metrics (over a full dataset sweep).
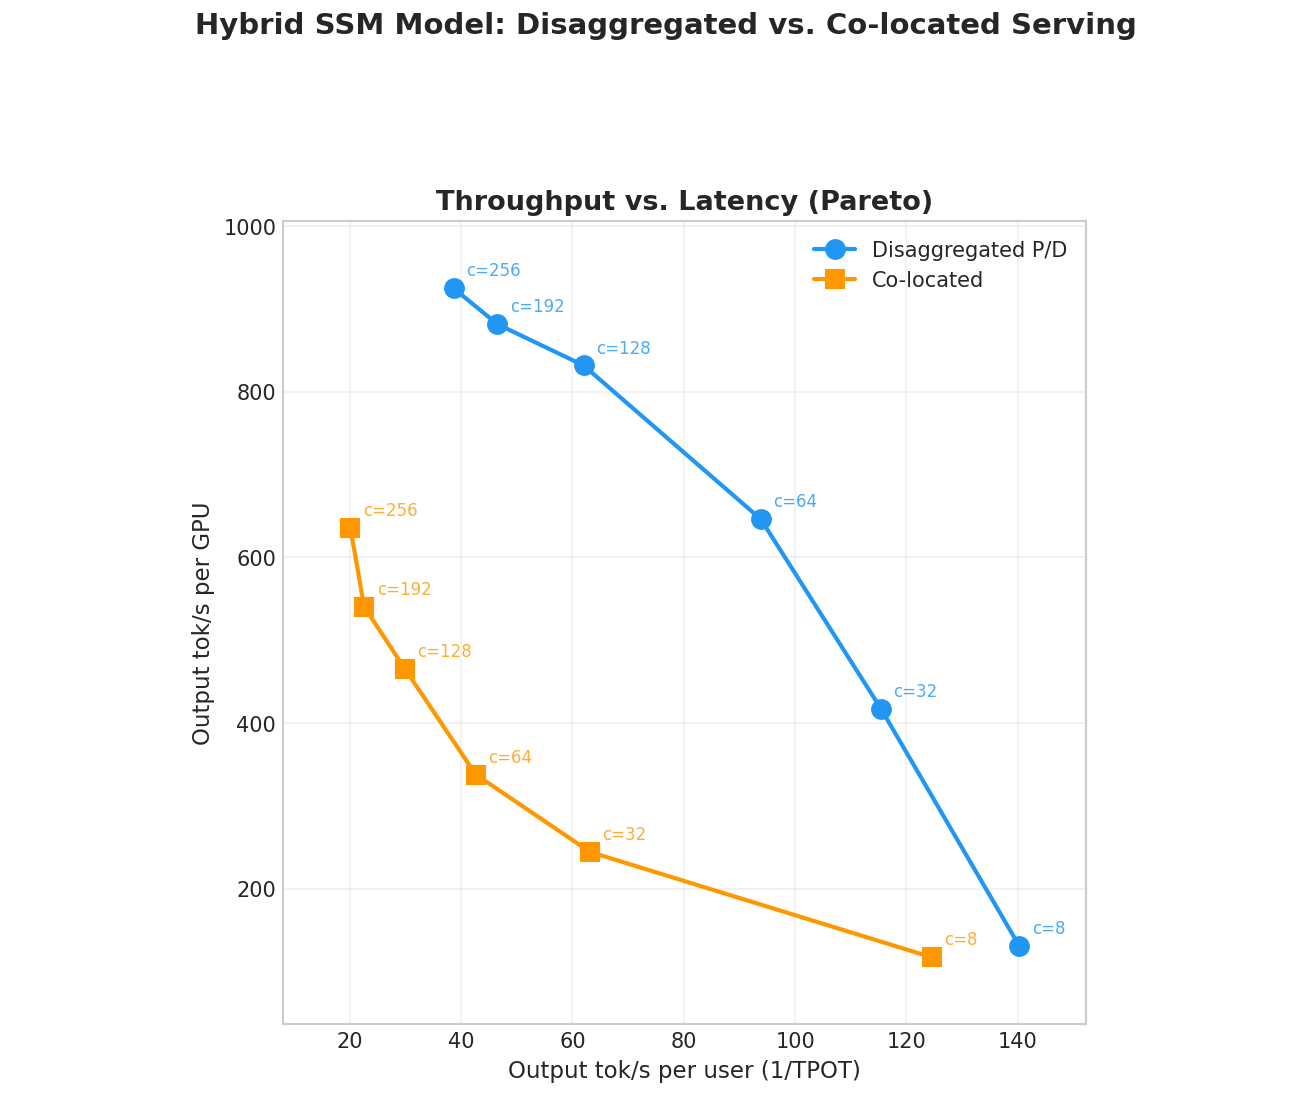
Figure 2: Disaggregated P/D vs. co-located serving for a hybrid SSM model. Throughput-vs-latency Pareto curve across concurrency levels. Prefix-caching disabled.
The results show the same pattern observed with disaggregated serving for standard transformer models: disaggregated P/D Pareto-dominates the co-located baseline at higher batch sizes. By isolating decode from prefill interference, the decode instance can sustain larger batches without stalling, yielding significantly higher output tok/s per GPU at high concurrency.
Getting Started
To run a hybrid SSM model with disaggregated P/D:
# Prefill instance
VLLM_SSM_CONV_STATE_LAYOUT=DS vllm serve nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-FP8 \
    --tensor-parallel-size 2 \
    --gpu-memory-utilization 0.85 \
    --trust-remote-code \
    --max-model-len 8192 \
    --block-size 128 \
    --no-disable-hybrid-kv-cache-manager \
    --kv-transfer-config '{"kv_connector":"NixlConnector","kv_role":"kv_both"}'
Note: DS conv state layout set
VLLM_SSM_CONV_STATE_LAYOUT=DSis required for heterogeneous TP, but not necessary otherwise.
Limitations and Future Work
- Mamba1 models: The 3-descriptor conv transfer currently supports Mamba2 only. Mamba1's SSM temporal shape
(intermediate_size // tp, state_size)does not allow reconstructingintermediate_size, which is needed for the conv decomposition. Similarly, GDN support (Qwen3.5+) is listed in the disaggregated roadmap - Speculative decoding: Interaction between SSM state transfer and speculative decoding has not been extensively validated.
- Mixed block sizes with HMA: Different block sizes between P and D (
block_size_ratio > 1) are not yet supported when HMA is enabled.
Acknowledgments
Thomas Parnell (IBM Research), Roi Koren (NVIDIA)